
What is VideoReward
VideoReward is a video generation preference dataset and reward model jointly created by the Chinese University of Hong Kong, Tsinghua University, Kuaishou Technology, and others. It contains 182,000 annotated data entries, covering three dimensions: visual quality, motion quality, and text alignment, and is used to optimize video generation models. The reward model is based on human feedback and, through multi-dimensional alignment algorithms such as Flow-DPO and Flow-RWR and inference-time techniques such as Flow-NRG, significantly improves the coherence and text alignment of video generation. Flow-NRG supports user-defined weights to meet personalized needs.
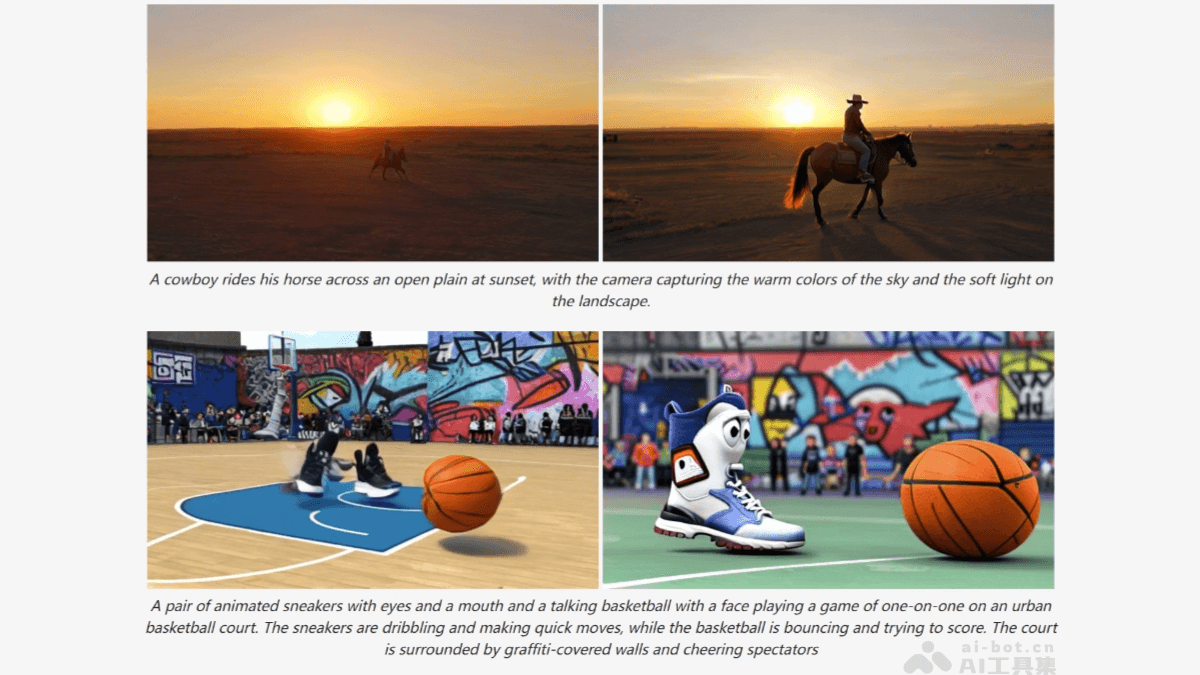
Main Features of VideoReward
- Building a Large-Scale Preference Dataset: VideoReward contains 182,000 annotated data entries, covering three key dimensions: visual quality (VQ), motion quality (MQ), and text alignment (TA), to capture users' preferences for generated videos.
- Multi-Dimensional Reward Model: Based on reinforcement learning, VideoReward introduces three alignment algorithms, including training-time strategies such as Flow-DPO and Flow-RWR and inference-time techniques such as Flow-NRG, to optimize video generation.
- Support for Personalized Needs: Flow-NRG supports users in assigning custom weights to multiple objectives during inference, meeting personalized video quality needs.
- Improving Video Generation Quality: Through human feedback, VideoReward can significantly improve the coherence of video generation and its alignment with prompt text, outperforming existing reward models.
Technical Principles of VideoReward
- Alignment Algorithms: VideoReward introduces three alignment algorithms. These algorithms extend methods from diffusion models and are specifically designed for flow-based models:
- Flow-DPO (Direct Preference Optimization): During the training phase, directly optimize the model to match video pairs preferred by humans.
- Flow-RWR (Reward-Weighted Regression): Optimize the model through reward weighting so that it better conforms to human feedback.
- Flow-NRG (Noise Video Reward Guidance): During the inference phase, directly apply reward guidance to noisy videos, supporting users in assigning custom weights to multiple objectives to meet personalized needs.
- Human Feedback Optimization: Through human feedback, VideoReward can significantly improve the coherence of video generation and its alignment with prompt text. Experimental results show that VideoReward outperforms existing reward models, and Flow-DPO performs better than Flow-RWR and standard supervised fine-tuning methods.
Project Address of VideoReward
- Project Official Website:https://gongyeliu.github.io/videoalign/
- arXiv Technical Paper:https://arxiv.org/pdf/2501.13918
Application Scenarios of VideoReward
- Video Generation Quality Optimization: VideoReward significantly improves the quality of video generation through a large-scale human preference dataset and a multi-dimensional reward model, especially in terms of visual quality, motion coherence, and text alignment.
- Personalized Video Generation: VideoReward's Flow-NRG technology supports users in assigning custom weights to multiple objectives during inference, meeting personalized video quality needs.
- Training and Fine-Tuning of Video Generation Models: The multi-dimensional reward model and alignment algorithms provided by VideoReward, such as Flow-DPO and Flow-RWR, can be used to train and fine-tune video generation models.
- User Preference Analysis and Research: VideoReward's large-scale preference dataset covers multiple dimensions such as visual quality, motion quality, and text alignment.
- Video content creation and editing: In the field of video content creation and editing, VideoReward can help generate higher-quality video materials and improve creation efficiency.