
What is Tencent Hunyuan Text-to-Video
Tencent Hunyuan Text-to-Video is based on TencentAI video generationThe AI video creation tool launched by the model can generate corresponding video content based on text prompts. The model performs excellently in image quality, object motion, shot transitions, etc., can understand and follow complex prompts, and generate videos with a blockbuster feel. In the input box interface, styles, shot sizes, lighting, camera movements, and multiple modes (smooth camera movement, rich actions, director mode) are provided, so even beginners can get started quickly. The Tencent Hunyuan Text-to-Video model can generate multi-shot videos, achieve natural transitions, and also support generating coherent multi-action videos.
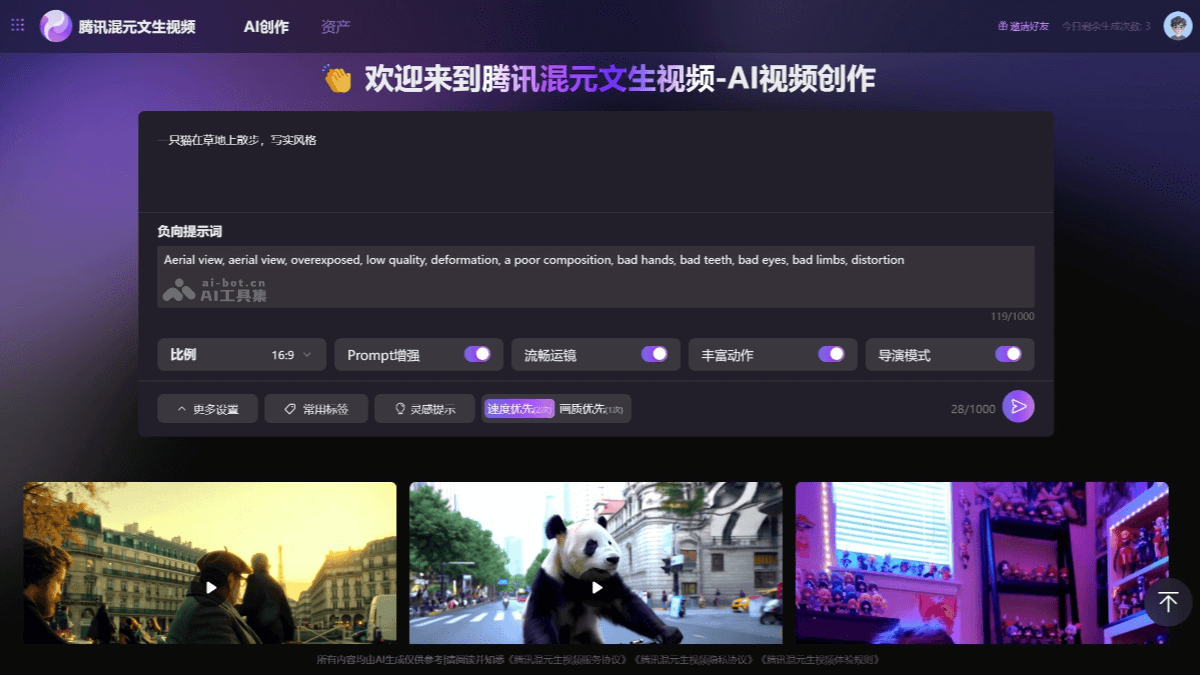
Main features of Tencent Hunyuan Text-to-Video
- Text-to-video generation: Generate corresponding video content based on the text prompts provided by the user.
- Multilingual support: Supports Chinese and English input, and can understand and generate videos in the corresponding language.
- High-definition image quality: The generated videos have high-definition image quality, providing a good visual experience.
- Shot transitions: Can achieve smooth shot transitions, enhancing the video's sense of dynamics and coherence.
- Object motion and scene simulation: Simulates object motion and scene changes, generating videos that are natural and consistent with the laws of physics.
- Multi-shot generation: Can generate multiple shots based on text prompts and achieve natural transitions between shots.
- Multi-action generation: Supports generating multiple coherent actions of the same subject, providing richer video content.
- Atmosphere creation: Can create a specific atmosphere and style based on prompts, enhancing the video's emotional expression.
- Follows complex prompts: Has good ability to follow complex prompts and can generate the scenes expected by users.
Hands-on test cases of Tencent Hunyuan Text-to-Video
Test 1:
- Content description: The shot begins by focusing on the flickering candlelight, with the outline of a young man writing a letter with his head lowered blurred. As the camera slowly pans to the right, the focus gradually shifts from the candle to the man's figure, and the texture of his clothes is clearly visible.
- Subjective impression: It accurately captures and reproduces typical Eastern aesthetics, recreating a subtle and atmospheric Chinese style. In a daze, one might think they are watching Tencent Video.
Test 2:
- Content description: Use a 200mm telephoto lens to capture a British Shorthair cat on the balcony, with the large potted plant in the foreground slightly blurred and its leaves swaying in the wind.
- Subjective impression: The British Shorthair cat's fur details are vivid, and the film grain and color saturation take the image quality to the next level.
Test 3:
- Content description: On a bustling snack street in Chengdu, a streamer wears clothing with Sichuan characteristics and a cute panda ear headband, tasting spicy skewers, with the bustling snack street and various tempting foods in the background.
- Subjective impression: Although there are minor flaws in the details, such as the slightly distorted presentation of the spicy skewers and some confusion in the streamer's clothing pattern, the overall completion is high, the streamer's performance is natural, and the background has a strong sense of everyday life, creating a rich everyday atmosphere overall.
Hands-on test 4:
- Content description: In a cafe decorated in a retro style, a young barista wearing a classic striped apron and a beret stands behind the counter, with coffee cups and handmade desserts placed on the counter.
- Subjective impression: Sunlight passes through the stained-glass windows and falls on the polished wooden boards, and Hunyuan presents the details of the reflections very exquisitely.
Comparison between Tencent Hunyuan Text-to-Video and Sora
Realistic scenes
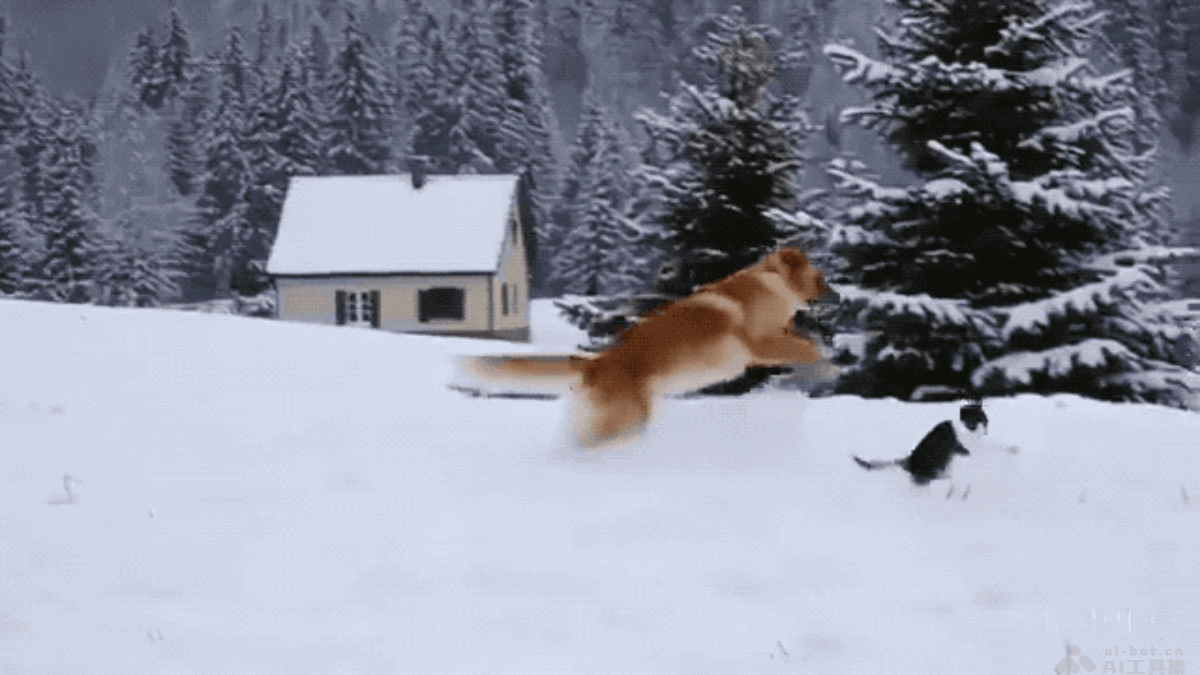
- Tencent Hunyuan Text-to-Video: A golden retriever chasing a cat in snowy Germany.
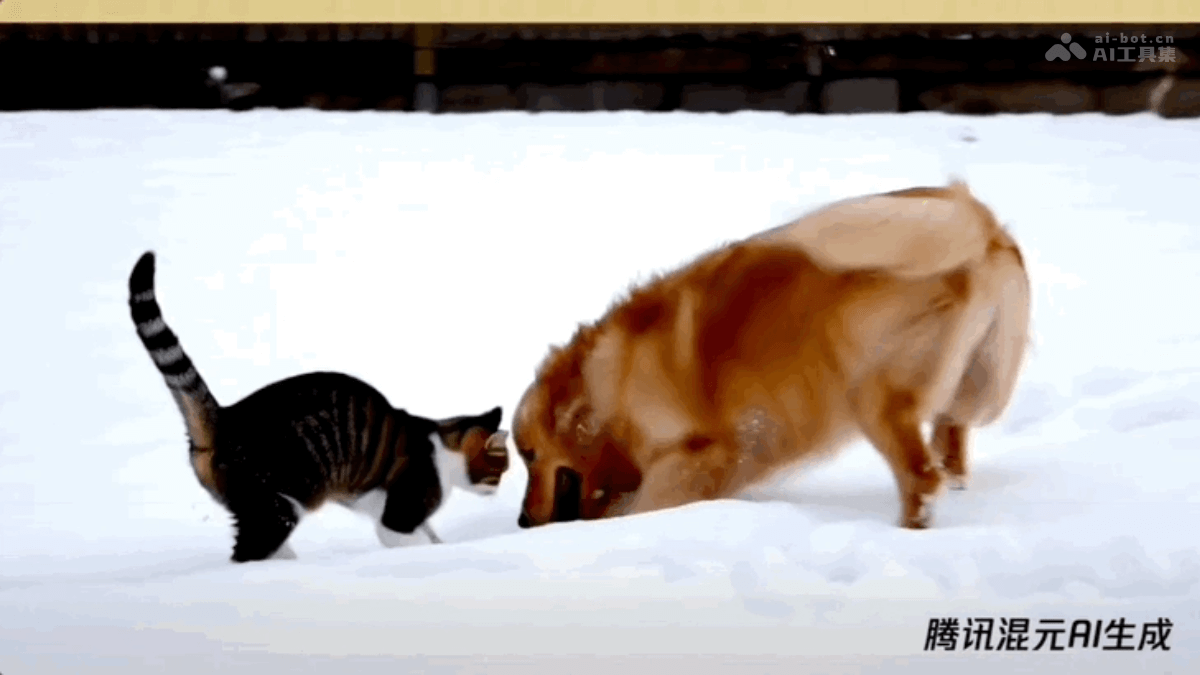
- Sora:A golden retriever chasing a cat in snowy germany。
Scenes that do not exist in reality
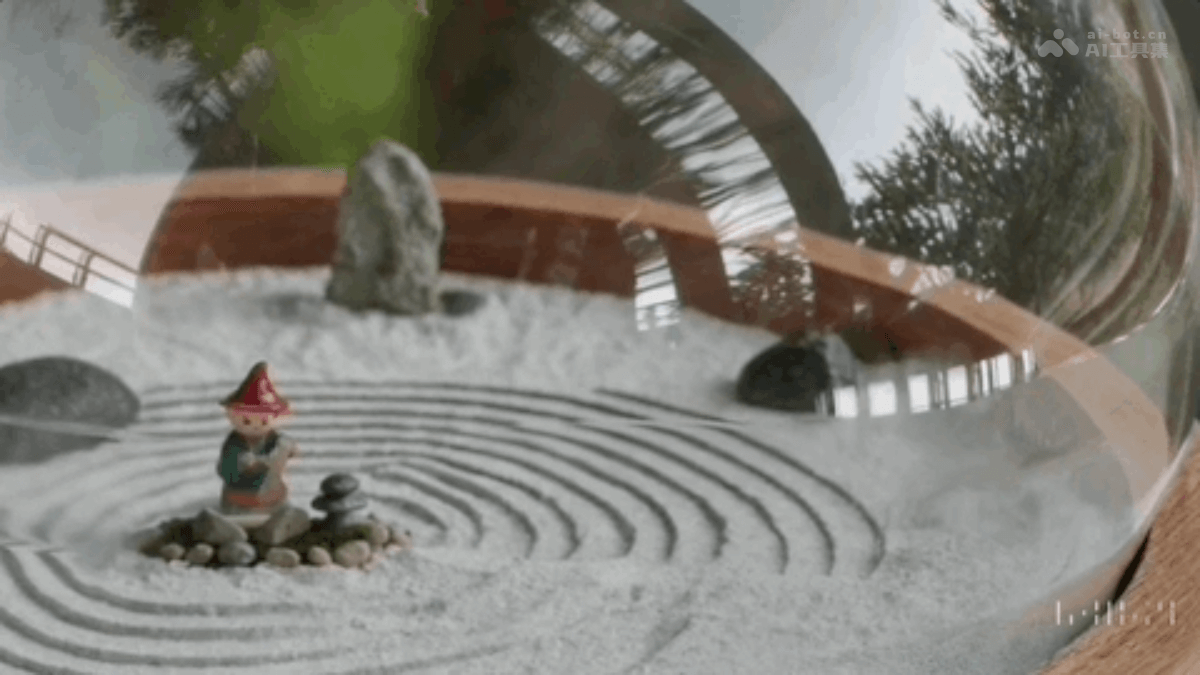
- Tencent Hunyuan Text-to-Video: A close-up shot showing a glass ball with a Zen garden inside. Inside the ball is a gnome raking the Zen garden and creating patterns in the sand.
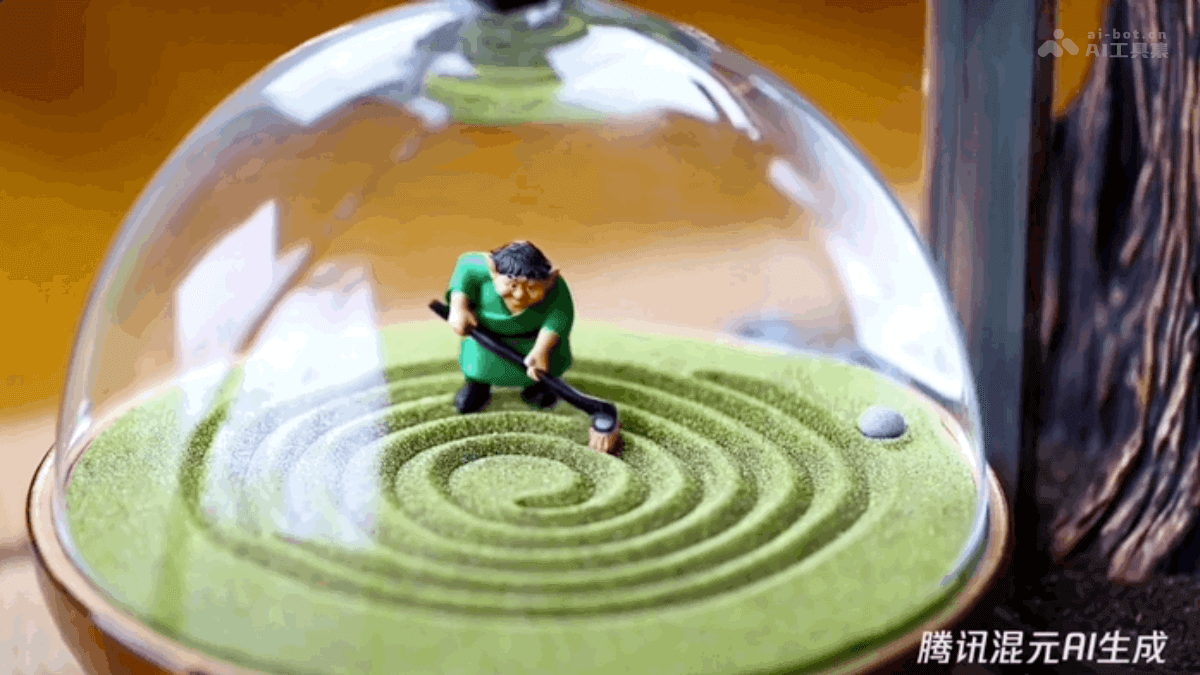
- Sora:A close up view of a glass sphere that has a zen garden within it. There is a small dwarf in the sphere who is raking the zen garden and creating patterns in the sand。
Long and complex prompt
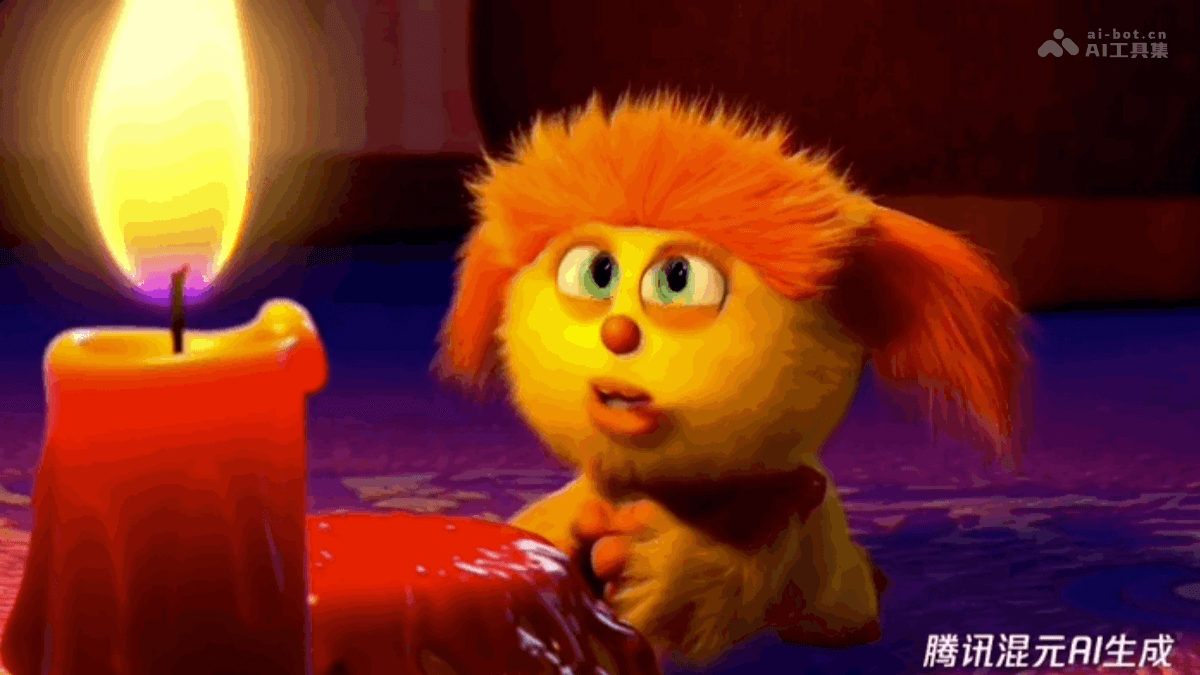
- Tencent Text-to-Video: The animated scene features a close-up of a short plush monster kneeling beside a melting red candle. The art style is 3D realistic, with attention to light and texture. The atmosphere of the painting is full of wonder and curiosity, as the monster stares at the flame with wide eyes and an open mouth. Its pose and expression convey a feeling of innocence and playfulness, as if it were exploring the world around it for the first time. The use of warm tones and dramatic lighting further enhances the cozy atmosphere of the image.
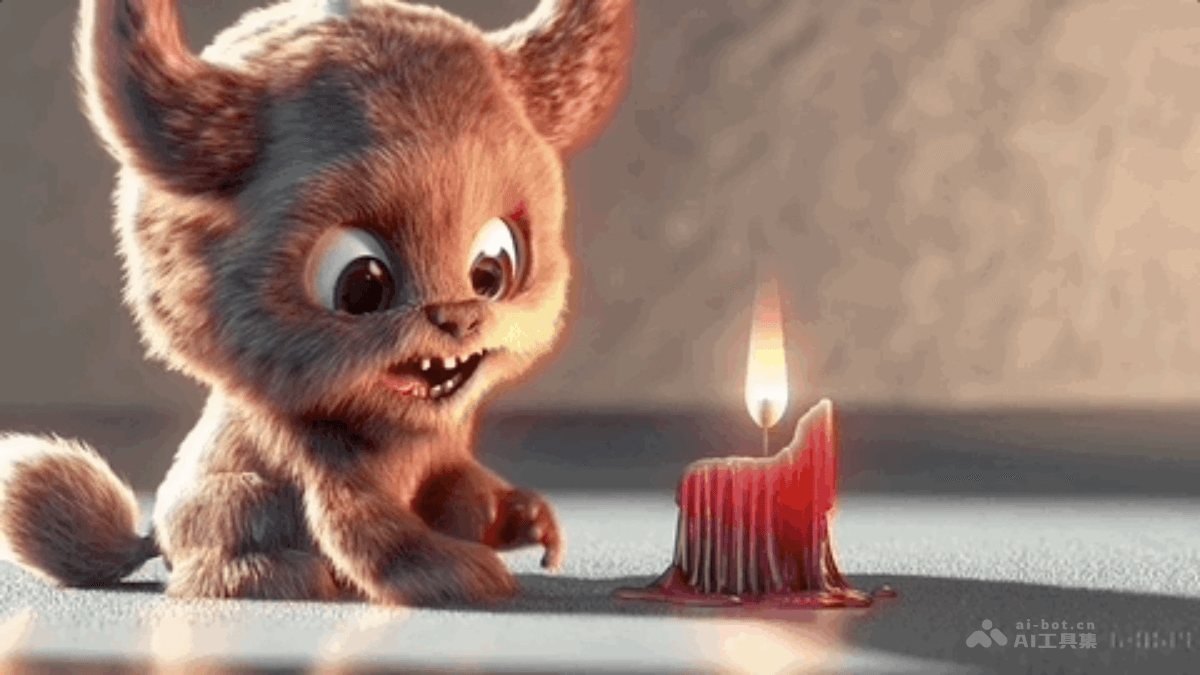
- Sora:Animated scene features a close-up of a short fluffy monster kneeling beside a melting red candle. The art style is 3D and realistic, with a focus on lighting and texture. The mood of the painting is one of wonder and curiosity, as the monster gazes at the flame with wide eyes and open mouth. Its pose and expression convey a sense of innocence and playfulness, as if it is exploring the world around it for the first time. The use of warm colors and dramatic lighting further enhances the cozy atmosphere of the image。
What is the Tencent Hunyuan Text-to-Video model
The Tencent Hunyuan Text-to-Video large model is an AI video generation model launched by Tencent, capable of generating corresponding video content based on text prompts. It was officially launched and open-sourced on December 3, 2024, for developers to use for free, with a parameter count of up to 13 billion, including complete models such as model weights, inference code, and model algorithms. It has stronger semantic understanding and image presentation capabilities, adopts a full attention mechanism throughout, making the transitions between each frame of video smoother, and uses a self-developed hybrid image-video VAE (3D variational encoder) to improve the model's performance in details, such as faces, fingers, high-speed shots, and more.
Project address of the Tencent Hunyuan Text-to-Video model
- Github repository:https://github.com/Tencent/HunyuanVideo
- HuggingFace model library:https://huggingface.co/tencent/HunyuanVideo
How to use Tencent Hunyuan Text-to-Video
- Visit Tencent Hunyuan Text-to-Video:Visitofficial website, where you can create videos, and after registering and logging in, you can generate 3 times for free.
- Log in to Tencent Yuanbao: or visitTencent Yuanbao, select the Tencent Hunyuan Text-to-Videofeature, and enter the creation page.
Application scenarios of Tencent Hunyuan Text-to-Video
- Film and television production: Use text-to-video technology to quickly generate preliminary concepts for special effects scenes, for early planning and discussion.
- Music videos: Create visual content that matches the rhythm and emotion of the music, enhancing the appeal of music videos.
- Game development: Generate cutscenes and background story videos in games, improving the immersion of the game.
- Advertising and marketing: Create customized advertising videos to showcase products or services in a more engaging way.
- Education and training: Produce simulation videos that recreate historical events or complex scientific phenomena to improve learning efficiency.