
What is Vid2World
Vid2World is an innovative framework launched by Tsinghua University in collaboration with Chongqing University. It supports converting full-sequence, non-causal passive video diffusion models (VDM) into autoregressive, interactive, action-conditioned world models. The model is based on two core technologies: video diffusion causalization and causal action guidance, addressing the shortcomings of traditional VDMs in causal generation and action conditioning. Vid2World performs excellently in complex environments such as robotic manipulation and game simulation, supporting the generation of high-fidelity, dynamically consistent video sequences and action-based interactive prediction. Vid2World opens up new avenues for improving the practicality and prediction accuracy of world models, with broad application prospects.
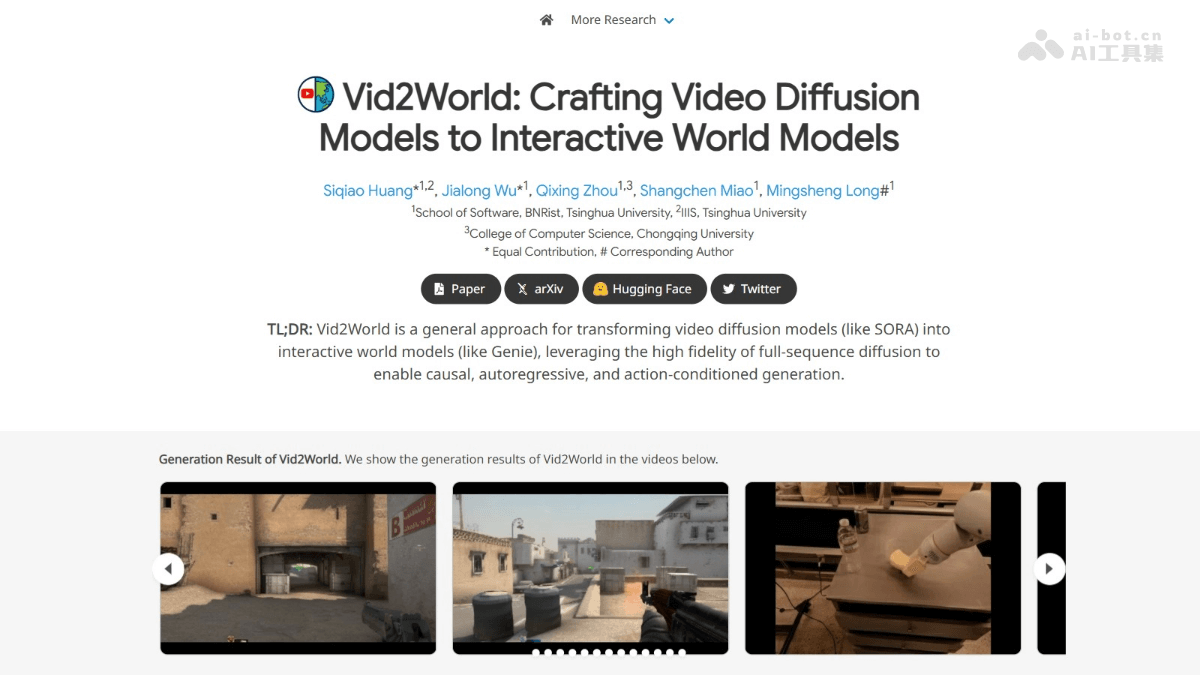
Main Features of Vid2World
- High-fidelity video generation: Generates predictions that are highly similar to real videos in visual fidelity and dynamic consistency.
- Action conditioning: Generates corresponding video frames based on the input action sequence, supporting fine-grained action control.
- Autoregressive generation: Generates videos frame by frame in an autoregressive manner, where each step's generation depends only on past frames and actions.
- Causal reasoning: The model can perform causal reasoning, where predictions depend only on past information and are not affected by future information.
- Supports downstream tasks: Supports interactive tasks such as assisting robotic manipulation and game simulation.
Technical Principles of Vid2World
- Video diffusion causalization: Video diffusion models (VDM) denoise the entire video sequence simultaneously. The full-sequence generation approach is not suitable for causal reasoning because future frames affect past frames. To achieve causal generation, Vid2World modifies the pretrained VDM by applying a causal mask to the temporal attention layer, restricting the attention mechanism to access only past frames, thereby achieving causality. The temporal convolution layer introduces a hybrid weight transfer scheme, preserving pretrained weights while adapting the model to causal convolution layers. Based on Diffusion Forcing technology, noise levels are independently sampled for each frame during training, allowing the model to learn combinations of noise levels across different frames and supporting autoregressive generation.
- Causal action guidance: To enable the model to respond to fine-grained actions, Vid2World introduces a causal action guidance mechanism. Each action is encoded via a lightweight multi-layer perceptron (MLP) and added to the corresponding frame. During training, each action is independently dropped with a fixed probability, forcing the model to learn both conditional and unconditional score functions. During testing, the responsiveness to action changes is adjusted based on a linear combination of the conditional and unconditional score functions. By independently dropping actions, the model can learn the impact of actions on generation results and better respond to action inputs during autoregressive generation.
Project Address of Vid2World
- Project official website:https://knightnemo.github.io/vid2world/
- HuggingFace model library:https://huggingface.co/papers/2505.14357
- arXiv technical paper:https://arxiv.org/pdf/2505.14357
Application Scenarios of Vid2World
- Robotic manipulation: Generates high-fidelity predictions to assist robot task planning.
- Game simulation: Generates videos highly consistent with real games, facilitating the development of neural game engines.
- Policy evaluation: Simulates the execution results of different policies to assist policy optimization.
- Video prediction: Predicts subsequent frames based on existing frames and action sequences, used in video completion, etc.
- Virtual environment construction: Generates a virtual scene of response actions, enhancing virtual reality interactivity.