
What is Vchitect 2.0
Vchitect 2.0 is an upgraded open-source video generation large model launched by Shanghai Artificial Intelligence Laboratory, aiming to generate video content that conforms to Chinese culture and Eastern aesthetics. The model supports video generation up to 20 seconds and is compatible with multiple resolutions, including 4:3 and 16:9. It provides an integrated video enhancement model with 2K resolution and 24fps, improving video quality and aesthetic level through integrated video generation, frame interpolation and super-resolution, and image restoration. Vchitect 2.0 launches the first evaluation framework supporting long videos of more than 20 seconds, promoting the development and application of video generation technology.
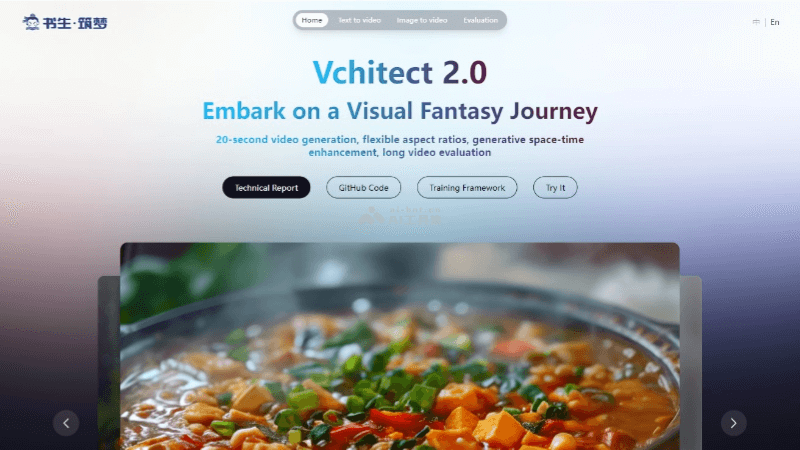
Main features of Vchitect 2.0
- Text-to-video generation: Users can generate short videos of 5 to 20 seconds by entering text prompts.
- Image-to-video conversion: Supports users in converting static images into 5 to 10 seconds of video content.
- Flexible aspect ratio: Supports users in generating videos with any aspect ratio, adapting to different display needs.
- HD video generation: The model can generate HD videos with a maximum resolution of 720×480.
- Super-resolution and frame insertion: Integrates the VEnhancer spatiotemporal enhancement module to perform super-resolution processing and frame insertion on videos, improving videos to 2K resolution and 24fps smoothness.
- Video generation evaluation framework: Launches the first evaluation framework VBench that supports long videos of more than 20 seconds, providing comprehensive evaluation tools for video generation models.
Technical principles of Vchitect 2.0
- Natural language processing: Parses text prompts and understands the user's creative intent.
- Video generation algorithms: Converts text or images into video content, involving deep learning and generative model technology.
- Cascaded latent diffusion model: Uses a cascaded latent diffusion model to generate videos, improving the quality and realism of generated videos.
- Spatiotemporal enhancement framework: Performs super-resolution processing and frame insertion on videos through the VEnhancer module, improving video smoothness and clarity.
- Multimodal hybrid model: Combines large language models and text-to-image generators to improve the accuracy of understanding text instructions and the generation quality of video content.
Project address of Vchitect 2.0
- Project official website:vchitect.intern-ai.org.cn
- GitHub repository:https://github.com/Vchitect/Vchitect-2.0
Application scenarios of Vchitect 2.0
- Advertising production: Vchitect 2.0 can quickly generate short video advertisements with creativity and visual impact, improving the appeal and influence of advertisements.
- Film editing and post-production: In film editing, the model helps editors quickly complete film editing work, improving work efficiency and quality.
- Educational content production: Teachers can generate teaching videos based on Vchitect 2.0 to present course content in a more vivid way, enhancing students' learning interest and effectiveness.
- Social media content creation: Users can use Vchitect 2.0 to generate personalized short videos, increasing the appeal and interactivity of content, and share them on social platforms.
- News and documentary production: Generates dynamic video content in news reports or documentaries, improving the richness and watchability of reports.