
What is Valley
Valley is a multimodal large model launched by ByteDance, used to handle diverse tasks involving text, image, and video data. Valley achieved the best results in internal e-commerce and short video benchmarks, and demonstrated excellent performance in OpenCompass tests, especially ranking second among models with fewer than 10B parameters. The Valley-Eagle version is based on the introduction of VisionEncoder to enhance the model's performance in extreme scenarios, can flexibly adjust the number of tokens, and processes in parallel with the original visual tokens.
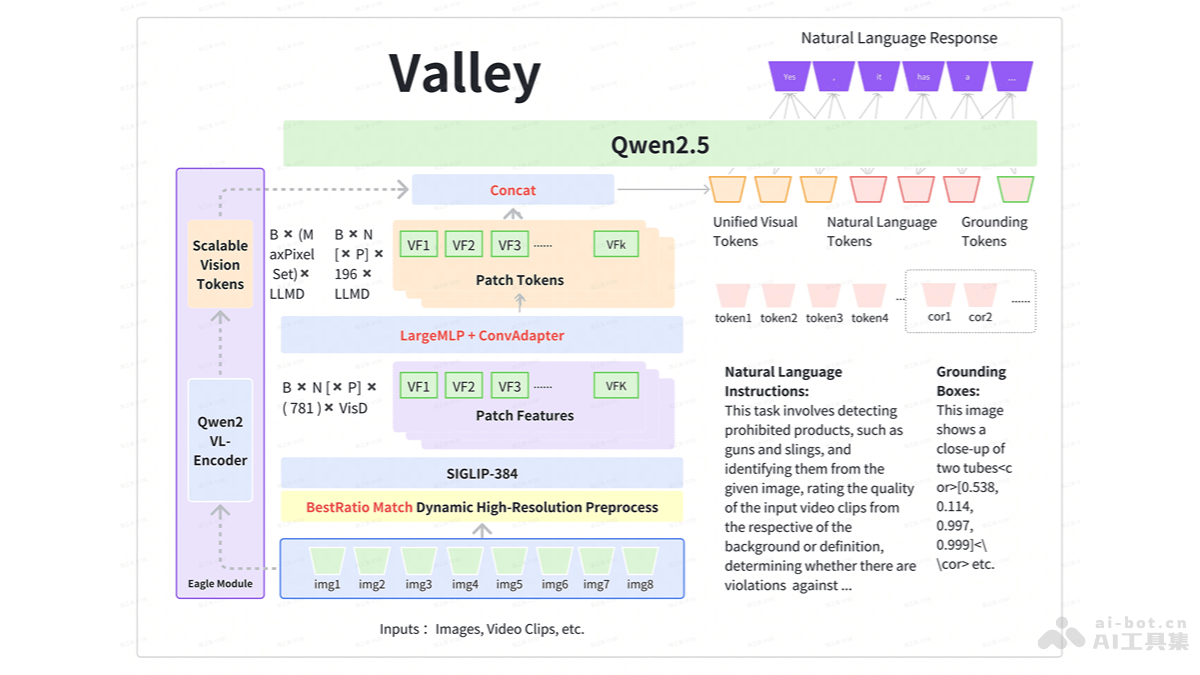
Valley's Main Features
- Multimodal Understanding: Can process text, image, and video data, providing deep understanding of different modalities of data.
- Task Processing: Supports various tasks involving multimodal data, such as image and video description, content analysis, etc.
- Performance Optimization: Demonstrates excellent performance in internal benchmarks and OpenCompass tests, especially in the e-commerce and short video domains.
- Model Scalability: With the introduction of VisionEncoder, Valley can flexibly adjust the number of tokens, enhancing performance in extreme scenarios.
Valley's Technical Principles
- LargeMLP and ConvAdapter: Combines LargeMLP (Large Multilayer Perceptron) and ConvAdapter (Convolutional Adapter) to build a projector, which helps the model's performance when processing visual data.
- VisionEncoder: The Valley-Eagle version introduces VisionEncoder, an additional encoder that can process visual tokens in parallel and flexibly adjust the number of tokens to adapt to different processing needs.
- Parallel Processing: Processes in parallel with the original visual tokens, enhancing the model's efficiency and effectiveness when processing large amounts of visual data.
- Model Alignment: Valley aligns with other models such as Siglip and Qwen2.5, and references the successful elements of these models in its design to ensure performance and compatibility.
Valley's Project Address
- GitHub Repository:https://github.com/bytedance/Valley
- HuggingFace Model Library:https://huggingface.co/bytedance-research/Valley
Valley's Application Scenarios
- Content Analysis and Understanding: Analyzes and understands text, image, and video content, providing support for content moderation, content recommendation, and content generation.
- Image and Video Description: Generates descriptive text for images and videos, suitable for social media, news reports, and educational materials.
- E-commerce: In the e-commerce field, used for product recommendation, user behavior analysis, and customer service automation.
- Short Video Platforms: Assists short video platforms in content creation, content moderation, and user experience optimization.
- Intelligent Assistant: As an intelligent assistant, understands and responds to user queries, providing image- and video-based information retrieval and recommendation.