
What is TRUEBench
TRUEBench (Trustworthy Real-world Usage Evaluation Benchmark) is an AI benchmarking tool launched by Samsung Electronics, used to evaluate the productivity of artificial intelligence in real-world work scenarios and address the limitations of existing AI benchmarks, such as being primarily English-centric and limited to single-turn question-answering structures. TRUEBench contains 2,485 test sets, covering 10 categories and 12 languages, and supports cross-lingual scenarios. TRUEBench ensures the accuracy and consistency of evaluation through human-AI collaborative design and optimization of evaluation criteria. TRUEBench's data samples and leaderboard have been released on the Hugging Face platform, allowing users to compare the performance and efficiency of up to five models.
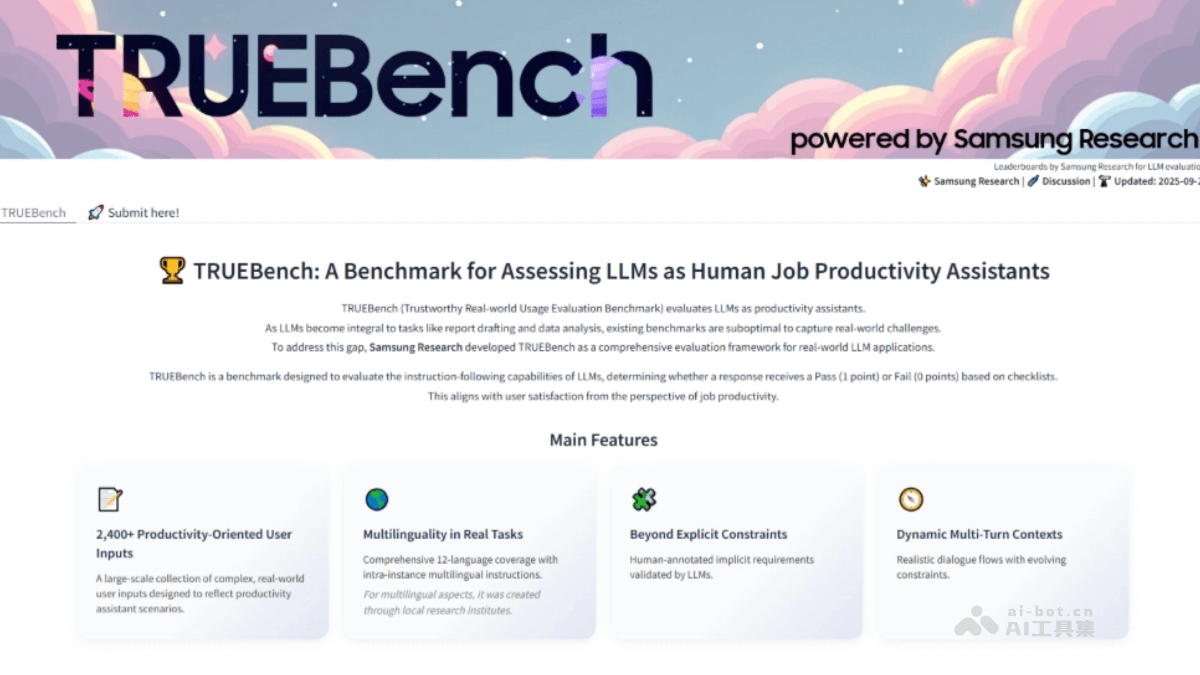
Main Features of TRUEBench
-
Comprehensive evaluation of AI productivity: TRUEBench evaluates around commonly used enterprise tasks across 10 categories and 46 subcategories, covering content generation, data analysis, text summarization, translation, and more.
-
Multilingual support: Supports 12 languages, including Korean, English, Japanese, and more.
-
Diverse test scenarios: Contains 2,485 test sets, with test set lengths ranging from 8 characters to over 20,000 characters, covering various tasks from simple tasks to long document summarization.
-
Reliable scoring system: An evaluation system designed based on AI-human collaboration, ensuring the accuracy and consistency of evaluation.
-
Publicly available data samples and leaderboard: Data samples and the leaderboard are now available on the open-source platform Hugging Face, allowing users to test up to 5 AI models.
Technical Principles of TRUEBench
-
Human-AI collaborative design of evaluation criteria: Human annotators create evaluation criteria, AI reviews them to check for errors, contradictions, or unnecessary restrictions, after which human annotators refine the criteria again, repeating this process to apply increasingly precise evaluation criteria.
-
Automatic AI evaluation: Based on the above cross-validated criteria, AI models are automatically evaluated, minimizing subjective bias and ensuring consistency。
-
Multilingual and cross-lingual scenario support: By designing test sets that support multiple languages and cross-lingual scenarios, TRUEBench can more comprehensively evaluate the performance of AI models in different language environments.
TRUEBench Project Address
- Project official website:https://news.samsung.com/global/samsung-introduces-truebench-a-benchmark-for-real-world-ai-productivity
- HuggingFace online experience:https://huggingface.co/spaces/SamsungResearch/TRUEBench
Application Scenarios of TRUEBench
-
Content generation: Used to evaluate AI's performance in tasks such as writing reports, emails, and copy, helping enterprises and developers understand AI's content creation capabilities.
-
Data analysis: Tests AI's ability to process and analyze data, such as generating charts and interpreting data, measuring its practicality in data-driven tasks.
-
Text summarization: Measures AI's efficiency in extracting key information and generating concise summaries, suitable for scenarios that require rapid information extraction.
-
Translation: Evaluates AI's accuracy and fluency in cross-lingual translation tasks, supports multilingual and cross-lingual scenarios, and is suitable for international business.
-
Multilingual support: By supporting multiple languages, TRUEBench can be more widely applied globally for AI evaluation in different language environments, meeting multilingual needs.