
What is TIP-I2V
TIP-I2V is a large-scale real text and image prompt dataset used in the field of image-to-video generation. TIP-I2V contains over 1.7 million unique user text and image prompts, along with corresponding videos generated by five state-of-the-art image-to-video models. The dataset can drive the development of better and safer image-to-video models, help researchers analyze user preferences, evaluate model performance, and address misinformation issues caused by image-to-video models.
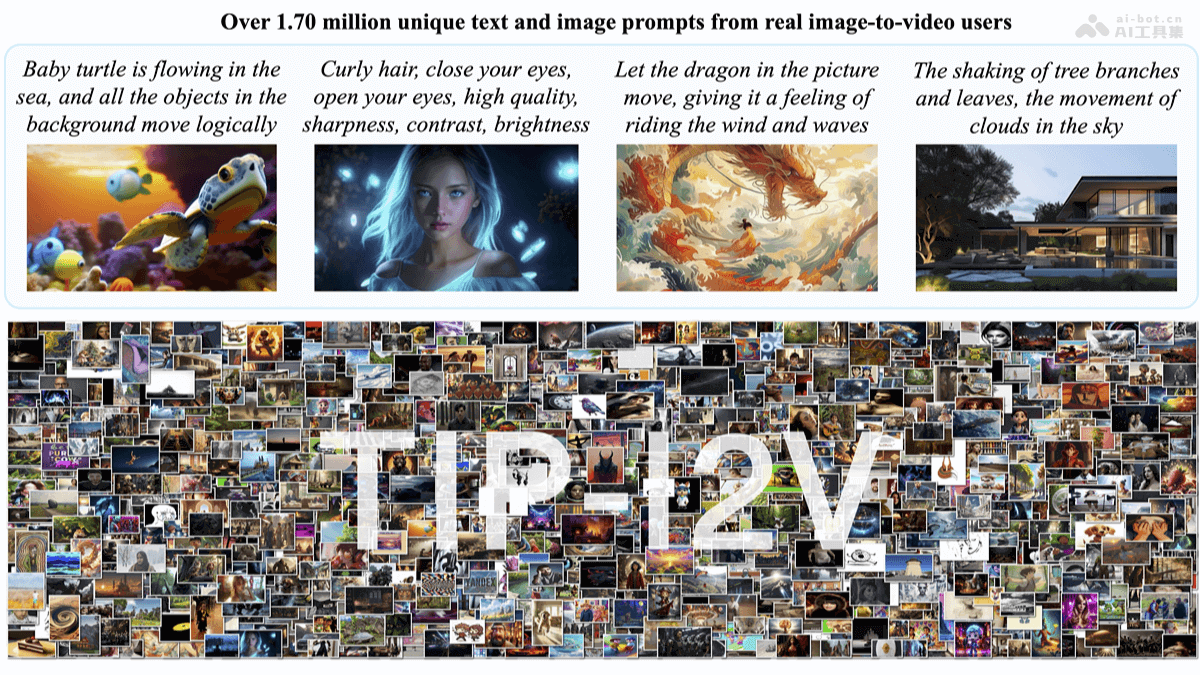
Main Features of TIP-I2V
- User Preference Analysis: By analyzing text and image prompts submitted by users, researchers can understand user needs and preferences for image-to-video generation.
- Model Performance Evaluation: Provides a platform for researchers to evaluate and compare the performance of different image-to-video generation models using real user data.
- Safety and Misinformation Research: Helps researchers address misinformation issues caused by image-to-video models, such as the creation of fake content by video generation technology.
Technical Principles of TIP-I2V
- Data Collection: Collects over 1.7 million text and image prompts, along with corresponding video generation results, from sources such as the Pika Discord channel.
- Multi-Model Integration: Integrates videos generated by five different image-to-video diffusion models (Pika, Stable Video Diffusion, Open-Sora, I2VGen-XL, CogVideoX-5B) to provide diverse data.
- Metadata Annotation: Assigns metadata such as UUID, timestamp, topic, NSFW (Not Safe For Work) status, text and image embeddings, etc., to each data point.
- Semantic Analysis: Based on natural language processing techniques such as GPT-4o, analyzes verbs in text prompts, and uses the HDBSCAN clustering algorithm to identify and rank the most popular topics.
- Video Generation Technology: Applies diffusion model technology, a type of generative model, to generate coherent video content from static images.
- Safety and Verification: Develops and evaluates models for identifying generated videos and tracing the source images of videos, to prevent videos from being abused for misinformation propagation.
Project Address of TIP-I2V
- Project Official Website:tip-i2v.github.io
- GitHub Repository:https://github.com/WangWenhao0716/TIP-I2V
- HuggingFace Model Library:https://huggingface.co/datasets/WenhaoWang/TIP-I2V
- arXiv Technical Paper:https://arxiv.org/pdf/2411.04709
Application Scenarios of TIP-I2V
- Content Creation and Entertainment: Independent artists can easily convert static paintings into dynamic videos for exhibitions or online galleries.
- Advertising and Marketing: Marketing teams can turn product images into attractive video ads to increase the click-through rate of online advertisements.
- Education and Training: Educational institutions can transform images of complex scientific concepts into easy-to-understand animated videos to assist teaching.
- News and Reporting: News organizations can convert photos from news scenes into videos to provide viewers with more intuitive news reports.
- Art and Design: Digital artists can transform static artworks into dynamic displays, creating new artistic experiences.