
What is TeleChat2-115B
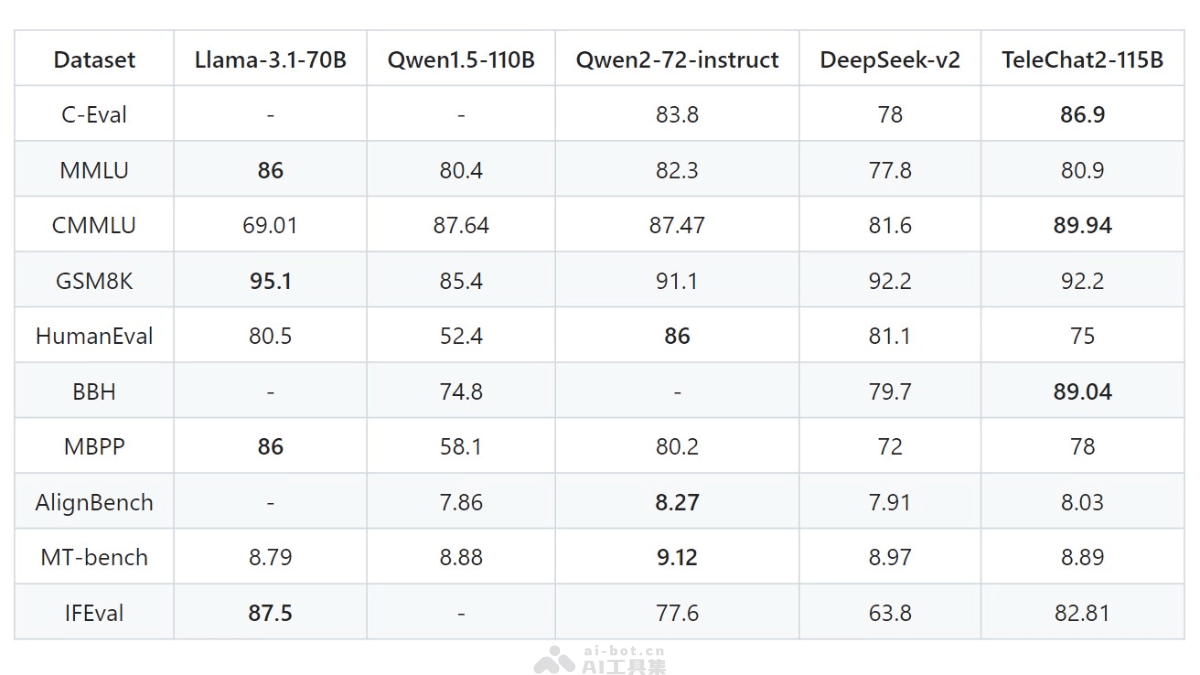
TeleChat2-115B is a large language model developed by the China Telecom Artificial Intelligence Research Institute (TeleAI), belonging to the Starlight semantic large model series. It is trained on domestic computing power and uses 10 trillion tokens of high-quality Chinese and English corpora. Compared with previous-generation models, TeleChat2-115B has significantly improved performance on general question answering, knowledge-based, code-based, and math-based tasks. The model has achieved excellent results on multiple evaluation leaderboards, such as ranking first in the C-Eval Open Access model comprehensive leaderboard. The open-sourcing of TeleChat2-115B marks an important advancement in domestic large model training technology and helps promote innovation and industrial application of large model technology.
Main features of TeleChat2-115B
- Text generation: can generate high-quality Chinese and English text.
- Multilingual support: supports training on high-quality Chinese and English corpora and processes text in both languages.
- Multiple formats and platforms: provides weight files in multiple formats and for multiple platforms, making deployment and use convenient in different environments.
- High-performance inference: supports single-card and multi-card inference, as well as long-text inference optimization.
- API and Web deployment: provides API and Web deployment methods and supports streaming generation and multi-turn dialogue.
Technical principles of TeleChat2-115B
- Decoder-only structure: uses a standard Decoder-only structure design for text generation tasks.
- Rotary Embedding: uses the Rotary Embedding positional encoding method, which helps the model better capture relative position information in sequence data.
- SwiGLU activation function: uses the SwiGLU activation function to replace the traditional GELU activation function, improving model performance.
- RMSNorm-based Pre-Normalization: performs layer normalization operations based on RMSNorm-based Pre-Normalization, helping improve the stability of model training.
- Separate word embedding and output layer parameters: separates the word embedding layer and output layer (lm head) parameters, helping enhance training stability and convergence.
- GQA optimization: chooses GQA (Grouped Query Attention) to save the parameter count and computation of the attention part and improve training and inference speed.
Project address of TeleChat2-115B
- GitHub repository:https://github.com/Tele-AI/TeleChat2
Application scenarios of TeleChat2-115B
- Intelligent customer service: as a chatbot, providing customer consultation services and answering user questions.
- Content creation: assisting writing and generating text content such as articles, stories, and poems.
- Language translation: achieving high-quality Chinese-English mutual translation.
- Educational tutoring: Provides language learning and homework tutoring, helping students understand complex concepts.
- Programming Assistance: Generates code snippets to help developers solve programming problems.
- Data Analysis: Processes and analyzes text data to extract useful information.
- Intelligent Search: Enhances search engines to provide more accurate search results.