
What is Tarsier2
Tarsier2 is an advanced large vision-language model (LVLM) launched by ByteDance. It generates detailed and accurate video descriptions and performs excellently in various video understanding tasks. The model achieves performance improvements through three key upgrades: expanding pretraining data from 11 million to 40 million video-text pairs, enriching data volume and diversity; performing fine-grained temporal alignment during the supervised fine-tuning stage; and automatically constructing preference data based on model sampling, then applying Direct Preference Optimization (DPO) training. On the DREAM-1K benchmark, Tarsier2-7B's F1 score is 2.8% higher than GPT-4o and 5.8% higher than Gemini-1.5-Pro. It achieves new best results on 15 public benchmarks, covering tasks such as video question answering, video grounding, hallucination testing, and embodied question answering.
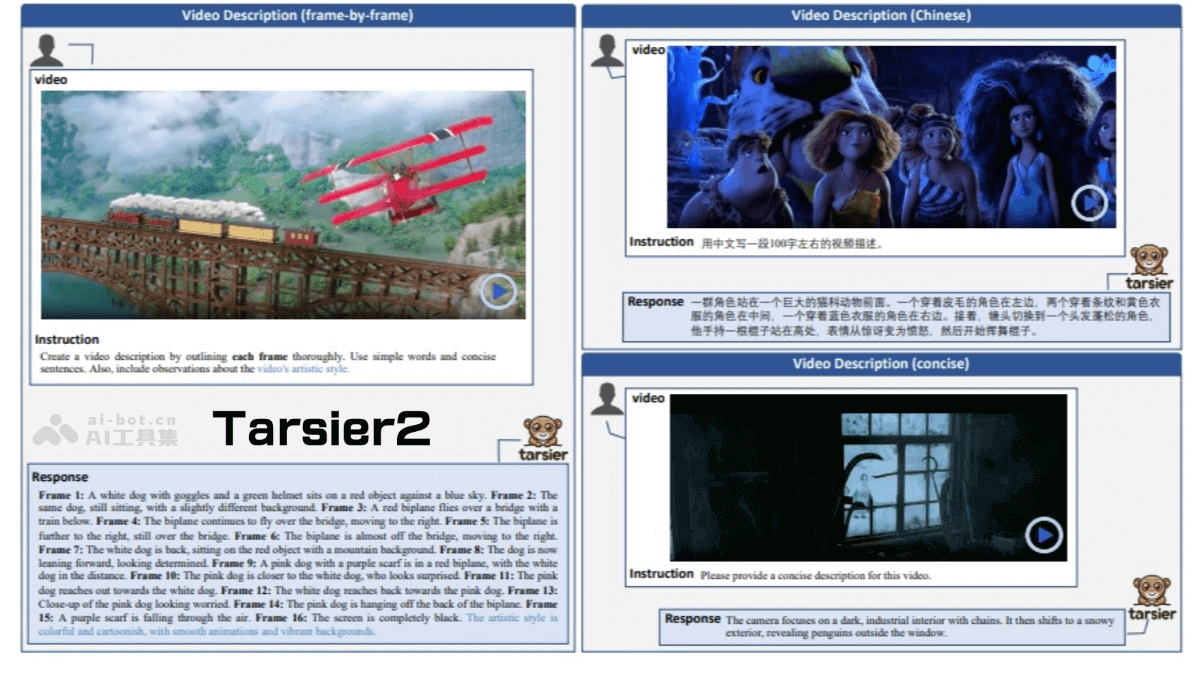
Main Features of Tarsier2
- Detailed Video Description: Tarsier2 can generate high-quality video descriptions covering various details in the video, including actions, scenes, and plots.
- Video Question Answering: It can answer specific questions about videos, demonstrating powerful spatiotemporal understanding and reasoning capabilities.
- Video Grounding: Tarsier2 can detect and locate the occurrence time of specific events in videos, supporting grounding for multiple video segments.
- Hallucination Testing: By optimizing the training strategy, Tarsier2 significantly reduces the possibility of the model generating false information.
- Multilingual Support: It supports video description generation in multiple languages, further expanding its application scenarios.
Technical Principles of Tarsier2
- Large-Scale Pretraining Data: Tarsier2 expands pretraining data from 11 million to 40 million video-text pairs, improving the scale and diversity of the data. The data includes short videos from the internet, commentary videos for movies or TV series, and video descriptions and question-answer pairs automatically generated through multimodal LLMs.
- Supervised Fine-Tuning (SFT) with Fine-Grained Temporal Alignment: During the supervised fine-tuning stage, Tarsier2 introduces 150,000 pieces of fine-grained annotated video description data, with each description corresponding to a specific timestamp. The time-aligned training method significantly improves the model's accuracy and ability to capture details in video description tasks, while also reducing generated hallucinations.
- Direct Preference Optimization (DPO): Tarsier2 automatically constructs preference data through model sampling and applies Direct Preference Optimization (DPO) for training. Based on positive and negative sample pairs generated by the model, it further optimizes the model's generation quality, ensuring that the generated video descriptions better align with human preferences.
Tarsier2 Project Address
- GitHub Repository:https://github.com/bytedance/tarsier
- arXiv Technical Paper:https://arxiv.org/pdf/2501.07888
Application Scenarios of Tarsier2
- Video Description: Tarsier2 can generate high-quality detailed video descriptions covering various details in the video, including actions, scenes, and plots.
- Hallucination Testing: Tarsier2 performs excellently in reducing generated hallucinations. Through Direct Preference Optimization (DPO) and fine-grained temporal alignment training, Tarsier2 significantly reduces the possibility of generating false information.
- Multilingual Support: Tarsier2 supports multilingual video description generation and can meet the needs of different language environments.
- Embodied Question Answering: Tarsier2 also performs excellently in Embodied QA tasks, and can combine visual and language information to provide accurate guidance for embodied intelligent agents.