
What is StreamingT2V
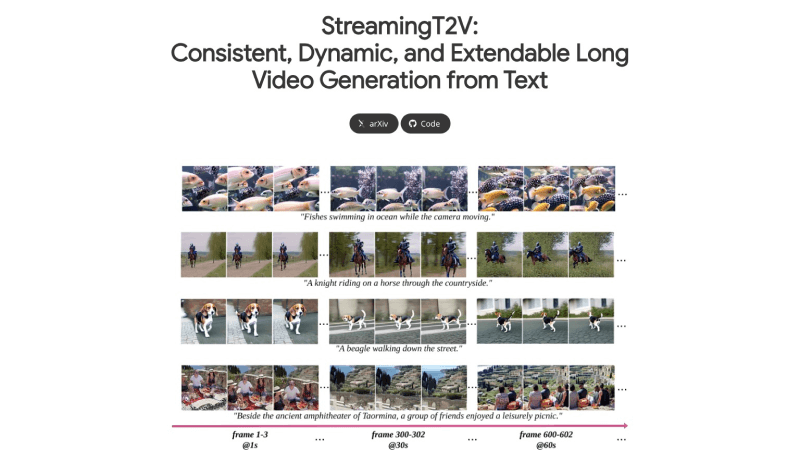
StreamingT2V is a text-to-video generation model launched by the PicsArt AI research team, aimed at addressing the challenge that existing models can only generate high-quality short videos of 16 or 24 frames, while encountering issues such as video quality degradation, inconsistent scene transitions, and video stagnation when generating long videos. By introducing the Condition Attention Module (CAM), the Appearance Preservation Module (APM), and a random blending method, StreamingT2V achieves smooth generation of long videos (up to 1200 frames, 2 minutes in duration), ensuring temporal coherence and close alignment with text descriptions. This method not only improves video quality but also makes video content richer and more dynamic, thereby achieving significant progress in the field of long video generation.
StreamingT2V Official Website Entry
- Official project homepage:https://streamingt2v.github.io/
- GitHub code repository:https://github.com/Picsart-AI-Research/StreamingT2V(Model and source code to be released)
- arXiv research paper:https://arxiv.org/abs/2403.14773
StreamingT2V Features
- Long video generation: StreamingT2V can generate long videos (80, 240, 600, 1200 frames or more) based on text descriptions, far exceeding the short video lengths typically generated by traditional models.
- Temporal coherence: The generated video frames have smooth transitions and consistency, avoiding the hard cuts or incoherence commonly seen when generating long videos.
- High-quality image frames: The model focuses on frame-level image quality, ensuring that even when the video is long, the image in each frame remains clear and detailed.
- Text alignment: Videos generated by StreamingT2V are closely aligned with the input text prompt descriptions, ensuring that the video content remains consistent with the user's text guidance.
- Video enhancement: Using a random blending method, StreamingT2V can enhance the quality of generated videos without introducing inter-block inconsistency, improving video resolution and visual effects.
StreamingT2V Workflow
The workflow of StreamingT2V can be divided into the following main stages:
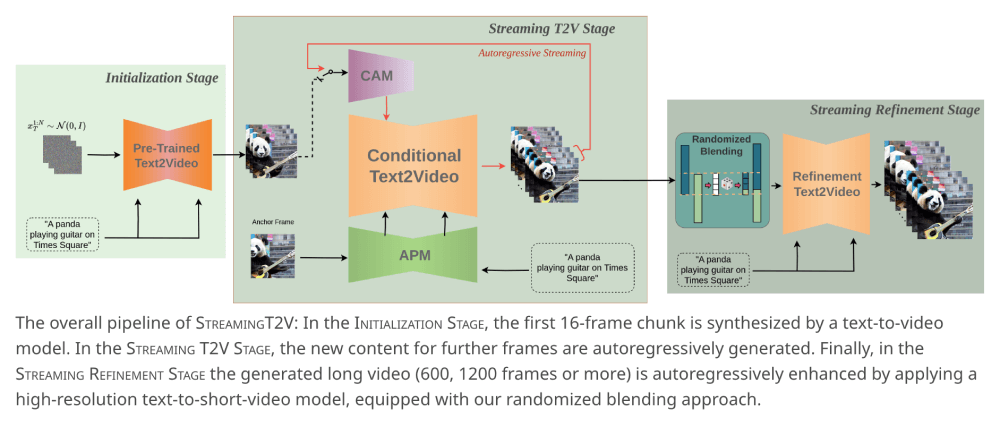
- Initialization Stage:
- At this stage, a pretrained text-to-video model (such as Modelscope) is first used to synthesize an initial video block, usually a short 16-frame video sequence.
- Streaming T2V Stage:
- Next, the model enters an autoregressive long video generation process. At this stage, StreamingT2V uses the Condition Attention Module (CAM) and the Appearance Preservation Module (APM) to generate subsequent frames of the long video.
- CAM uses short-term memory to focus on the features of the previous video block through an attention mechanism, thereby achieving smooth transitions between blocks.
- APM uses long-term memory to extract key visual features from the initial video block, ensuring consistency of scenes and objects throughout the entire video generation process.
- Streaming Refinement Stage:
- After generating a sufficiently long video (for example, 80, 240, 600, 1200 frames or more), the model enters the refinement stage.
- At this stage, a high-resolution text-to-video model (such as MS-Vid2Vid-XL) is used to perform autoregressive enhancement on the generated video.
- Through a random mixing method, consecutive 24-frame video blocks are enhanced while maintaining smooth transitions between blocks, thereby improving the overall quality and resolution of the video.