
What is StableV2V
StableV2V is an open-source video editing project launched by the University of Science and Technology of China, enabling precise editing and replacement of objects in videos based on inputs such as text, sketches, and images. The project uses a shape-consistent editing paradigm based on three main components: Prompted First-frame Editor (PFE), Iterative Shape Aligner (ISA), and Conditional Image-to-video Generator (CIG), ensuring that the edited content is consistent with the motion and depth information of the original video, and generating natural and smooth edited videos.
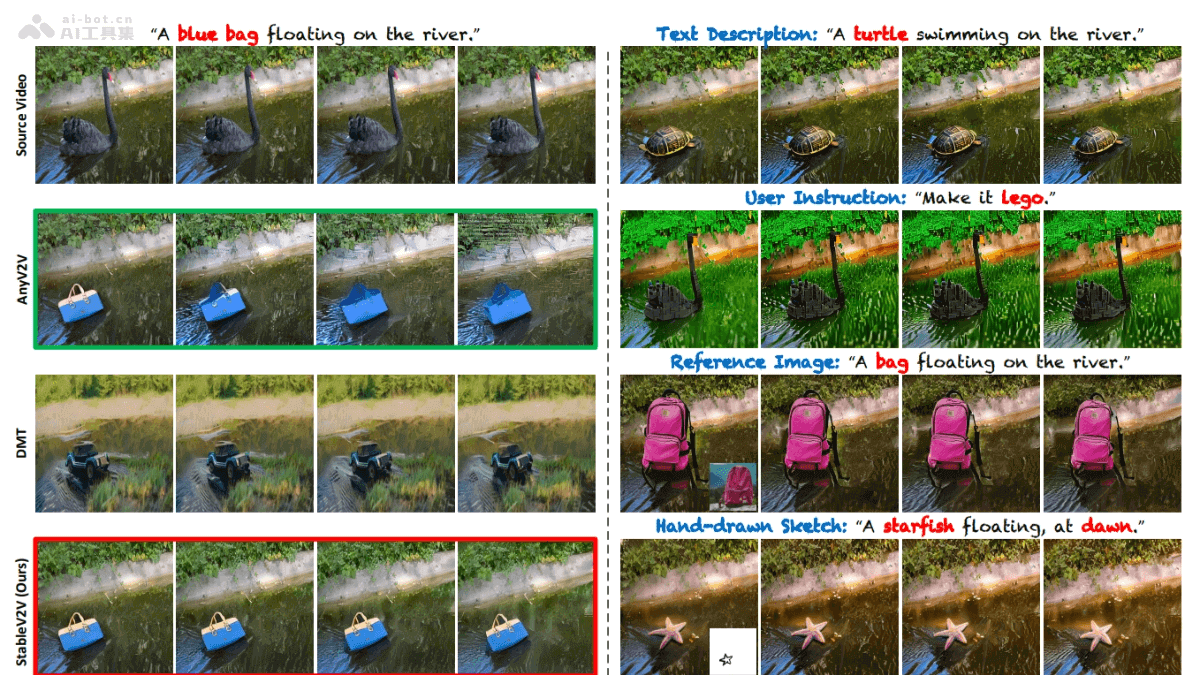
Main Features of StableV2V
- Video editing based on multiple inputs: Supports multiple input methods such as text, sketches, and images to enable editing and replacement of objects in videos.
- Shape consistency preservation: Ensures that the edited video content remains consistent with the original video in shape and motion, even when the object shape changes significantly.
- Flexible user prompt handling: Flexibly handles different types of user prompts, providing a broader creative space.
- High-quality video output: Generates high-quality edited videos with excellent visual effects.
Technical Principles of StableV2V
- Prompted First-frame Editor (PFE):As the starting point of the editing process, PFE is responsible for converting user prompts (text, images, sketches, etc.) into the edited content of the first frame of the video.
- Iterative Shape Aligner (ISA):
- ISA is based on the assumption that the edited content shares the same motion and depth information as the original content, using depth maps as a bridge to transfer motion.
- Based on motion simulation and depth simulation processes, ISA can calculate and propagate average motion, shape, and depth information.
- A shape-guided depth refinement network is used to optimize the depth map, ensuring that the interaction between the object and the surrounding environment looks natural and reasonable.
- Conditional Image-to-video Generator (CIG):
- CIG is responsible for converting the edited first frame and the optimized depth map into a complete edited video.
- Ctrl-Adapter is used as the controller to inject depth map information into the generation process.
- With the help of I2VGen-XL, the edited content is extended from the first frame to the entire video sequence, generating a high-quality edited video.
- Use of depth information:The depth map plays a key role, transferring motion information and guiding video generation, ensuring that the depth and motion of the edited content are consistent with the original video.
- Components work together:The three components PFE, ISA, and CIG work together to ensure that the entire process from first-frame editing to video generation maintains a high degree of consistency and naturalness.
StableV2V Project Address
- Project Website:alonzoleeeooo.github.io/StableV2V
- GitHub Repository:https://github.com/AlonzoLeeeooo/StableV2V
- HuggingFace Model Library:https://huggingface.co/AlonzoLeeeooo/StableV2V
- arXiv Technical Paper:https://arxiv.org/pdf/2411.11045
Application Scenarios of StableV2V
- Film and video production:Used in special effects production, scene transformation, and character replacement, enabling creative visual effects without reshooting.
- Social media content creation:Content creators can quickly edit video content to increase the appeal and creativity of videos, such as turning ordinary scenes into works of artistic style.
- Education and training:Produce instructional videos to visualize abstract concepts, such as historical scene reenactments or scientific phenomenon simulations, as well as safety drills and technical operation demonstrations.
- News and reporting:Edit and enhance on-site video to provide clearer and more specific visual reporting, such as simulating the process of natural disasters occurring.
- Advertising and marketing:Create more engaging advertising videos, integrate products into creative scenes, and improve the appeal and memorability of advertisements.