
What is SoulX-FlashTalk
SoulX-FlashTalk is the first 14B-parameter real-timedigital human generationmodel open-sourced by Soul App's AI team, achieving 0.87-second sub-second latency and 32fps high frame rate. The model adopts bidirectional streaming distillation and multi-step self-correction mechanisms to achieve unlimited-duration stable generation, full-body motion interaction, and multilingual driving, suitable for 7×24-hour live streaming, virtual customer service, game NPCs, and other scenarios. The model has now ranked in the HuggingFace I2V trending list TOP5, providing an open-source solution for commercial-grade real-time digital human applications.
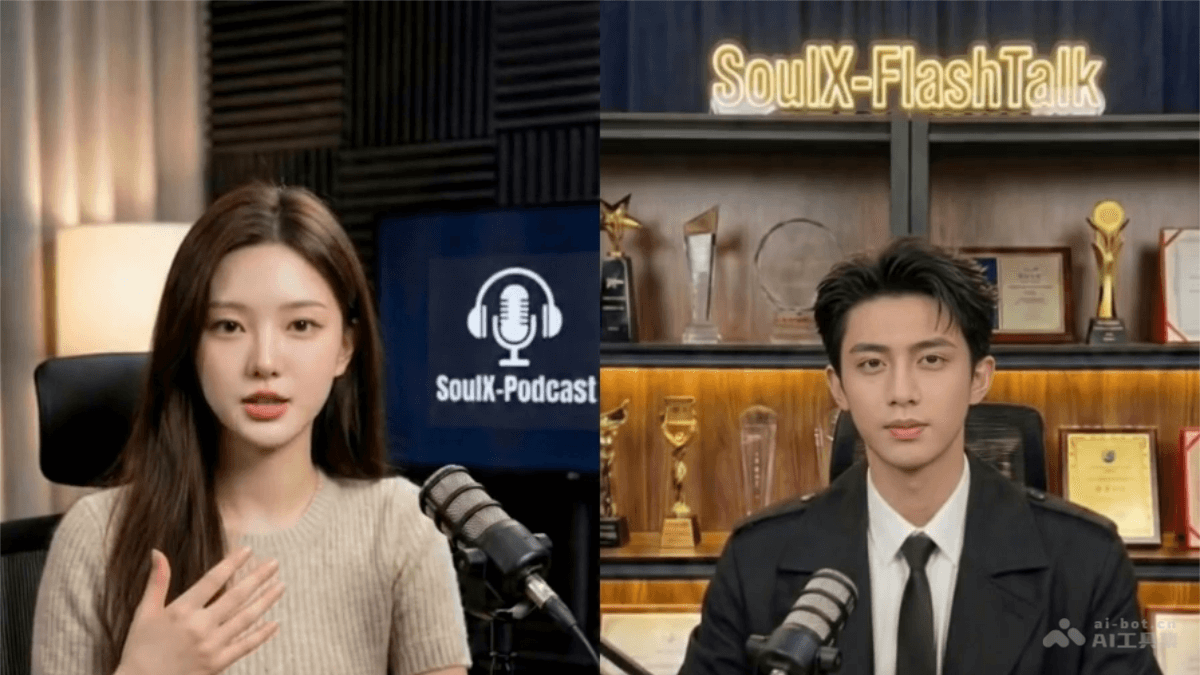
Main Features of SoulX-FlashTalk
-
Real-time audio-video generation: Based on a 14B large model, it achieves 0.87-second sub-second latency and 32fps high-frame-rate output, meeting live-streaming-grade real-time interaction needs.
-
Audio-driven digital human: Supports receiving speech or audio input, precisely driving synchronized changes in the virtual avatar's lip movements, facial expressions, and body movements.
-
Full-body motion synthesis: Supports full-body limb dynamics generation and highly detailed hand movement performance.
-
Ultra-long stable generation: Through a self-correction mechanism, it ensures identity consistency, stable visuals, and lossless image quality during long-duration generation.
-
Multilingual support: The model uses a Chinese-optimized speech encoder and a Chinese-English bilingual subtitle encoder, supporting cross-language digital human driving.
-
Infinite streaming generation: Supports 7×24-hour continuous uninterrupted live streaming, with the system running stably without crashing or lagging.
-
Multi-style avatars: Compatible with multiple visual styles such as cartoon and realistic, meeting avatar customization needs for different application scenarios.
Technical Principles of SoulX-FlashTalk
- Bidirectional streaming distillation: By retaining the intra-block bidirectional attention mechanism during the streaming generation process, it effectively maintains spatiotemporal correlations while significantly simplifying the training process, enabling the model to converge with only 1000 steps of supervised fine-tuning and 200 steps of distillation. Compared with traditional methods, it achieves a 23-fold improvement in training efficiency, laying the foundation for real-time deployment of large models.
- Latency-aware spatiotemporal adaptation: As the first-stage training strategy, it is specifically optimized for low-resolution inputs, short frame sequences, and dynamic aspect-ratio bucketing, allowing the 14B-parameter large model to first adapt to the demands of fast inference. While reducing computational burden, it maintains generation quality and resolves the contradiction between large model parameter count and inference speed.
- Multi-step retrospective self-correction mechanism: Used to ensure the stability of unlimited-duration generation, it can detect and correct accumulated errors in real time during the generation process, preventing errors from snowballing over time. It ensures consistent identity features, stable and smooth visuals, and lossless visual quality during long video generation, achieving true "infinite streaming" output.
- 3D VAE latent space compression: Based on the WAN2.1 architecture, it performs efficient latent space encoding and decoding of high-resolution video, greatly reducing the computational burden of real-time generation; combined with the full 3D attention and multimodal cross-attention mechanisms of the 14B DiT generator, as well as the multi-dimensional encoding of speech, images, and text by the conditional encoder layers, it builds a complete end-to-end real-time digital human generation system.
SoulX-FlashTalk Project Address
- Project Website:https://soul-ailab.github.io/soulx-flashtalk/
- GitHub Repository:https://github.com/Soul-AILab/SoulX-FlashTalk
- HuggingFace Model Repository:https://huggingface.co/Soul-AILab/SoulX-FlashTalk-14B
Application Scenarios of SoulX-FlashTalk
-
7×24-hour AI livestream room: E-commerce digital human streamers can achieve round-the-clock uninterrupted livestreaming, read and reply to bullet comments in real time, greatly reducing labor costs while maintaining a natural and smooth livestreaming experience.
-
AI virtual instructors and smart customer service: Applied in scenarios such as bank tellers and online education, it provides a face-to-face interaction experience similar to video calls, supporting real-time voice Q&A and emotive feedback.
-
High-quality batch production of short videos and short dramas: Only a segment of audio is needed to directly generate a complete digital human video, with no need for motion capture equipment or post-production. Long video output quality remains stable and consistent, greatly improving content production efficiency.
-
Real-time NPCs in games: The model supports voice-driven non-scripted dialogue, enabling real-time linkage between emotions and actions, providing players with a more immersive and dynamic interactive experience.