
What is SongCreator
SongCreator is launched by Tsinghua University Shenzhen International Graduate School, The Chinese University of Hong Kong, and other institutionsAI music generation model, which can generate complete songs containing vocals and accompaniment starting from lyrics. Based on the dual-sequence language model (DSLM) and attention masking strategy, it understands and generates various related song generation tasks, including editing and generation. SongCreator performs excellently in multiple tasks, especially in lyrics-to-song and lyrics-to-vocals tasks, and can independently control the acoustic conditions of vocals and accompaniment in generated songs.
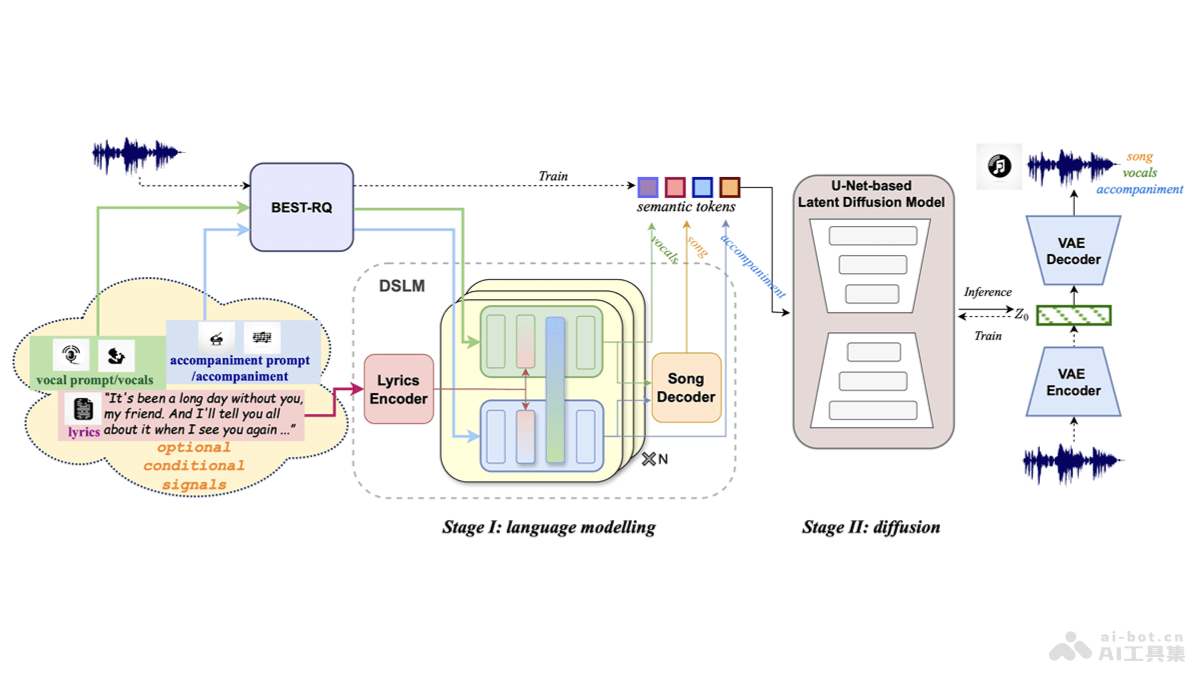
SongCreator's main features
- Lyrics-to-Song: Generate a complete song containing vocals and accompaniment based on the provided lyrics.
- Lyrics-to-Vocals: Generate the vocal part based on lyrics, without accompaniment.
- Accompaniment-to-Song: Given an accompaniment, generate a vocal part that harmonizes with the accompaniment to form a complete song.
- Vocals-to-Song: Given a vocal part, generate accompaniment to form a complete song.
- Song Editing: Modify specific sections in an existing song to match the target lyrics while maintaining coherence with the original song.
- Vocals Editing: Edit the vocal part in a song without changing the accompaniment.
- Music Continuation: Generate a continuous part of music based on a segment of accompaniment or vocals.
- Unconditional music generation: Generate music or vocals without lyrics.
SongCreator's technical principles
- Dual-sequence language model (DSLM): Use DSLM to capture information from vocals and accompaniment. The model includes two decoders, respectively for vocals and accompaniment, and captures the mutual influence between the two through a dynamic bidirectional cross-attention module.
- Attention masking strategy: Design a series of attention masking strategies. The strategy supports the model in working in a unified way across different song generation tasks, such as editing, understanding, and generation.
- Multi-task training: Improve its capabilities in composition, arrangement, and understanding based on multi-task training, enabling it to handle various complex music scenarios.
- Conditional signals: Accept multiple optional inputs, including lyrics, vocal prompts, accompaniment prompts, etc., giving it a high degree of flexibility and controllability when generating songs.
- Semantic Tokens: Use the BEST-RQ model trained on an unlabeled dataset to extract semantic tokens of songs based on vector quantization. The tokens contain the semantic and acoustic details needed to reconstruct the song.
- Latent Diffusion Model (LDM): Use LDM to decode semantic tokens into high-quality song audio. The model consists of a variational autoencoder (VAE) and a diffusion model, and is used to generate high-fidelity and musical music.
SongCreator's project address
- Project official website:songcreator.github.io
- arXiv technical paper:https://arxiv.org/pdf/2409.06029
SongCreator's application scenarios
- Music production: Music producers and composers generate song demos, quickly prototype, or seek inspiration during the creative process.
- Education and learning: In music education, as a teaching tool, it helps students understand song structure and learn composition and arrangement.
- Entertainment and gaming: In video games and interactive media, background music is generated in real time according to the game context, enhancing players' immersion.
- Content creation: Video content creators and podcasts customize original music for projects without having to hire professional musicians.
- Advertising and marketing: The advertising industry quickly generates soundtracks that match the brand image and advertising concept.