
What is SNOOPI
SNOOPI is an innovative text-to-image generation framework that improves model performance and controllability based on guidance for enhanced single-step diffusion models. SNOOPI includes two techniques: PG-SB (Proper Guidance – SwiftBrush) and NASA (Negative-Away Steer Attention). PG-SB uses a random-scale classifier-free guidance method to enhance training stability; NASA uses a cross-attention mechanism to integrate negative prompts, effectively suppressing unwanted elements in generated images. Experimental results show that SNOOPI significantly surpasses baseline models on multiple evaluation metrics, especially achieving an HPSv2 score of 31.08, setting a new benchmark for single-step diffusion models.
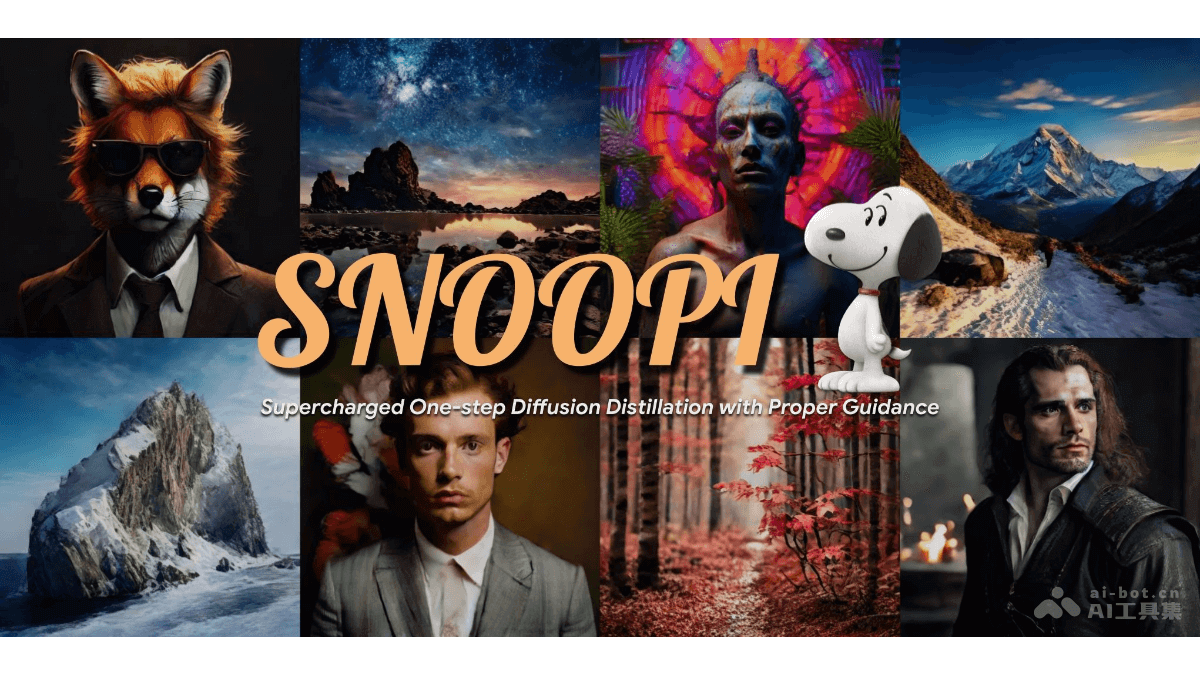
SNOOPI's main features
- Improve the efficiency of single-step text-to-image diffusion models: Simplify multi-step text-to-image diffusion models into single-step models, improving generation efficiency and reducing computational resource requirements.
- Enhance model stability and controllability: Based on PG-SB and NASA techniques, SNOOPI provides more stable performance during training and inference, and supports finer control over generated images.
- Support negative prompt guidance: SNOOPI uses NASA technology to support negative prompts, making it possible to exclude unwanted elements during image generation and enhancing the practical application value of image generation.
- Improve image quality: SNOOPI can generate high-quality, high-resolution images, and its HPSv2 score reaches 31.08, demonstrating its advantage in image quality.
- Cross-model backbone compatibility: SNOOPI can work effectively on different model backbones, including PixArt-α, SDv1.5, and SDv2.1, demonstrating broad applicability.
SNOOPI's technical principles
- Random-scale classifier-free guidance: PG-SB (Proper Guidance – SwiftBrush) varies the guidance ratio of the teacher model during training, expands the output distribution, and enables the model to adapt to different diffusion model backbones while maintaining competitive performance.
- Negative prompt integration: NASA (Negative-Away Steer Attention) integrates negative prompts into single-step diffusion models based on a cross-attention mechanism, adjusting the attention weights in the intermediate feature space to reduce the appearance of unwanted features in generated images.
- Model output alignment: The VSD framework uses pretrained diffusion models to enhance text-based generation, ensuring that generated images align with the probability density of the teacher model.
- Feature filtering: Based on the NASA mechanism, SNOOPI filters out unwanted features in the feature space, can exclude unwanted elements before generating images, and reduces the appearance of blending artifacts.
SNOOPI's project address
- Project official website:snoopi-onestep.github.io
- GitHub repository:https://github.com/VinAIResearch/SNOOPI
- HuggingFace model library:https://huggingface.co/papers/2412.02687
- arXiv technical paper:https://arxiv.org/pdf/2412.02687
SNOOPI's application scenarios
- Digital art creation: Artists and designers can quickly generate images with specific styles or elements, improving creative efficiency.
- Game development: In game design, quickly generate game environments, character concept art, or other game assets.
- Advertising and marketing: Marketers can quickly generate attractive advertising images based on copy, improving the appeal and personalization of marketing materials.
- Social media content generation: Social media users and content creators generate personalized images and posts, increasing interaction and engagement.
- Film and entertainment industry: In film production and the entertainment industry, generate special effects images, backgrounds, or storyboards.