
What is Show-o
Show-o is a unified Transformer model that integrates multimodal understanding and generation. By combining autoregressive and discrete diffusion modeling, it can flexibly handle a wide range of vision-language tasks, including visual question answering, text-to-image generation, text-guided inpainting and extrapolation, and mixed-modality generation. The Show-o model demonstrates performance comparable to or better than existing specialized models on multimodal understanding and generation benchmarks, and can reduce the sampling steps required for image generation, improving efficiency. Show-o supports a variety of downstream applications, such as text-guided image inpainting and extrapolation, without the need for additional fine-tuning.
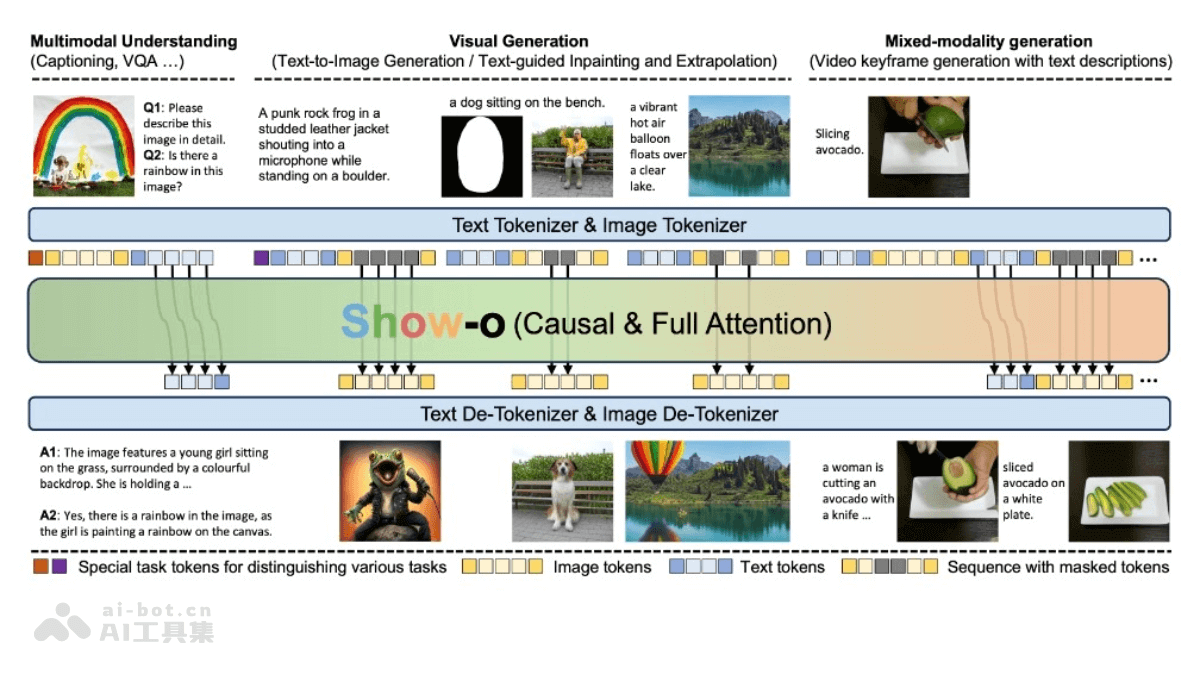
Show-o's Main Features
- Visual Question Answering (VQA): It can understand image content and answer questions about the image.
- Text-to-Image Generation: It generates corresponding images based on text descriptions, supporting creative and diverse visual outputs.
- Text-Guided Image Inpainting: It can identify missing parts in an image and repair them based on text prompts.
- Text-Guided Image Extrapolation: It adds new elements to an image or extends the image content based on text descriptions.
- Mixed-Modality Generation: It combines text descriptions to generate video keyframes, providing possibilities for long video generation.
- Multimodal Understanding and Generation: It integrates visual and language information to handle complex multimodal tasks.
Show-o's Technical Principles
- Unification of Autoregressive and Discrete Diffusion Modeling: The Show-o model innovatively combines autoregressive and discrete diffusion modeling, adaptively handling various different and mixed-modality inputs and outputs.
- Based on a Pretrained Large Language Model (LLM): Show-o's architecture is based on a pretrained LLM, with QK-Norm operations added before each attention layer to improve the model's stability and performance.
- Discrete Image Tokens: Show-o employs discrete denoising diffusion to simulate discrete image tokens, simplifying the need for an additional text encoder.
- Unified Prompting Strategy: Show-o designs a unified prompting strategy that tokenizes images and text to form input sequences, adapting to different types of tasks, such as multimodal understanding, text-to-image generation, etc.
- Full Attention Mechanism: Show-o introduces a full attention mechanism that can adaptively apply causal attention or full attention based on the type of input sequence. Text tokens use causal attention, while image tokens use full attention, supporting each image token to interact with all other tokens in the sequence.
- Training Objectives: Show-o adopts two learning objectives: next token prediction (NTP) and masked token prediction (MTP), simultaneously performing autoregressive and (discrete) diffusion modeling.
- Mixed-Modality Generation: Show-o demonstrates the potential for mixed-modality generation, such as generation based on text descriptions and video keyframes, providing new possibilities for long video generation.
- Reduced Sampling Steps: Compared with autoregressive image generation, Show-o requires about 20 times fewer sampling steps, reducing computational resource consumption and improving the model's application flexibility.
Show-o's Project Address
- Github Repository:https://github.com/showlab/Show-o
- arXiv Technical Paper:https://arxiv.org/pdf/2408.12528
- Online Experience Demo:https://huggingface.co/spaces/showlab/Show-o
Show-o Application Scenarios
- Social Media Content Creation: Users can provide text descriptions, and Show-o can generate corresponding images or videos to enrich the content of social media posts.
- Virtual Assistant: In virtual environments, based on user queries or instructions, Show-o can generate explanatory images or animations to provide visual assistance.
- Education and Training: Show-o can generate charts, diagrams, and example images for teaching materials, enhancing the learning experience.
- Advertising and Marketing: Based on product descriptions or marketing concepts, Show-o can quickly generate attractive visual content for advertising and promotion.
- Game Development: Show-o can generate unique game environments, characters, and item images for video game design.
- Film and Video Production: Show-o assists in pre-production by generating concept art and scene design drawings based on the script.