
What Is ShotAdapter
ShotAdapter is a framework launched jointly by Adobe and UIUC for text-to-multi-shotvideo generation. It is based on fine-tuning a pretrainedtext-to-videomodel and introduces transition tokens and a local attention masking strategy to achieve multi-shot video generation. The framework can ensure the identity consistency of characters across different shots and supports users in controlling the number, duration, and content of shots with specific text prompts. ShotAdapter introduces a new method for constructing multi-shot video datasets from single-shot video datasets, generating training data based on sampling, segmenting, and concatenating video clips.
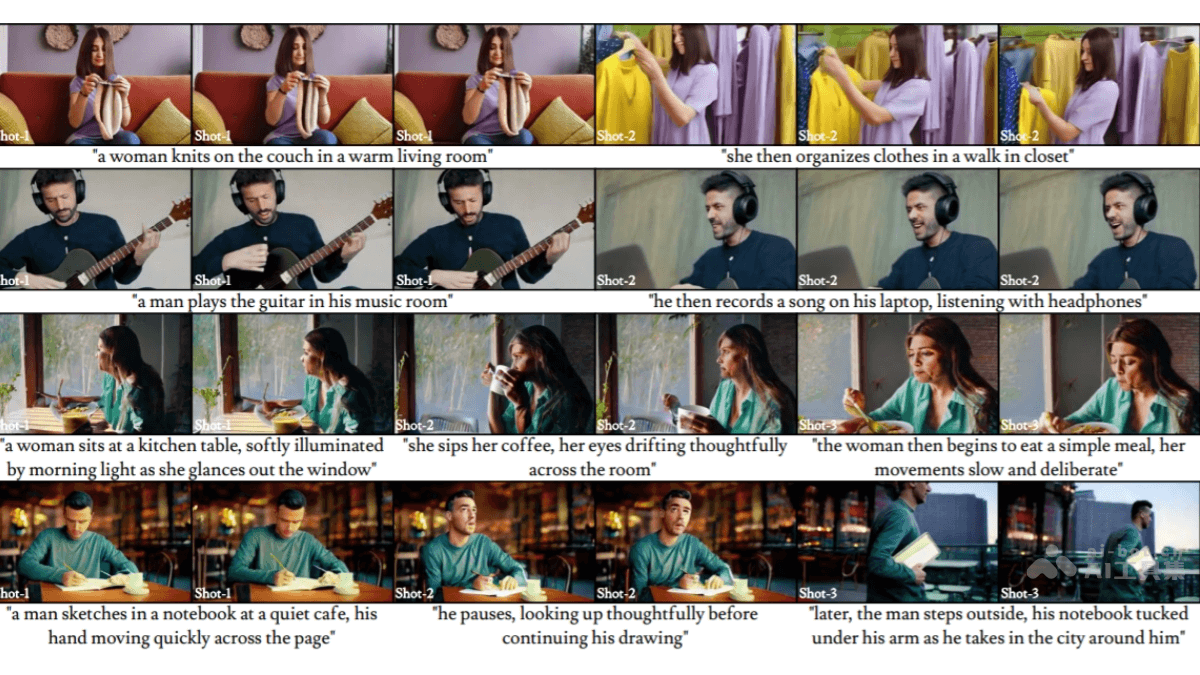
ShotAdapter's Main Features
- Multi-shot video generation: Generate videos containing multiple shots based on text descriptions, with each shot having different activities and backgrounds.
- Control over the number and duration of shots: Users can precisely control the number of shots in a video and the duration of each shot with text prompts.
- Character identity consistency: Maintain the identity consistency of characters across multiple shots.
- Background control: Support keeping the background consistent in a video or switching to a new background between shots, flexibly adjusted according to user needs.
- Shot-specific content control: Support users in controlling the content of each shot based on shot-specific text prompts, achieving fine-grained control over video details.
ShotAdapter's Technical Principles
- Transition tokens: Introduce special transition tokens used to indicate shot transitions in a video. The tokens are embedded into the text-to-video model, enabling the model to recognize and generate transitions between shots.
- Local attention masking: To ensure that the content of each shot closely corresponds to the text prompt, local attention masking is used. The masking strategy limits interactions between different parts of the model, so that each text prompt only affects the corresponding video frames, achieving shot-specific control.
- Fine-tuning a pretrained model: Based on fine-tuning a pretrained text-to-video model on a multi-shot video dataset, multi-shot videos are generated. The fine-tuning process requires only relatively few iterations (such as 5,000) to adapt the model to the multi-shot video generation task.
- Dataset construction: To train a multi-shot video generation model, a method is introduced for constructing multi-shot video datasets from single-shot video datasets. Based on sampling, segmenting, and concatenating video clips, as well as post-processing steps (such as identity consistency checking and shot-specific caption generation), a multi-shot video dataset suitable for training is created.
ShotAdapter's Project Address
- Project website:https://shotadapter.github.io/
- arXiv technical paper:https://arxiv.org/pdf/2505.07652
ShotAdapter's Application Scenarios
- Film and television production: Generate script previews, animations, and special effects videos to improve production efficiency.
- Advertising and marketing: Create attractive advertisements and social media videos to increase user engagement.
- Education: Assist teaching and training, and produce instructional videos and corporate training content.
- Game development: Generate game story videos and cutscenes to enhance the player experience.
- Personal creation: Help individuals create video diaries and creative videos, sparking inspiration.