
What is SenseNova V6
SenseNova V6 is launched by SenseTimeSenseNovathe sixth-generation multimodal fusion large model series, based on a 600-billion-parameter multimodal MoE architecture, achieving native fusion of text, images, and video. SenseNova V6 performs excellently in pure text tasks and multimodal tasks, with multiple indicators surpassingGPT-4.5、Gemini 2.0 Proand other models.
SenseNova V6 includes four versions. SenseNova V6 Pro is a 620-billion-parameter mixture-of-experts architecture model, supporting native fusion of text, images, and video, benchmarking against mainstream international models; SenseNova V6 Reasoner Pro has reasoning capabilities, assisting in solving complex problems; SenseNova V6 Video specializes in video understanding, suitable for scenarios such as teaching and cultural tourism; SenseNova V6 Omni is a lightweight full-modal interaction model, providing real-time interactive experience. SenseNova V6 has the characteristics of strong reasoning, strong interaction, and long memory. It performs reasoning and analysis on medium-to-long videos, accurately answers questions in real-time audio-video interaction, and provides emotional expression. The models are applied in fields such as educational tutoring and embodied intelligence, providing robots with a brain, eyes, ears, and mouth.
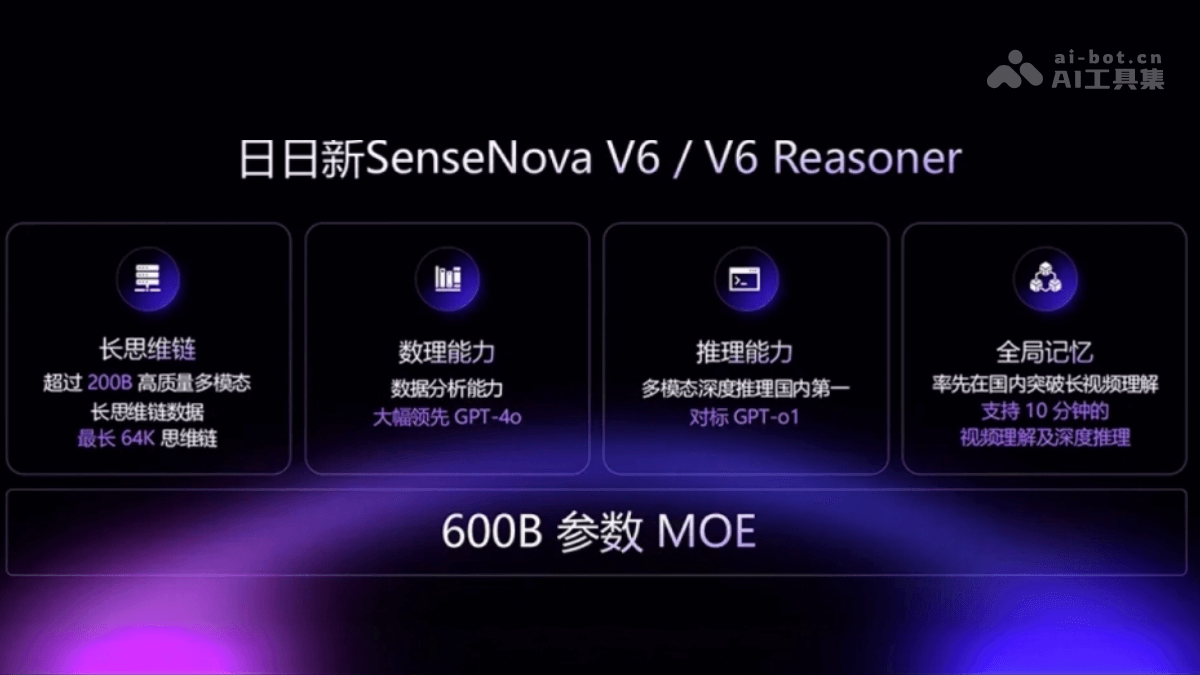
Main features of SenseNova V6
- Video processing and analysis: Supports reasoning and analysis of medium-to-long videos.
- Real-time audio-video interaction: Accurately answers questions about video content, such as character relationships, plot development, etc.
- Educational tutoring: Recognizes handwriting, tutors children in math problems, and provides one-on-one guided explanations.
- Emotional understanding and expression: Has highly anthropomorphic perception, expression, and emotional understanding capabilities, switching tone, emotion, and pitch according to different dialogue content and scenario needs.
- Embodied intelligence: Enables robots to have stronger perception and interaction capabilities.
Technical principles of SenseNova V6
- Native multimodal fusion training technology: Deeply integrates multiple modal information such as text, images, video, and audio in the model architecture and training process, avoiding the problem in traditional methods where enhancing one modal capability leads to a decline in another modal capability, and better handling complex scenarios and capturing cross-modal detail associations.
- Multimodal long chain-of-thought synthesis technology: Based on multi-agent collaboration, achieves the generation and verification of ultra-long chain-of-thought, enabling the model to have long-duration, multi-step deep thinking capabilities, suitable for scenarios such as mathematical derivation, scientific analysis, and long document understanding.
- Multimodal hybrid reinforcement learning: RLHF based on human preferences and RFT based on deterministic answers balance the model's logical reasoning ability and emotional expression ability, ensuring that the model naturally expresses emotions while improving reasoning ability.
- Unified representation and dynamic compression for long videos: Achieves efficient alignment and compression of cross-modal information, uniformly encodes visuals, speech, subtitles, and temporal logic to form coherent temporal representations, greatly improving processing efficiency.
Project address of SenseNova V6
- Project official website:https://platform.sensenova.cn
Application scenarios of SenseNova V6
- Video creation and analysis: Quickly generates video highlights, edits specific scenes, and adds narration and sound effects.
- Educational tutoring: Tutors math problems, provides one-on-one explanations, and helps students understand problem-solving approaches.
- Intelligent Customer Service: Accurately answers user questions, provides personalized suggestions, and enhances the user experience.
- Embodied Intelligence: Provides robots with perception and interaction capabilities, applied in scenarios such as home, industrial, and medical.
- Content Recommendation: Recommends personalized videos, articles, music, and other content based on user preferences.