
What Is SenseNova U1.5 Lite
SenseNova U1.5 Lite is a lightweight native unified multimodal large model open-sourced by SenseTime, designed specifically for real-world visual creation workflows. The model natively supports ultra-long instruction following of 3-4k characters, and features high-quality visual generation, reliable image editing, precise text layout, fine-grained visual control, and native 4K output capabilities. It can reliably complete complex visual delivery tasks such as posters and infographics, and is open-sourced for developers and creators worldwide.
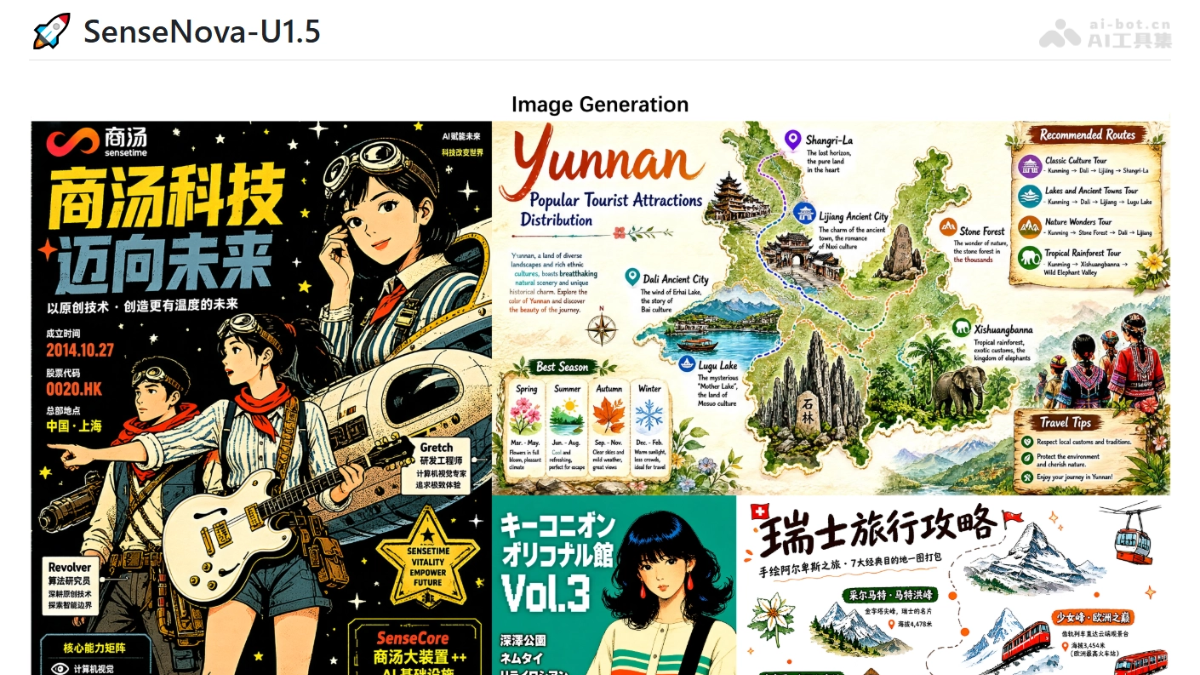
Main Features of SenseNova U1.5 Lite
-
Ultra-Long Instruction Following: Natively supports 3-4k character context, and can simultaneously handle multiple complex constraints such as subject, quantity, spatial relationships, text, layout, and style.
-
High-Quality Visual Generation: Improves composition, color, material, lighting, and realism, reducing the problem of locally correct but overall insufficient completion.
-
Native Image Editing: Enhances subject identity preservation and protection of non-edited regions, and supports local modifications, element replacement, text refinement, and multi-reference image editing.
-
Text and Complex Layout: Strengthens Chinese and English text rendering, and multi-text layout capabilities for posters, infographics, and brand visuals.
-
Fine-Grained Visual Control: Supports Bounding Box, Visual Marker, and single-image/multi-image references to achieve precise editing of specified regions and objects.
-
Native 4K Output: Balances overall composition with extremely fine textures, tiny text, and light and shadow refraction in high-resolution generation.
Technical Principles of SenseNova U1.5 Lite
-
Data and Task Restructuring: The model re-improves the training data distribution and task design around real-world visual delivery needs, building specialized training data for core capabilities such as complex instruction following, text layout, image editing, and 4K generation, ensuring that the model's capabilities shift from pursuing "visual aesthetics" to "reliably completing real visual tasks."
-
Post-Training Process Optimization: Through post-training processes in dimensions such as enhanced visual quality, complex instruction following, text and layout, native 4K, native image editing, and fine-grained visual control, it systematically improves the model's execution stability and controllability in real creation scenarios, enabling each capability to enter actual workflows more accurately and stably.
-
Native Unified Multimodal Architecture: As a lightweight native unified multimodal large model, its architecture achieves deep fusion of text and visual information, enabling the model to directly understand complex image-text instructions and complete generation and editing tasks within a unified framework, without the need for additional modality conversion or stitching modules, achieving efficient visual creation capabilities at the 8B parameter scale.

Follow WeChat and reply "Open Source" to join theAI Open Source Project Exchange Group
How to Use SenseNova U1.5 Lite
- Online Experience: Visit the SenseNova Studio official website https://unify.light-ai.top/可在网页端直接体验,无需本地部署。
- Open-Source Deployment: Go to the GitHub repositoryhttps://github.com/OpenSenseNova/SenseNova-U1下载源码,在本地或服务器上直接部署运行。
- Get Model Weights: Visit the Hugging Face model library https://huggingface.co/collections/sensenova/sensenova-u15下载模型文件,集成到自有框架中推理使用。
Core Advantages of SenseNova U1.5 Lite
- Ultra-Long Instruction Understanding and Execution: Natively supports ultra-long complex instructions of 3-4k characters, and can accurately parse and execute visual tasks containing multiple constraints such as subjects, quantities, spatial relationships, text, layout, and style.
- Stability in Real Creative Workflows: Shifts from pursuing visual aesthetics to real visual delivery, ensuring that generation and editing capabilities are stably usable and precisely controllable in complex creative workflows.
- Precise Image Editing: Has reliable native image editing capabilities, and can keep the subject identity, spatial structure, and non-edited areas intact while modifying local elements.
- Text and Complex Layout: Strengthens Chinese and English text rendering and complex layout, and can complete multi-text layout tasks such as posters, infographics, and brand visuals with high quality.
- Fine Visual Control: Supports fine visual control methods such as Bounding Box, Visual Marker, and multi-image reference, enabling precise editing of specified areas and objects.
- Native 4K HD Output: Supports native 4K high-resolution output, balancing overall composition with extremely fine textures, tiny text, and light and shadow refraction at ultra-high resolution.
Project Address of SenseNova U1.5 Lite
- GitHub Repository:https://github.com/OpenSenseNova/SenseNova-U1
- HuggingFace Model Library:https://huggingface.co/collections/sensenova/sensenova-u15
Comparison of SenseNova U1.5 Lite with Similar Competing Products
| Comparison Dimension | SenseNova U1.5 Lite | Janus-Pro-7B |
|---|---|---|
| Parameter Scale | 8B (MoT Architecture) | 7B |
| Model Positioning | Native unified multimodal generation and editing model, focused on real visual creative delivery | Unified multimodal understanding and generation model, emphasizing a balance between visual understanding and generation |
| Instruction Length | Natively supports ultra-long complex instruction following of 3-4k characters | Mainly supports text instructions of conventional length, with limited ability to follow ultra-long complex instructions |
| Image Editing | Native image editing, supporting local modification, element replacement, and preservation of non-edited areas | Has basic image generation capabilities, with weaker native image editing and area preservation capabilities |
| Text Rendering | Strengthens Chinese and English text, complex poster layout, and infographic layout | Text rendering capability is average, and complex layout and infographic generation are not its core strengths |
| Resolution Output | Supports native 4K high-resolution output | Mainly supports generation at conventional resolutions |
| Visual Control | Supports fine control such as Bounding Box, Visual Marker, and multi-image reference | Visual control methods are relatively limited |
Application Scenarios of SenseNova U1.5 Lite
-
Creative Poster and Cover Design: Generates posters, magazine covers, and key event visuals with high aesthetic completion based on ultra-long image-text instructions, precisely controlling text layout, spatial hierarchy, and style tone.
-
Infographics and Data Visualization: Transforms complex data, travel guides, knowledge popularization, and other content into high-density infographics with clear structure and mixed text and images, ensuring text accuracy and coherent visual logic.
-
Brand Visuals and Marketing Materials: Quickly generates series of visual materials with a unified style for brands, including product packaging, social media images, and advertising banners, while maintaining consistency in brand fonts and visual elements.
-
E-commerce Product Image Editing and Optimization: While preserving the main product and background, perform local element replacement, text refinement, and lighting adjustment to achieve low-cost, high-efficiency product image iteration.
-
Social Media Content Creation: Provide creators with one-stop support from concept to finished image, generating image-and-text content with refined layout and personalized text, suited to the high-frequency publishing needs of platforms such as Xiaohongshu and Instagram.