
What Is SenseNova U1.5-Lite-Preview
SenseNova U1.5-Lite-Preview is a preview version of SenseTime's open-source lightweight native unified multimodal model. Iterated on the NEO-Unify architecture, it achieves end-to-end integration of visual understanding, reasoning, generation, and editing with only 8B-MoT parameters. The model natively supports 4K image generation, featuring fine local textures, real-world materiality, Chinese and English text generation, and complex layout capabilities. It is optimized for precise adherence to ultra-long natural language and structured visual instructions, and comes with a Prompt Enhance Skill to lower the barrier to complex creation.
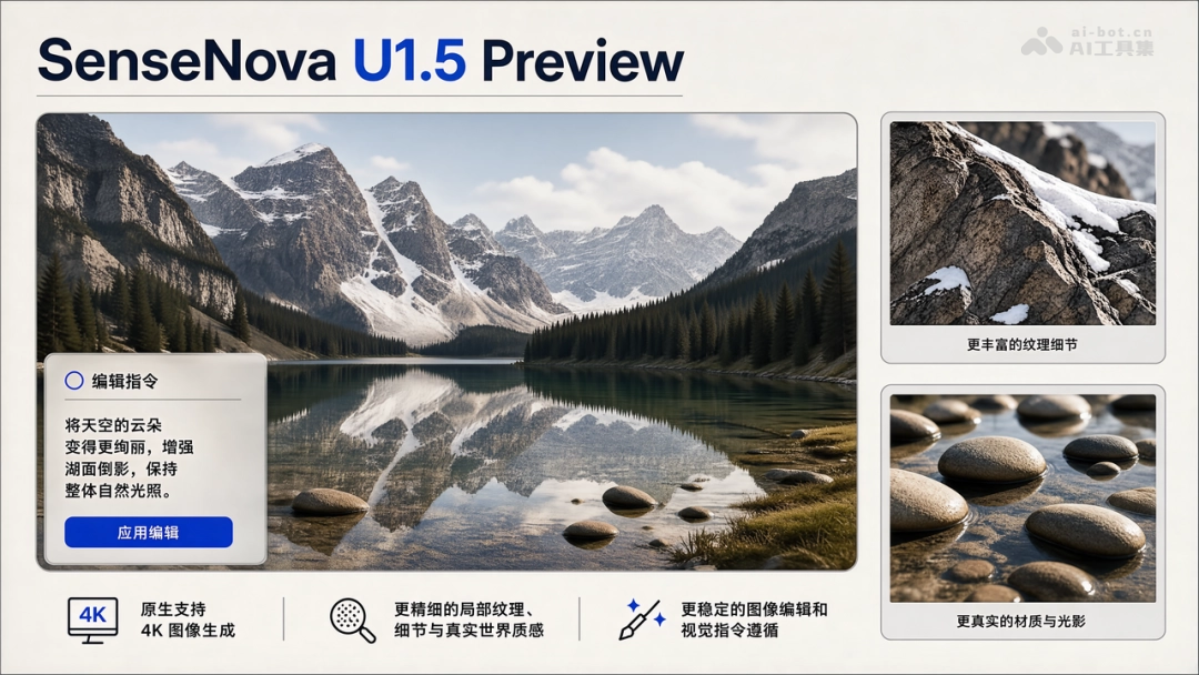
Main Features of SenseNova U1.5-Lite-Preview
-
4K Native Generation: Supports end-to-end generation of ultra-high-resolution images, with details that hold up under magnification.
-
Fine Visual Texture: Presents more realistic material textures, light and shadow layering, and local details.
-
Chinese and English Text Generation: Accurately renders Chinese and English text and typography in complex layouts.
-
Image Editing and Iteration: Supports sustainable iterative image editing based on natural language instructions.
-
Prompt Enhance Skill: Automatically expands brief requirements into complete creative proposals, lowering the barrier to writing instructions.
Technical Principles of SenseNova U1.5-Lite-Preview
-
NEO-Unify Unified Architecture: Jointly models language, visual semantics, and pixel generation within a single model, achieving native unification of understanding, reasoning, generation, and editing.
-
8B-MoT Lightweight Design: Adopts a hybrid token architecture with only 8 billion parameters, expanding the boundaries of multimodal capabilities while remaining lightweight, and validating the continuous scalability of the unified architecture.
-
Native Pixel-Language Mapping: Trained end-to-end from pixels and language, the model learns a native mapping capability from language descriptions to visual structures.
-
Long-Context Visual Control: The model is optimized for understanding ultra-long natural language and structured creative instructions, supporting precise execution of multi-constraint, hierarchical visual instructions.

Follow WeChat and reply "open source" to join theAI Open-Source Project Communication Group
How to Use SenseNova U1.5-Lite-Preview
- Obtain the Model and Documentation: Visit the GitHub repository to view technical documentation and inference code, or download the 8B-MoT model weights and configuration files on Hugging Face.
- Environment Deployment: Configure the runtime environment and load the model weights according to the documentation to complete local or cloud-based model initialization.
- Basic Image Generation: Directly input a natural language description (Chinese and English supported), and the model can natively generate 4K images.
- Complex Creative Instructions: Provide complete creative requirements including subject, layout, style, text, and constraints, and the model executes generation according to the explicit visual structure.
- Prompt Enhance Assistance: Invoke the experimental Prompt Enhance Skill to automatically expand brief ideas into complete creative proposals, then submit them to the model for execution.
- Image Editing Operations: Upload an existing image and attach natural language editing instructions, and the model completes sustainable iterative editing while maintaining overall consistency.
Core Advantages of SenseNova U1.5-Lite-Preview
-
Lightweight and Unified: With only 8B-MoT parameters, it achieves integrated understanding, generation, and editing, reducing deployment costs.
-
4K Ultra HD: Natively supports 4K resolution generation, maintaining detail and consistency even at ultra-large canvas sizes.
-
Strong Instruction Following: Even without dedicated Prompt Enhance formatting training, it can still reliably execute long and complex visual instructions.
-
Realistic Texture: Significantly improves local textures, material lighting and shadow, and real-world texture expression.
-
Text Stability: Chinese and English text generation and complex layout organization are more accurate and stable.
Project address of SenseNova U1.5-Lite-Preview
- GitHub Repository:https://github.com/OpenSenseNova/SenseNova-U1/blob/main/docs/u1.5_preview.md
- HuggingFace Model Library:https://huggingface.co/sensenova/SenseNova-U1.5-8B-MoT-Preview
Comparison of SenseNova U1.5-Lite-Preview with similar competing products
| Dimension | SenseNova U1.5-Lite-Preview | Emu3(BAAI) |
|---|---|---|
| Architecture Route | NEO-Unify native unified multimodal, integrating understanding/reasoning/generation/editing | Native unified multimodal, unifying image understanding and generation under an autoregressive framework |
| Open-Source Scale | 8B-MoT lightweight open source, oriented toward community preview | Provides open-source versions in multiple sizes (such as 8B), with complete training code and data pipeline |
| Resolution Support | Natively supports 4K image generation, with outstanding detail and consistency | Supports high-resolution generation, mainly focusing on conventional sizes and video frame generation |
| Core Capabilities | Ultra-long instruction following, 4K Ultra HD, Chinese and English text rendering, continuously iterable editing | Image understanding, text-to-image generation, video prediction, emphasizing multimodal unification |
| Text and Layout | Specialized optimization for Chinese and English text generation and complex layouts, with high stability | Text generation capability exists, but layout control and long-text accuracy are relatively limited |
| Positioning | Lightweight unified multimodal base preview version, focusing on visual creation and editing | Open-source unified multimodal foundation model, focusing on research validation and the multimodal unification paradigm |
Application scenarios of SenseNova U1.5-Lite-Preview
- Commercial Brand Visual Design: Rapidly generate posters, infographics, and brand promotional materials containing precise Chinese and English text, complex layouts, and specified visual styles, meeting commercial creation needs with a high control ceiling.
- Ultra-Wide Narrative Long Scrolls: Create ultra-wide continuous narrative content such as historical timelines and cultural long scrolls in 4K Ultra HD resolution, where large amounts of text and icon details remain clear and stable even when enlarged.
- Architectural and Product Concept Visualization: Produce highly realistic architectural exterior renderings, interior space concept images, and product display images, presenting realistic material textures, lighting and shadow layers, and spatial atmosphere.
- Photographic Portraits and Close-ups: The model can generate portrait photography, facial close-ups, and character-themed works with fine skin textures, natural lighting and shadow, and realistic texture, supporting complex compositions and style specification.
- Retro and Collage Art Creation: The model supports stylized visual creation with multi-element fusion such as retro journals, collage posters, and natural history illustrations, accurately presenting details such as paper texture, stamps, and handwritten text.