
What is SenseAudio
SenseAudio is an AI voice open platform launched by SenseTime, focusing on "natural, pleasant, and emotionally rich AI voices." The platform integrates 70+ premium voices and providestext-to-speech、voice cloning(cloning possible with just 3 seconds of material), vocal extraction, speech recognition (supporting 20+ languages) and other core capabilities, while also covering AI audio and video creation, virtual character dialogue, intelligent voice input methods, and other features. It opens APIs to developers, supports voice cloning and text-to-voice calls, and is suitable for content creation, intelligent customer service, accessible communication, and many other scenarios, committed to making AI voices more natural and easier to use.
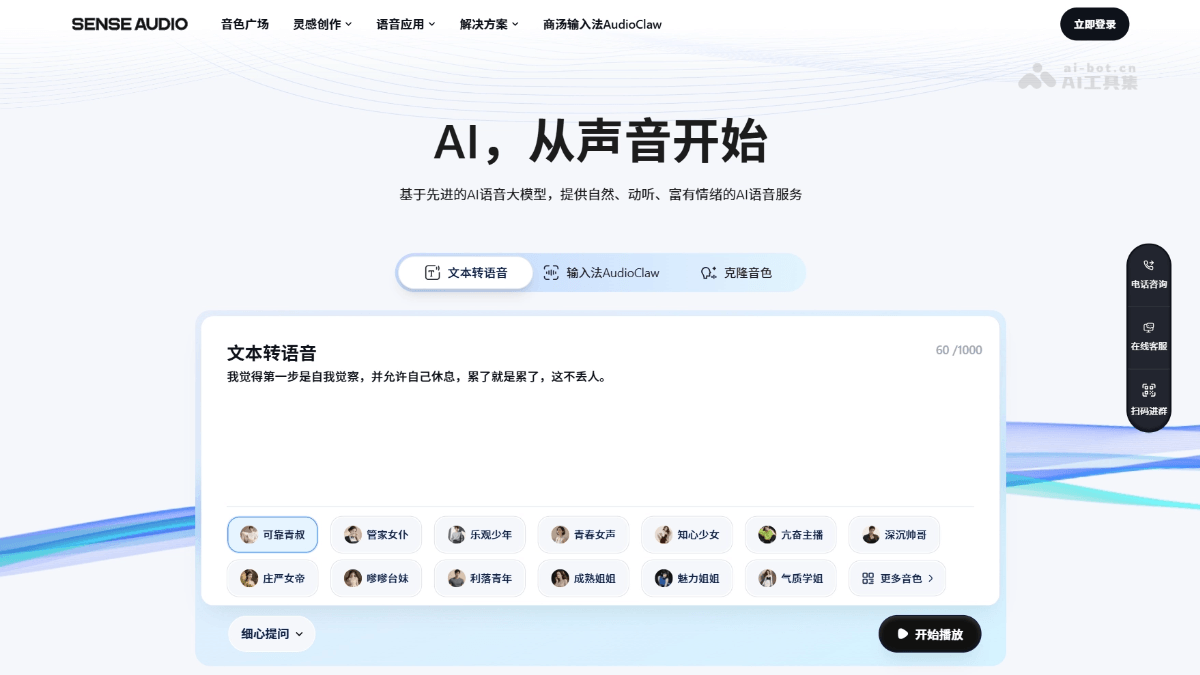
SenseAudio's main features
-
Text-to-speech: Provides more than 70 premium voices and supports a variety of delicate emotion adjustments, making AI voices more natural and pleasant.
-
Voice cloning: Requires only 3 seconds of audio material to highly restore a voice, accurately replicating emotions and voice details, with support for both Chinese and English.
-
Text-to-voice: Supports directly generating personalized voices that match your imagination through text descriptions, as convenient as AI image generation.
-
Vocal extraction: Can intelligently separate vocals from complex environmental noise or music, with support for uploading video and audio files for processing.
-
Speech recognition: Equipped with mature and stable speech recognition technology, covering more than 20 languages and quickly and accurately converting speech to text.
-
Inspiration creation: Integrates AI video generation and audio-video editing tools, serving as both an entertainment creation platform and a practical productivity tool.
-
Character plaza: Supports extremely low-latency real-time calls with virtual characters, experiencing realistic tones and a variety of dialogue scenarios.
-
AI intelligent voice input method: Automatically corrects slips of the tongue, achieves structured output, and completes intelligent translation and expansion with voice commands.
-
Developer API: Opens capability interfaces such as voice cloning, speech synthesis, and speech recognition, with support for calling the SenseAudio-TTS-1.5 model.
SenseAudio's key information and usage requirements
-
Developer: SenseTime
-
Product positioning: AI voice open platform + audio and video creation tool
-
Core model: SenseAudio-TTS-1.5 (SOTA-level speech synthesis)
-
Number of voices: 70+ professional premium voices
-
Supported languages: Chinese, English, and 20+ languages for recognition
-
Cloning material requirements: 3-30 seconds of audio, within 30MB, supporting MP3/WAV/M4A/AAC
-
API services: Supports calling capabilities such as voice cloning, TTS, and ASR
-
Registration method: Register an account on the official website; some features require credits
-
File formats: Audio supports MP3, WAV, M4A, and AAC formats
-
Duration limit: Voice cloning material must be kept within 3-30 seconds
-
Size limit: A single audio file must not exceed 30MB
SenseAudio's core advantages
-
Natural emotional expression: Focuses on AI voices that are "naturally pleasant and emotionally rich," eliminating mechanical feel and making synthesized speech closer to human expression.
-
Ultra-fast voice cloning: Just 3 seconds of audio material can highly restore the timbre, accurately replicate emotions and details, and greatly lower the barrier to use.
-
Rich and diverse voice options: Provides 70+ professional premium voices, covering multiple application scenarios and delicate emotions to meet personalized needs.
-
Strong multilingual capability: Supports recognition of Chinese, English, and 20+ languages, suitable for global business scenarios.
-
Creative tool integration: Integrates AI video generation, audio and video editing, vocal extraction, and speech recognition in one, meeting creative needs in a one-stop manner.
-
SOTA-level model: Equipped with the SenseAudio-TTS-1.5 model, its speech synthesis technology is at the industry-leading level.
-
Flexible API invocation: Opens capability interfaces such as voice cloning, TTS, and ASR, making it convenient for developers to quickly integrate into their own products.
How to use SenseAudio
-
Visit the official website: Visit the SenseAudio official website https://senseaudio.cn/ to complete account registration, and you can enter the platform homepage.
-
Choose a feature: On the homepage, choose the desired feature entry, including eight major modules such as text-to-speech, voice cloning, and vocal extraction.
-
Text-to-speech: Enter the text content to be converted, choose your preferred voice from 70+ voices and adjust emotion parameters, and generate natural and pleasant AI speech with one click.
-
Voice cloning: Upload a 3-30 second audio file that meets the format requirements or record directly. After the system automatically learns the timbre features, you can use that voice to generate new content.
-
Vocal extraction: Upload an audio or video file containing background sound, and the platform automatically separates and extracts a clear vocal track.
-
Speech recognition: Upload an audio file or record in real time, and the system quickly and accurately converts speech into text, supporting more than 20 languages.
-
Inspiration creation: Choose a video creation template and combine AI video generation with audio and video editing tools to complete one-stop content creation.
-
Character call: Choose a virtual character in the character plaza, and click the call button to experience real-time voice interaction with extremely low latency.
Comparison of SenseAudio with similar competitors
| Comparison dimension | SenseAudio (SenseTime) |
Xunfei Zhizuo (iFLYTEK) |
Moyin Gongfang (Mobvoi) |
|---|---|---|---|
| Developer | SenseTime | iFLYTEK | Mobvoi |
| Core positioning | AI voice open platform + audio and video creation | Professional AI dubbing and video production | AI dubbing and digital humans |
| Number of voices | 70+ premium voices | 100+ featured speakers | 1000+ voices |
| Voice cloning | 3 seconds of material, highly restores emotional details | Requires 1-3 minutes of material | Supported, requires material of a certain length |
| Emotional expression | Focuses on "natural and pleasant sound, full of emotion" | Mature emotional synthesis technology | Supports multiple emotional styles |
| Featured functions | AI video creation, character calls, smart input method | Virtual streamers, multilingual simultaneous interpretation | Digital human avatars, multilingual dubbing |
| Speech recognition | Supports 20+ languages | Industry-leading speech technology | Supports mainstream languages |
| Open API | Supports interfaces such as TTS/ASR/cloning | Provides complete developer interfaces | Provides API services |
Application scenarios of SenseAudio
-
Content creation: Provides high-quality AI speech for short videos, podcasts, audiobooks, and advertising dubbing, supports emotion adjustment and voice cloning, and creates personalized content.
-
Smart customer service: Through natural and emotional voice interaction, it improves the service experience of robotic customer service and reduces labor costs.
-
Education and training: Converts textbook content into speech, supports multilingual pronunciation, and assists language learning and visually impaired students in accessing knowledge without barriers.
-
Film and television production: Supports rapid generation of dubbing drafts, and the vocal extraction function assists post-production audio processing, improving production efficiency.
-
Games and entertainment: Customizes exclusive voices for game characters, and the character plaza supports real-time voice interaction, enhancing immersion.