
What is Seedance 1.0
Seedance 1.0 is launched by ByteDance's Seed teamvideo generationfoundation model. The model supports text and image input, can generate 1080p high-quality videos with seamless multi-shot switching, has native multi-shot narrative capabilities, can switch between long, medium, and close-up shots, with stable subject motion and natural visuals. Seedance 1.0 supports creation in multiple styles, such as realistic, anime, and film/TV, and has fast generation speed and low cost. On the third-party evaluation leaderboard Artificial Analysis, Seedance 1.0 ranks first in both text-to-video and image-to-video tasks, demonstrating strong performance and advantages in the field of video generation.
Main features of Seedance 1.0
- Multi-shot narrative capability: Supports generating narrative videos containing multiple coherent shots, can switch between long, medium, and close-up shots, and ensures high consistency of the core subject, visual style, and overall atmosphere.
- Smooth and stable motion performance: The model can generate videos with large-scale motion, maintaining a high level of stability and physical realism from subtle expressions to dynamic scenes.
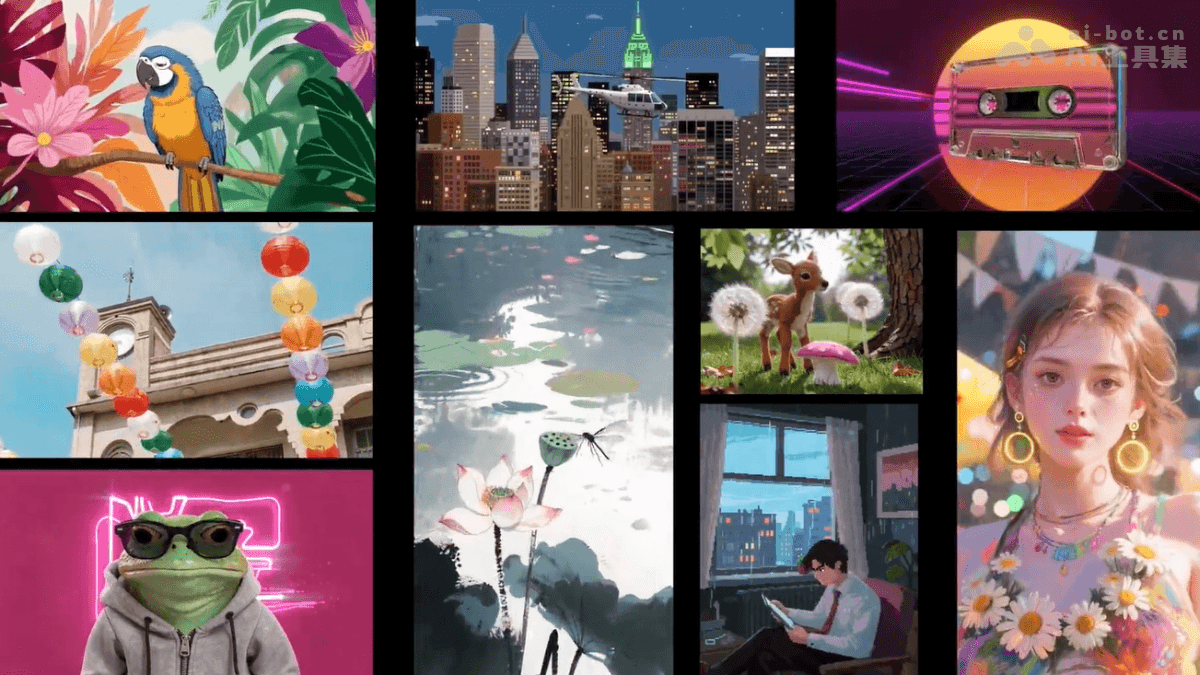
- Creation in multiple styles: Supports video generation in multiple styles, including realistic, anime, film/TV, advertising, and more.
- Precise semantic understanding and instruction following: The model can accurately parse complex natural language instructions, stably control multi-subject interactions and combinations of multiple actions, and support rich camera movement options.
- High-speed inference and low cost: Based on optimization of the model structure and inference acceleration, Seedance 1.0 supports completing video creation in a short time. For a 5-second 1080p resolution video generation task, the measured inference time is only 41.4 seconds (based on NVIDIA L20 testing), significantly lower than other similar models.
Technical principles of Seedance 1.0
- Multi-source data organization and precise description model: Based on multi-stage filtering and balancing, a large-scale, diverse video dataset was built, covering different themes, scenes, styles, and camera movements. A dense description model integrating dynamic and static features was trained to generate precise video descriptions (Caption) as training data. The model focuses on action changes and camera movements in videos, emphasizing the properties and characteristics of the main elements in the frame and scene information.
- Efficient pre-training framework: A diffusion Transformer model with decoupled spatial and temporal layers was built. The spatial layer performs attention aggregation within a single frame, and the temporal layer focuses on cross-frame attention computation, improving training and inference efficiency. It supports interleaved sequences of visual tokens and text tokens, extends to multi-shot video training, and enhances the model's multi-shot generation capability and multimodal understanding. Based on a binary mask indicating which frames should follow the control conditions during generation, it implements a unified framework for tasks such as text-to-image, text-to-video, and image-to-video.
- Post-training optimization and composite reward system: In the fine-tuning stage, a high-quality video-text pair dataset is used for training to ensure that the generated videos perform better in aesthetic effects and motion dynamics. A composite reward system including a base reward model, a motion reward model, and an aesthetic reward model was built to improve the model's performance in image-text alignment, motion quality, and visual aesthetics based on multi-dimensional reward models. By maximizing the reward values of multiple reward models, combined with the RLHF (Reinforcement Learning from Human Feedback) algorithm, the model's overall performance in text-to-video and image-to-video tasks is improved.
- Extreme inference acceleration: An adversarial distillation mechanism based on segmented trajectory consistency, score matching, and human preference guidance achieves a better synergy between generation quality and speed at extremely low inference steps. A lightweight VAE decoder with channel-structure refinement achieves lossless perceptual-quality twofold acceleration in the video generation pipeline. Based on system-level transformations such as fused operator optimization, heterogeneous quantization and sparsity strategies, adaptive hybrid parallelism, asynchronous offloading, and VAE parallel decomposition, an efficient inference path for long-sequence video generation is constructed, achieving a better synergy between end-to-end throughput and memory efficiency.
Performance of Seedance 1.0
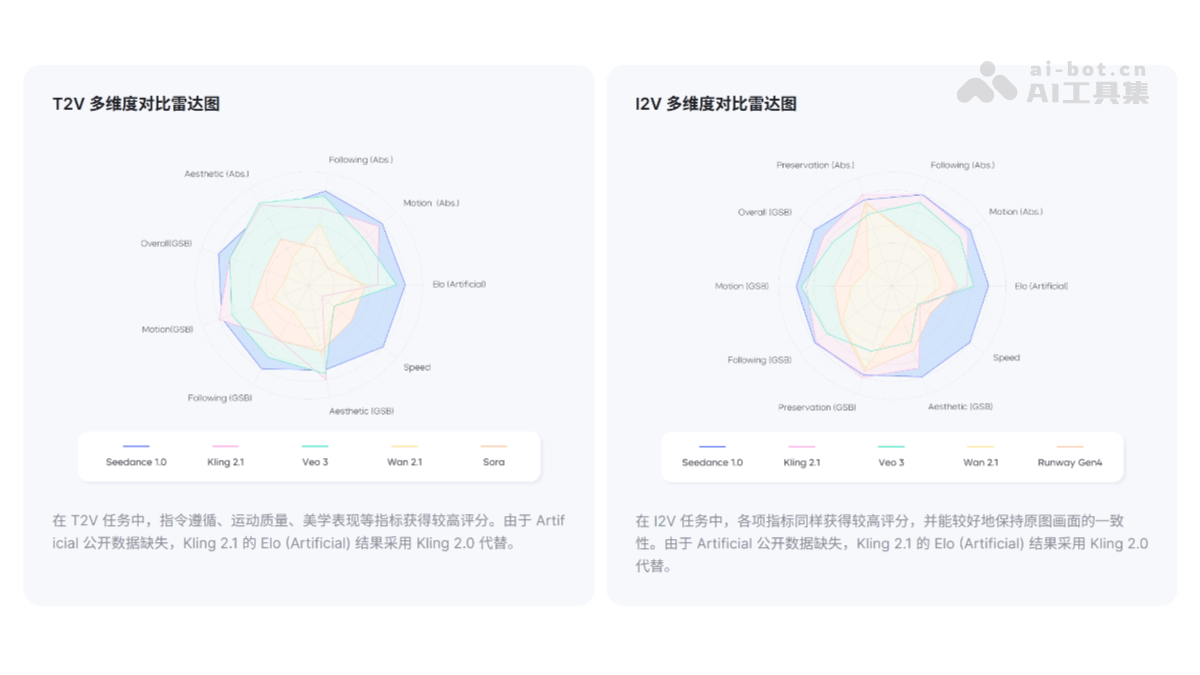
- On the third-party evaluation platform Artificial Analysis, Seedance 1.0 ranks first in both text-to-video (T2V) and image-to-video (I2V) tasks.
- In internal benchmark tests comparing Seedance 1.0 with other industry models, Seedance 1.0 performs well across multiple core dimensions such as instruction following, motion quality, and aesthetic expression. In the T2V task, it achieves relatively high scores on metrics including instruction following, motion quality, and aesthetic expression.
Official examples of Seedance 1.0
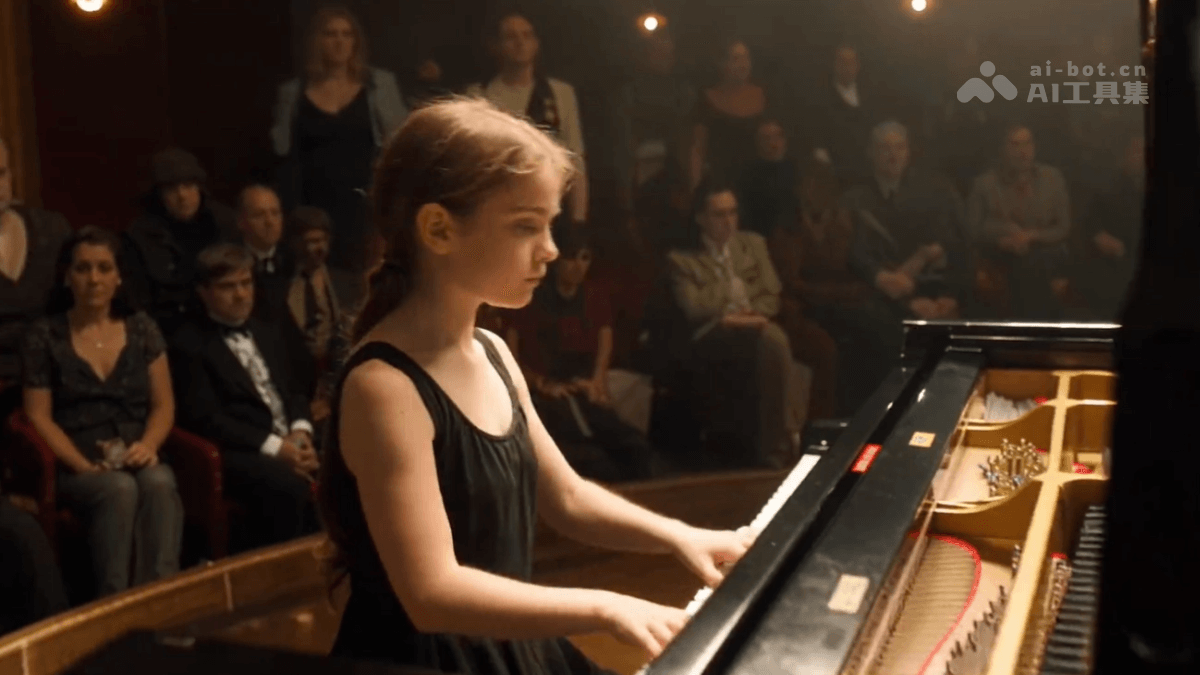
- Native multi-shot narrative capability:
- Prompt: A girl playing the piano, multi-shot switching, cinematic quality (I2V).
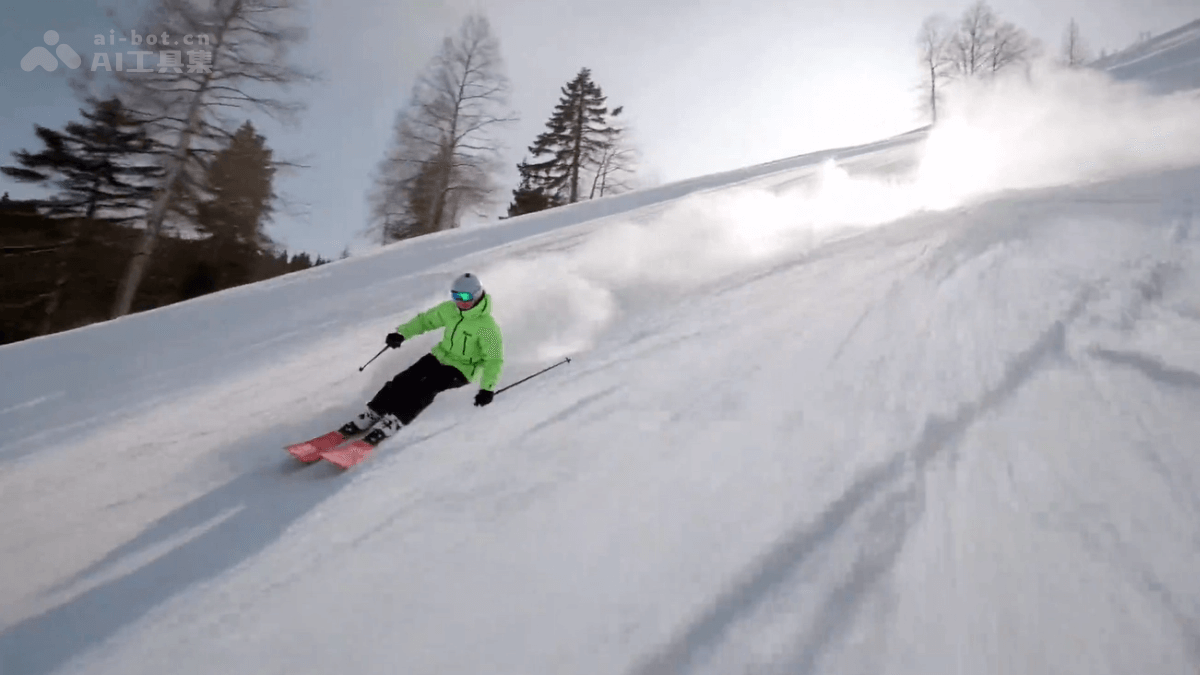
- Stronger motion generation performance:
- Prompt: A skier is skiing; as he turns, he kicks up a large cloud of snow, gradually accelerating along the slope while the camera moves smoothly.
- Supportshighly aestheticcreation in multiple styles:
Project address of Seedance 1.0
- Project official website:https://seed.bytedance.com/zh/seedance
- Technical paper:https://lf3-static.bytednsdoc.com/obj/eden-cn/bdeh7uhpsuht/Seedance
Application scenarios of Seedance 1.0
- Film and television production: Generate narrative videos containing multiple shot transitions, support complex narrative structures, and enhance the narrative capability and visual effects of videos.
- Advertising and marketing: Quickly generate high-quality advertising videos, support multiple styles and scenarios, and meet the advertising needs of different brands and products.
- Game development: Generate cutscenes and dynamic scenes in games, enhancing the narrative quality and immersion of games.
- Education and training: Generate educational videos and training materials to help students and employees better understand and master knowledge.
- News and media: Generate dynamic content in news reports and documentaries, enhancing the visual effects of news and documentaries.