
What is SAM 3
SAM 3 (Segment Anything Model 3) is Meta AI's latest advanced computer vision model, capable of detecting, segmenting, and tracking objects in images and videos through text, examples, and visual prompts. The model supports open-vocabulary phrase input, possesses powerful cross-modal interaction capabilities, and can correct segmentation results in real time. SAM 3 delivers outstanding performance in image and video segmentation tasks, twice that of existing systems, and supports zero-shot learning. The model extends to the field of 3D reconstruction, empowering multi-scenario applications such as home previews, creative video editing, and scientific research, providing strong momentum for the future development of computer vision.
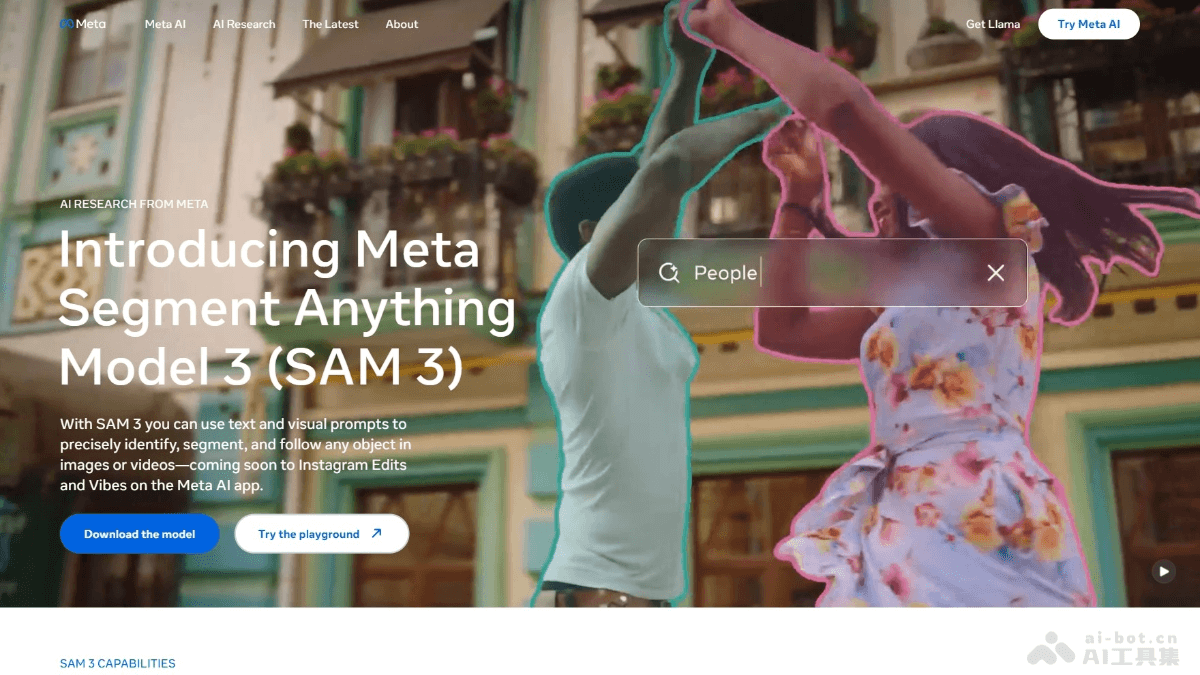
SAM 3's Main Features
-
Multi-modal Prompt Support: SAM 3 supports detecting and segmenting objects in images and videos through text, examples, and visual prompts (such as clicks and box selections), adapting to various user needs.
-
Image and Video Segmentation: SAM 3 can detect and segment all matching objects in images, supports tracking objects in videos, and can interactively correct segmentation results in real time.
-
Zero-Shot Learning: SAM 3 can handle unseen concepts through open-vocabulary text prompts, segmenting new object categories without additional training.
-
Real-Time Interactivity: Supports users in correcting model errors by adding additional prompts (such as clicks or box selections), further optimizing segmentation results and enhancing user experience.
-
Cross-Domain Applications: SAM 3 is widely used in creative media tools (such as Instagram Edits), home decoration previews (such as Facebook Marketplace), and scientific fields (such as wildlife monitoring).
SAM 3's Technical Principles
- Unified Model Architecture: SAM 3 is based on a unified model architecture that simultaneously supports segmentation tasks in images and videos. The model combines a powerful visual encoder (such as Meta Perception Encoder) and a text encoder, capable of processing open-vocabulary text prompts. The model architecture includes an image-level detector and a memory-based video tracker, both sharing the same visual encoder.
- Multi-modal Input Processing:
- Text Encoder: Encodes text prompts into feature vectors, used to guide segmentation tasks.
- Visual Encoder: Encodes images or video frames into feature vectors, used to detect and segment objects.
- Fusion Encoder: Fuses text and visual features to generate conditioned image features for subsequent segmentation tasks.
- Presence Head: To improve the model's classification capability, SAM 3 introduces a Presence Head, specifically used to predict whether the target concept exists in the image or video. This helps decouple recognition and localization tasks, improving the model's accuracy and efficiency.
- Large-Scale Data Engine: To train SAM 3, Meta built an efficient data engine, combining human annotation and AI-assisted annotation to generate high-quality annotated data for over 4 million unique concepts. The data covers multiple visual domains and tasks, ensuring the model has broad generalization capabilities.
- Zero-Shot Learning: SAM 3 supports zero-shot learning, capable of handling unseen concepts. Through open-vocabulary text prompts, the model uses pre-trained visual and language encoders to recognize and segment new object categories.
- Real-Time Interactivity: SAM 3 supports real-time interactivity, allowing users to correct the model's errors by adding additional prompts (such as clicks or box selections), further optimizing the segmentation results. The interactivity enables the model to better adapt to the user's intent.
- Video tracking and segmentation: In video tasks, SAM 3 uses a memory-based tracker to handle the spatiotemporal consistency of objects. The tracker uses the detector's output and historical information in memory to generate high-quality segmentation masks and propagate the masks across video frames.
SAM 3 project address
- Project official website:https://ai.meta.com/sam3/
- GitHub repository:https://github.com/facebookresearch/sam3/
- Online experience Demo:https://www.aidemos.meta.com/segment-anything
SAM 3 application scenarios
-
Creative media tools: Creators can quickly apply special effects to people or objects in videos, improving creative efficiency.
-
Home decor preview: In Facebook Marketplace, SAM 3 supports the "room preview" feature, allowing users to preview the effect of home decor items in their own space and assisting purchasing decisions.
-
Scientific applications: SAM 3 is used in wildlife monitoring and ocean exploration, helping researchers better understand and protect the natural environment, for example by analyzing wildlife behavior through video.
-
3D reconstruction: SAM 3D can reconstruct 3D objects and human bodies from a single image, providing a new standard for 3D reconstruction in physical world scenarios and empowering virtual reality and augmented reality applications.
-
Video creation: SAM 3 provides AI visual creation tools and supports remixing existing AI-generated videos, improving creative flexibility.