
What are Qwen3-VL Cookbooks
Qwen3-VL Cookbooks is a collection of practical guides launched by Alibaba for the Qwen3-VL model, helping users quickly master and apply the model's various functions. The collection covers usage examples for a variety of capabilities, including object recognition, document parsing, video understanding, spatial understanding, multimodal coding, and more. Each Cookbook provides detailed code examples and operating steps, enabling users to quickly learn through examples how to use the Qwen3-VL model in real-world scenarios and better leverage the model's powerful visual-language capabilities.
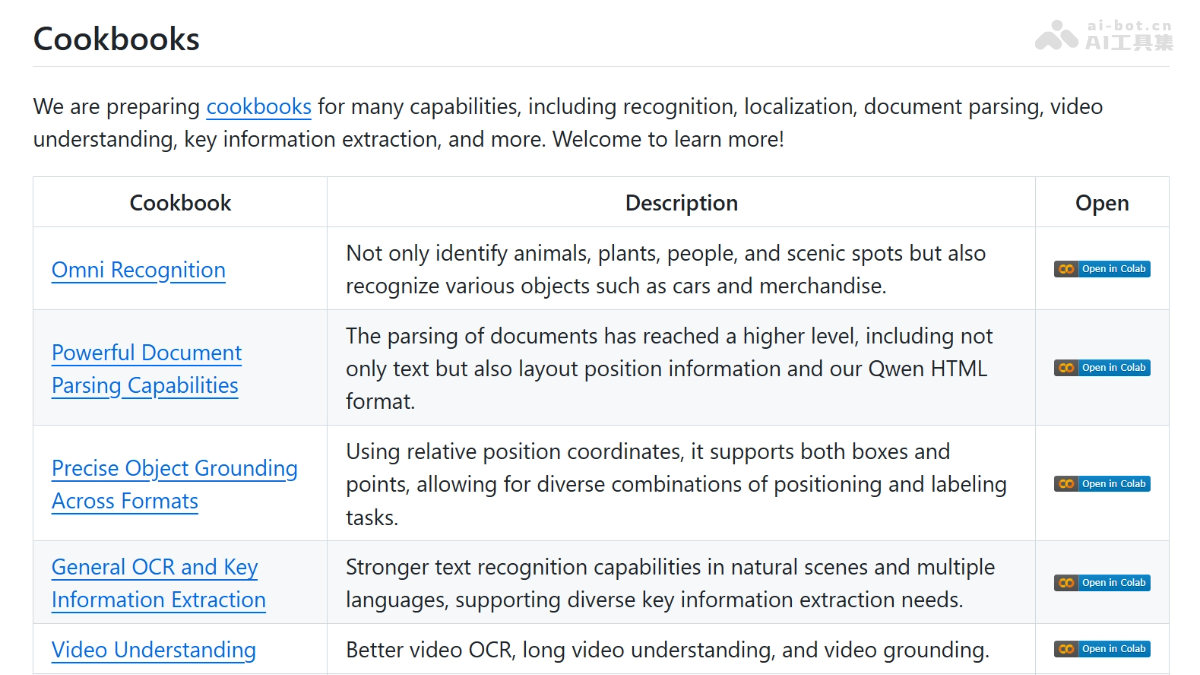
Main Features of Qwen3-VL Cookbooks
-
Provides detailed operating guides: Helps users quickly master how to use the Qwen3-VL model for various tasks.
-
Demonstrates implementation methods for multimodal tasks: Through specific examples, guides users on how to complete tasks by combining multimodal data such as images, videos, and text.
-
Optimizes model usage workflows: Provides efficient processing workflows and code examples to help users improve development and deployment efficiency.
-
Supports multiple application scenarios: Covers diverse scenarios from object recognition to document parsing, video understanding, and more, meeting different needs.
-
Provides performance optimization suggestions: Helps users optimize model performance according to specific tasks, improving inference speed and efficiency.
What Qwen3-VL Cookbooks Covers
-
Object Recognition (Omni Recognition): Recognizes a variety of objects, including animals, plants, people, scenic spots, and various commodities.
-
Document Parsing (Powerful Document Parsing Capabilities): Parses text and its layout in documents, supporting Qwen HTML format.
-
Precise Object Grounding Across Formats: Uses relative coordinates to locate targets in images, supporting box and point annotations.
-
General OCR and Key Information Extraction: Supports OCR in 32 languages and can recognize text in low-light, blurry, and skewed scenes.
-
Video Understanding: Supports video OCR and long video understanding, and can perform video content analysis.
-
Mobile Agent: Through visual grounding and reasoning, helps users control mobile phone operations.
-
Computer-Use Agent: Through visual grounding and reasoning, helps users control computer and web operations.
-
3D Grounding: Provides precise 3D bounding boxes for indoor and outdoor objects.
-
Thinking with Images: Uses image zoom and search tools to enhance the model's understanding of image details.
-
MultiModal Coding: Generates HTML, CSS, and JS code based on images and videos.
-
Long Document Understanding: Achieves rigorous semantic understanding of ultra-long documents.
-
Spatial Understanding: Observes, understands, and reasons about spatial information in images and scenes.
Qwen3-VL Cookbooks Project Address
- GitHub Repository:https://github.com/QwenLM/Qwen3-VL/tree/main/cookbooks
Application Scenarios of Qwen3-VL Cookbooks
-
Object Recognition: In intelligent security, quickly identify suspicious individuals or objects in surveillance footage, improving the efficiency of security monitoring.
-
Document Parsing: In the financial industry, automatically extract key clauses and data from contract texts to improve contract review efficiency.
-
Precise Object Localization: In autonomous driving, accurately recognize and localize traffic signs and obstacles on the road to ensure driving safety.
-
Multilingual OCR and Key Information Extraction: In intelligent customer service, quickly read multilingual documents uploaded by users and extract key information to improve service efficiency.
-
Video Understanding: In the education field, automatically generate subtitles for online course videos to facilitate student learning.