
What is Qwen3-ASR-Flash
Qwen3-ASR-Flash is the latest in the Tongyi Qianwen seriesspeech recognitionmodel, based on Qwen3 base model, trained on massive multimodal and ASR data. The model supports 11 languages and multiple accents, delivers high-accuracy, high-robustness speech recognition performance, and supports singing recognition. Users can provide text context in any format to obtain customized ASR results. Qwen3-ASR-Flash performs best in multilingual benchmark tests, can handle complex acoustic environments and difficult text patterns, and provides strong support for speech-to-text services.
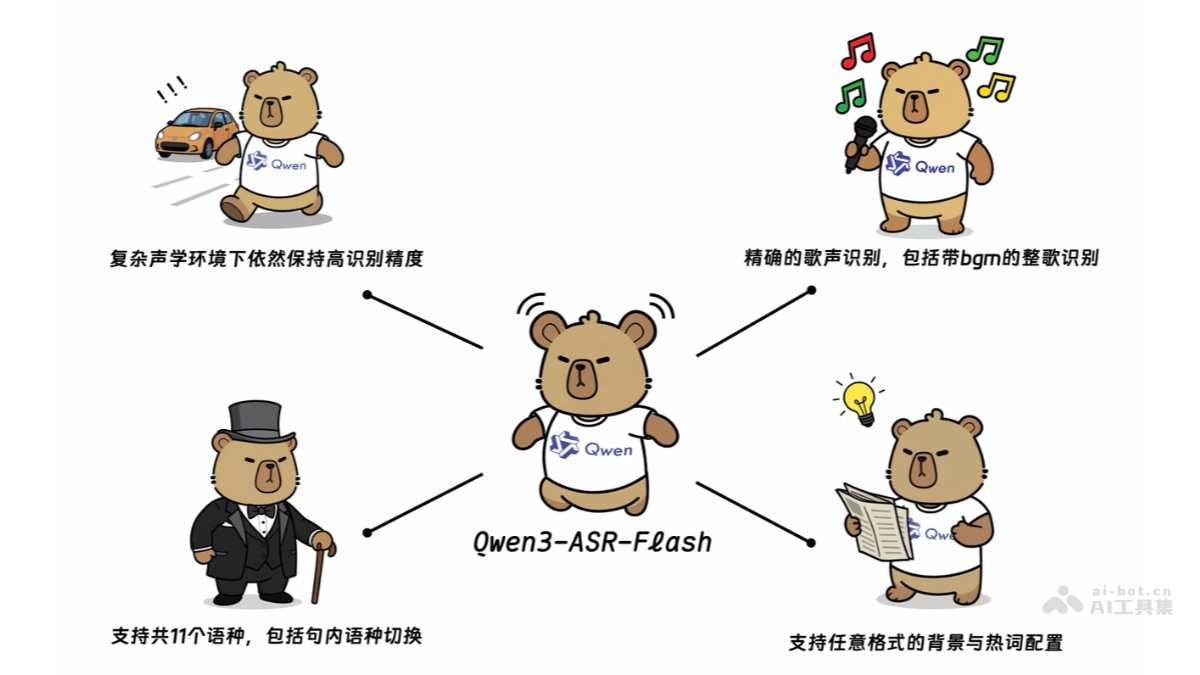
Main Features of Qwen3-ASR-Flash
- High-Accuracy Speech Recognition: Performs excellently in speech recognition across multiple languages and dialects, accurately transcribing Mandarin, Sichuan dialect, Hokkien, Wu, Cantonese, and other Chinese dialects, as well as various English accents such as British and American English, and covering French, German, Russian, and 9 other languages.
- Singing Recognition: Supports singing recognition, including a cappella and full-song recognition with background music, with a measured error rate below 8%.
- Customized Recognition: Users provide background text in any format, such as keyword lists, paragraphs, or complete documents, and the model can intelligently use contextual information to recognize matching named entities and other key terms and output customized recognition results.
- Language Identification and Non-Speech Rejection: Supports accurate identification of the language of speech and automatically filters out non-speech segments, including silence and background noise.
- High Robustness: Maintains high accuracy when facing complex text patterns such as long and difficult sentences, mid-sentence language switching, and repeated words, as well as complex acoustic environments such as in-car noise and various types of noise.
Technical Principles of Qwen3-ASR-Flash
- Based on the Qwen3 Base Model: Qwen3-ASR-Flash is built on the Qwen3 base model. The Qwen3 base model is a powerful multimodal pretrained model with the ability to process multiple types of data, including text and speech.
- Trained on Massive Multimodal Data: The model is trained on massive multimodal data, including multiple types of data such as text and speech, enabling the model to understand and process information across multiple modalities.
- Trained on ASR Data at the Scale of Tens of Millions of Hours: In addition to multimodal data, Qwen3-ASR-Flash is trained on automatic speech recognition (ASR) data at the scale of tens of millions of hours. The data covers multiple languages, dialects, and accents, enabling the model to accurately recognize and transcribe speech.
Project Address of Qwen3-ASR-Flash
- Project Official Website:https://bailian.console.aliyun.com/?tab=model#/model-market/detail/group-qwen3-asr-flash?modelGroup=group-qwen3-asr-flash
- Online Experience Demo:https://huggingface.co/spaces/Qwen/Qwen3-ASR-Demo
Application Scenarios of Qwen3-ASR-Flash
-
Meeting Notes: Qwen3-ASR-Flash can transcribe multilingual meeting content in real time, helping efficiently organize meeting minutes.
-
News Interviews: Accurately transcribes interview speech, improving the timeliness of news reporting.
-
Online Education: Transcribes course audio explanations into text to meet the needs of students in different languages.
-
Intelligent Customer Service: Integrated into customer service systems to transcribe customer inquiries in real time and improve service efficiency.
-
Medical Records: Accurately transcribes doctors' voice records, facilitating medical record organization and data analysis.