
What is Qwen2
Qwen2 is a new-generation large language model open-sourced by the Alibaba Cloud Tongyi Qianwen team. This series covers five model sizes ranging from 0.5B to 72B. On top of Chinese and English, it adds high-quality data in 27 languages, greatly improving the model's natural language understanding, code writing, mathematical problem-solving, and multilingual processing capabilities. Qwen2 supports a context length of up to 128K tokens and optimizes the model's generalization and application potential. This series of models performs excellently on multiple evaluation benchmarks, surpassing Meta's Llama-3-70B, and has now been open-sourced on the Hugging Face and ModelScope platforms.
Qwen2 model information
| Model Name | Parameter Count (B) | Non-Embedding Parameter Count (B) | Whether GQA is used | Whether Tie Embedding is used | Context Length (tokens) |
|---|---|---|---|---|---|
| Qwen2-0.5B | 0.49 | 0.35 | Yes | Yes | 32K |
| Qwen2-1.5B | 1.54 | 1.31 | Yes | Yes | 32K |
| Qwen2-7B | 7.07 | 5.98 | Yes | No | 128K |
| Qwen2-57B-A14B | 57.41 | 56.32 | Yes | No | 64K |
| Qwen2-72B-Instruct | 72.71 | 70.21 | Yes | No | 128K |
- Parameter Count: The total number of parameters in the model, in units of B (billion).
- Non-Embedding Parameter Count: The number of parameters excluding the word embedding (Embedding) part.
- Whether GQA is used: Whether the model adopts GQA (Generalized Query Answering) technology.
- Whether Tie Embedding is used: Whether the model uses technology in which the input and output layers share parameters.
- Context Length: The maximum context length the model can process, in units of tokens.
Qwen2 official website entry
- Official blog introduction:https://qwenlm.github.io/zh/blog/qwen2/
- GitHub address:https://github.com/QwenLM/Qwen2
- Hugging Face address:https://huggingface.co/Qwen
- ModelScope address:https://modelscope.cn/organization/qwen
- Hugging Face online Demo:https://huggingface.co/spaces/Qwen/Qwen2-72B-Instruct
Qwen2 model evaluation
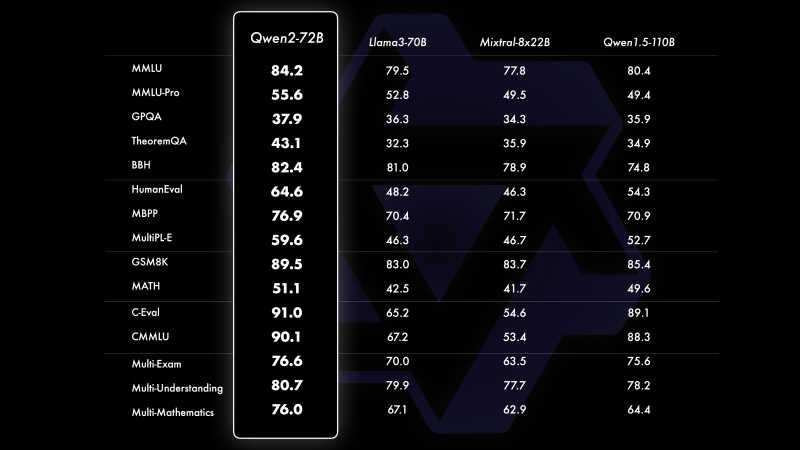
- The Qwen2 series performs excellently on multiple evaluation benchmarks, especially on the Qwen2-72B model, achieving a substantial improvement in results.
- In multiple capabilities such as natural language understanding, knowledge, code, mathematics, and multilingual performance, Qwen2-72B significantly surpasses current leading models, such as Llama-3-70B and the 110B model of Qwen1.5.
- In 16 benchmark tests, Qwen2-72B-Instruct demonstrated a balance between foundational capabilities and alignment with human values, surpassing the 72B model of Qwen1.5 and matching Llama-3-70B-Instruct.
Qwen2 model highlights
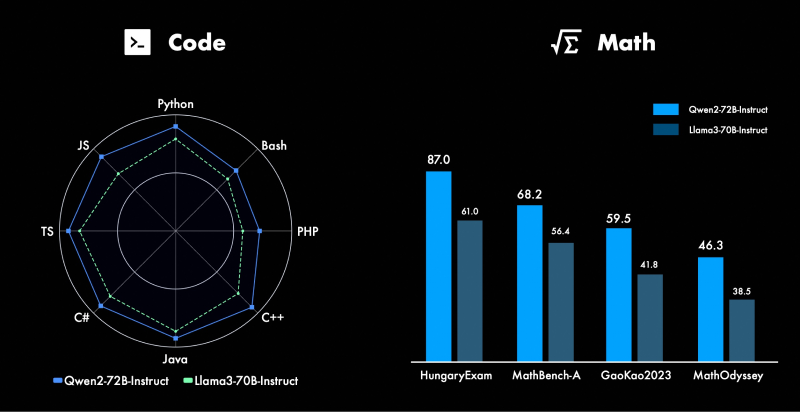
- Code & Mathematics: Qwen2's capabilities in code and mathematics have been significantly improved, successfully incorporating the experience of CodeQwen1.5 and achieving improved results across multiple programming languages. Mathematical capability is supported by large-scale high-quality data, achieving a leap in problem-solving ability.
- Long text processing: The Instruct models of the Qwen2 series are trained on a 32k context length and extended to longer contexts through technologies such as YARN. Qwen2-72B-Instruct can perfectly handle information extraction tasks with a 128k context length.
- Safety: In multilingual unsafe query categories, Qwen2-72B-Instruct is comparable to GPT-4 in safety and significantly better than the Mistral-8x22B model, reducing the proportion of harmful responses generated.
- Multilingual capability: Qwen2 performs excellently in multilingual evaluations, enhancing processing capabilities for 27 languages and optimizing language switching issues, reducing the probability of language switching occurring in the model.