
What is Qwen2.5-Omni-3B
Qwen2.5-Omni-3B is a lightweight multimodal AI model launched by the Alibaba Qwen team. It is a simplified version of Qwen2.5-Omni-7B, designed specifically for consumer-grade hardware, and supports multiple input functions such as text, audio, images, and video. With the parameter count reduced from 7B to 3B, its multimodal performance still retains more than 90% of the 7B model, and it performs outstandingly in real-time text generation and natural speech output. When processing long-context inputs of 25,000 tokens, memory usage is reduced by 53%, from 60.2GB in the 7B model to 28.2GB, allowing it to run on devices with a 24GB GPU.
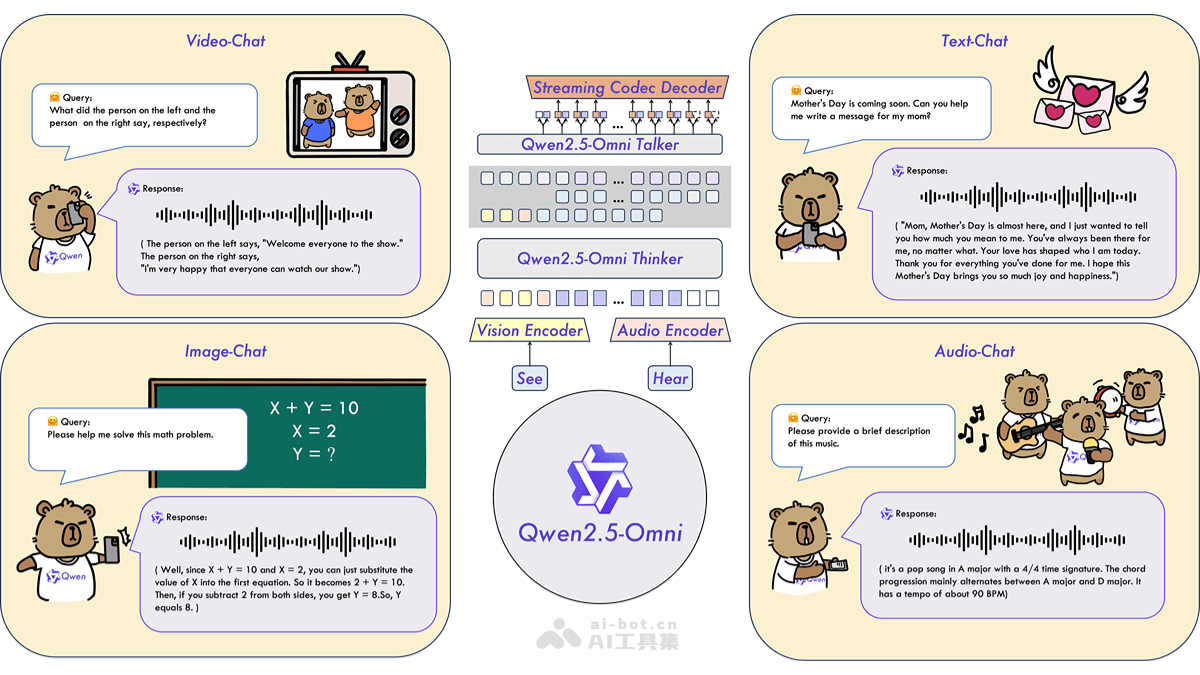
Main features of Qwen2.5-Omni-3B
- Multimodal input and real-time response: Supports multiple input functions such as text, audio, images, and video, and can generate text and natural speech responses in real time.
- Voice customization: Users can choose between two built-in voices (Chelsie female and Ethan male), adapting to different applications or audiences.
- Memory optimization: When processing long-context inputs of 25,000 tokens, memory usage drops from 60.2GB in the 7B model to 28.2GB, a reduction of 53%, allowing it to run on devices with a 24GB GPU.
- Architectural innovation: Adopts the Thinker-Talker design and the customized positional embedding method TMRoPE, ensuring synchronized understanding of video and audio inputs.
- Optimization support: Supports FlashAttention 2 and BF16 precision optimization, further improving speed and reducing memory consumption.
- Performance: In multimodal benchmark tests, performance is close to the 7B model, for example, scoring 68.8 on the VideoBench video understanding test and 92.1 on the Seed-tts-eval speech generation test.
Technical principles of Qwen2.5-Omni-3B
- Thinker-Talker architecture: Qwen2.5-Omni-3B adopts the Thinker-Talker architecture, dividing the model into two parts: the "Thinker" and the "Talker." The Thinker is responsible for processing and understanding multimodal inputs (such as text, audio, and video), generating high-level semantic representations and text output; the Talker generates natural speech based on the Thinker's output, ensuring synchronized text generation and speech output.
- Time-aligned Multimodal Position Embedding (TMRoPE): To synchronize the timestamps of video input with audio, Qwen2.5-Omni-3B proposes TMRoPE (Time-aligned Multimodal RoPE). By interleaving the time IDs of audio and video frames, the three-dimensional positional information of multimodal inputs (time, height, width) is encoded into the model, achieving synchronized understanding of video and audio inputs.
- Streaming processing and real-time response: The model adopts a chunked processing method, decomposing long sequences of multimodal data into small chunks for processing, reducing processing latency. A sliding window mechanism is introduced to limit the context range of the current token, further optimizing the efficiency of streaming generation. This enables the model to generate text and speech responses in real time in a streaming manner.
- Precision optimization: The model supports FlashAttention 2 and BF16 precision optimization, further improving processing speed and reducing memory consumption.
Project address of Qwen2.5-Omni-3B
- HuggingFace model library:https://huggingface.co/Qwen/Qwen2.5-Omni-3B
Application scenarios of Qwen2.5-Omni-3B
- Video understanding and analysis: Qwen2.5-Omni-3B can process and analyze video content in real time. It can be applied to fields such as video content analysis, surveillance video interpretation, and intelligent video editing, helping users quickly extract key information from videos.
- Speech Generation and Interaction: The model supports voice customization, allowing users to choose between two built-in voices (Chelsie female and Ethan male). It can be used in scenarios such as intelligent voice assistants, voice broadcasting systems, and audiobook generation, providing a natural and fluent voice interaction experience.
- Intelligent Customer Service and Automated Report Generation: Qwen2.5-Omni-3B can process text input and generate text responses in real time, making it suitable for intelligent customer service systems, where it can quickly answer user questions and provide solutions.
- Education and Learning Tools: In the field of education, Qwen2.5-Omni-3B can assist teaching, for example, by helping students answer questions and providing learning guidance through voice and text interaction. It can be used in mathematics teaching to parse geometry problems and provide step-by-step reasoning guidance.
- Creative Content Generation: Qwen2.5-Omni-3B can analyze image content and generate creative content that combines images and text.