
What is QIHOO-T2X
Qihoo-T2X is an efficient multimodal generation model based on the Proxy Tokenized Diffusion Transformer (PT-DiT), launched by 360 AI Research Institute and Sun Yat-sen University. Qihoo-T2X introduces a sparse proxy token attention mechanism, significantly reducing the redundancy of traditional diffusion Transformers in global self-attention computation, and combines window attention and shifted window attention to enhance detail modeling capabilities. Qihoo-T2X supports multiple tasks, includingtext-to-image(T2I)、text-to-video(T2V) and text-to-multi-view (T2MV) generation.
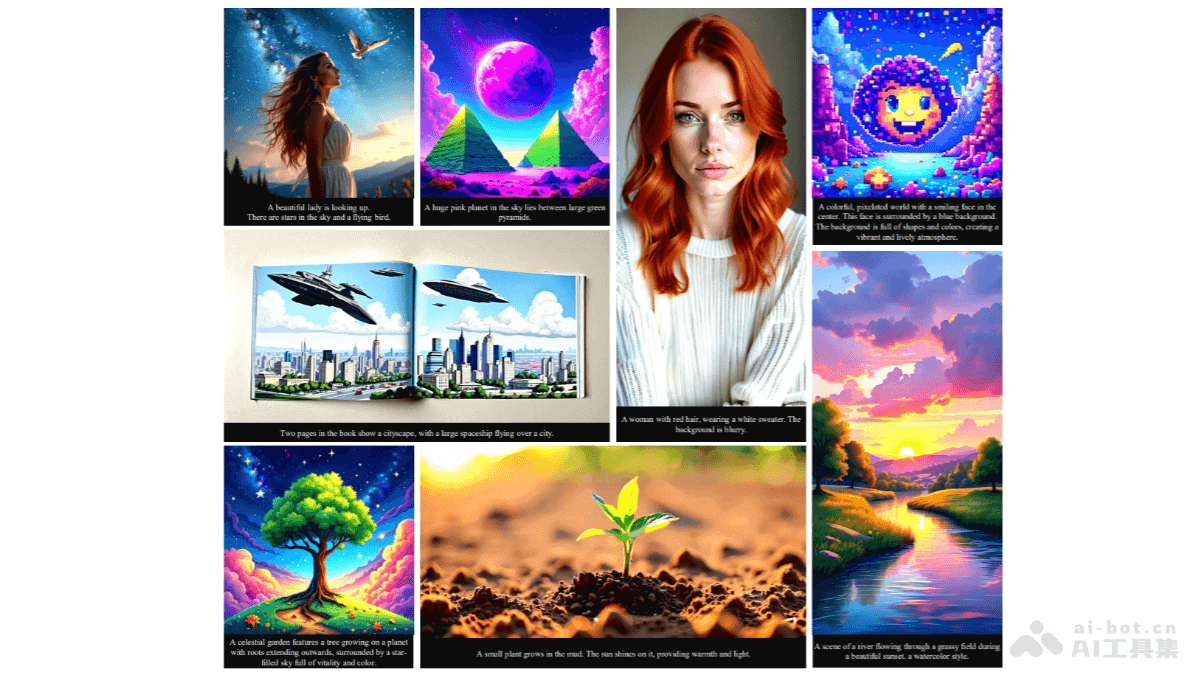
Main features of Qihoo-T2X
- Text-to-image: Generates high-quality, high-resolution images based on input text descriptions, producing image content highly consistent with the text descriptions, suitable for fields such as creative design and art generation.
- Text-to-video: Generates coherent video content based on text descriptions, supports the generation of dynamic scenes and video sequences, suitable for scenarios such as video creation and animation production.
- Text-to-multi-view: Generates multi-view images of the same object or scene based on text descriptions, suitable for multi-view display of 3D objects, and supports virtual reality (VR) and augmented reality (AR) applications.
- Efficient generation: Based on an optimized proxy tokenized attention mechanism, it significantly reduces computational complexity, supports efficient generation of high-resolution images and long videos, and lowers training and inference costs.
Technical principles of Qihoo-T2X
- Proxy tokenized attention: Traditional diffusion Transformers use a global self-attention mechanism, which has high computational complexity and redundancy. PT-DiT (the core architecture of Qihoo-T2X) computes average tokens within each spatiotemporal window as proxy tokens, performs self-attention computation on the proxy tokens, and greatly reduces the amount of computation. The global semantic information among proxy tokens is injected into all latent tokens based on cross-attention, ensuring the effective propagation of global information.
- Window attention and shifted window attention: To enhance local detail modeling capability, PT-DiT introduces a window attention mechanism, performing self-attention computation on tokens within local windows. The shifted window attention mechanism is used to avoid the "grid effect" caused by window partitioning, further improving generation quality.
- Efficient computation of sparse proxy tokens: Based on the sparse proxy token mechanism, PT-DiT significantly reduces computational complexity when processing high-resolution images and long videos, while maintaining the quality of generated content.
- Multi-task adaptability: The architecture design of PT-DiT can seamlessly adapt to multiple tasks such as image generation, video generation, and multi-view generation, without the need for major adjustments to the model structure.
Qihoo-T2X project address
- Project official website:https://360cvgroup.github.io/Qihoo-T2X/
- GitHub repository:https://github.com/360CVGroup/Qihoo-T2X
- arXiv technical paper:https://arxiv.org/pdf/2409.04005
Application scenarios of Qihoo-T2X
- Creative design and artistic creation: Quickly generates high-quality art images based on text descriptions, supports multiple styles, accelerates the design process, and provides inspiration for artists.
- Video content generation: Generates coherent animated videos, suitable for advertising, promotion, and animation production, reducing the cost and time of video creation.
- Education and training: Generate instructional images and videos to help students understand complex concepts, supporting virtual laboratories and dynamic teaching resources.
- Entertainment and Game Development: Generate virtual scenes, characters, and dynamic content for use in game development, virtual reality (VR), and augmented reality (AR) applications to enhance immersion.
- Advertising and Marketing: Quickly generate personalized advertising images and videos, improve marketing effectiveness, and meet brand visual content needs.