
What is PP-OCRv5
PP-OCRv5 is an efficient and accurate text recognition model launched by Baidu. The model is based on a two-stage processing pipeline and is specifically designed to quickly and accurately detect and recognize text in images. The model has only 0.07 billion parameters, is small in size and highly efficient, and performs excellently on CPUs and edge devices, processing more than 370 characters per second. The model supports 5 text types, including Simplified Chinese, Traditional Chinese, English, Japanese, and Pinyin, and can recognize more than 40 languages. In various OCR benchmarks, PP-OCRv5 outperforms general-purpose vision-language models, especially in handwritten and printed text recognition.
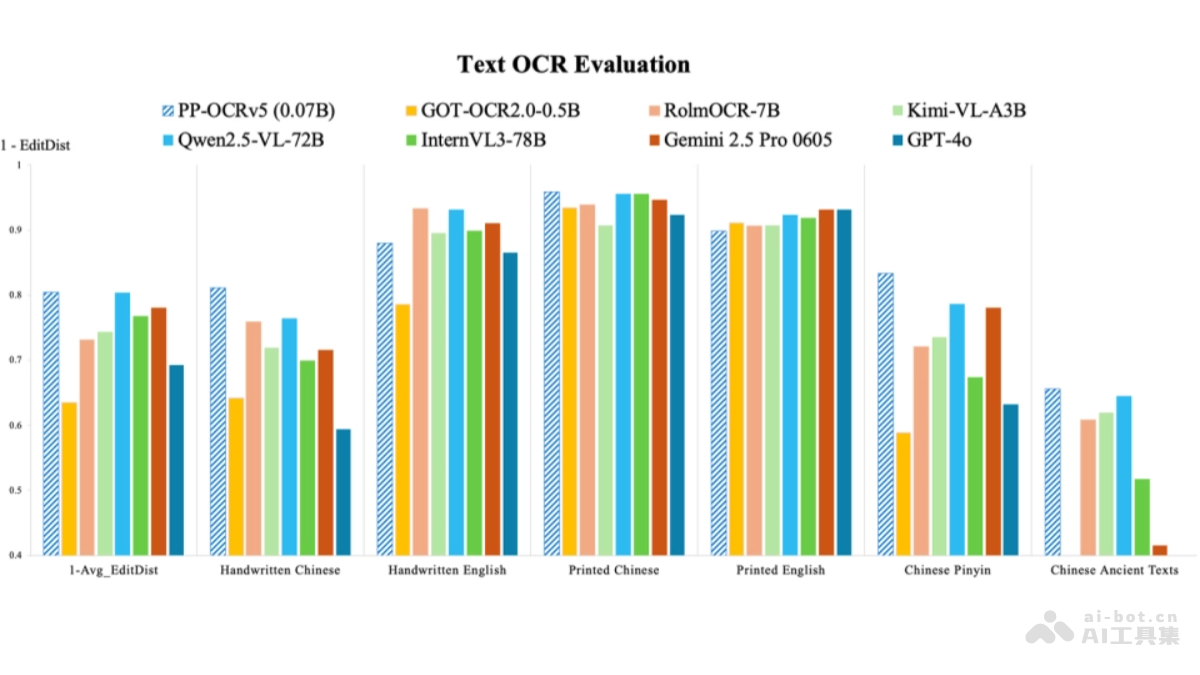
Main features of PP-OCRv5
-
Efficient text detection and recognition: PP-OCRv5 can quickly and accurately detect text regions in images and accurately recognize text content, suitable for various scenarios such as document scanning and text extraction from images.
-
Multilingual support: Supports 5 text types, including Simplified Chinese, Traditional Chinese, English, Japanese, and Pinyin, and can recognize more than 40 languages, meeting OCR needs in different language environments.
-
Accurate text localization: Provides precise text line bounding box coordinates, which are crucial for structured data extraction and content analysis, helping users better understand and process text information.
-
High efficiency and low resource consumption: The model has a small number of parameters (0.07 billion) and runs efficiently on CPUs and edge devices, making it suitable for use on resource-constrained hardware such as mobile devices or embedded systems.
-
Adapts to multiple text styles: It can effectively recognize both printed and handwritten text, and can perform OCR tasks well on both clear documents and lower-quality scans.
Technical principles of PP-OCRv5
-
Two-stage processing pipeline: PP-OCRv5 uses a two-stage processing pipeline: first, text detection is performed to determine the positions of text in the image, and then text recognition is performed to convert the characters in the detected text regions into an editable text format.
-
Modular design: The model consists of four core components: image preprocessing, text detection, text line orientation classification, and text recognition. The modular design allows each stage to focus on a specific task, improving overall efficiency and accuracy.
-
Deep learning technology: Built on deep learning frameworks such as PaddlePaddle and trained on large amounts of annotated data, the model can learn different text features and image patterns, enabling effective recognition of text in various complex scenarios.
-
Optimized network architecture: While maintaining high accuracy, the network architecture is optimized to reduce the model's parameter count and computational load, allowing it to run more efficiently on different hardware platforms while maintaining high performance.
PP-OCRv5 project address
- Project official website:https://huggingface.co/blog/baidu/ppocrv5
- HuggingFace model library:https://huggingface.co/collections/PaddlePaddle/pp-ocrv5-684a5356aef5b4b1d7b85e4b
Application scenarios of PP-OCRv5
-
Document processing: Quickly converts paper documents into electronic text, suitable for office automation and archive management.
-
Education: The model can recognize handwritten text in student assignments and exam papers, assisting teachers in grading.
-
Financial industry: Efficiently recognizes text information in various bills and contracts, improving the efficiency of data entry and review.
-
Traffic management: Accurately recognizes license plates and traffic sign text, supporting traffic monitoring and autonomous driving systems.
-
Mobile Office: Quickly extracts text from documents and images on mobile devices, supporting office work anytime, anywhere.