
What is PlayDiffusion
PlayDiffusion is a new audio editing model launched by Play AI, based on diffusion model technology, specifically designed for fine-grained audio editing and restoration. The model encodes audio into discrete token sequences, masks the parts that need modification, and uses a diffusion model to denoise the masked regions under the condition of updated text, achieving high-quality audio editing. The model seamlessly preserves context, ensuring speech coherence and naturalness, while also supporting efficient text-to-speech synthesis. PlayDiffusion's non-autoregressive nature outperforms traditional autoregressive models in generation speed and quality, bringing new breakthroughs to the fields of audio editing and speech synthesis.
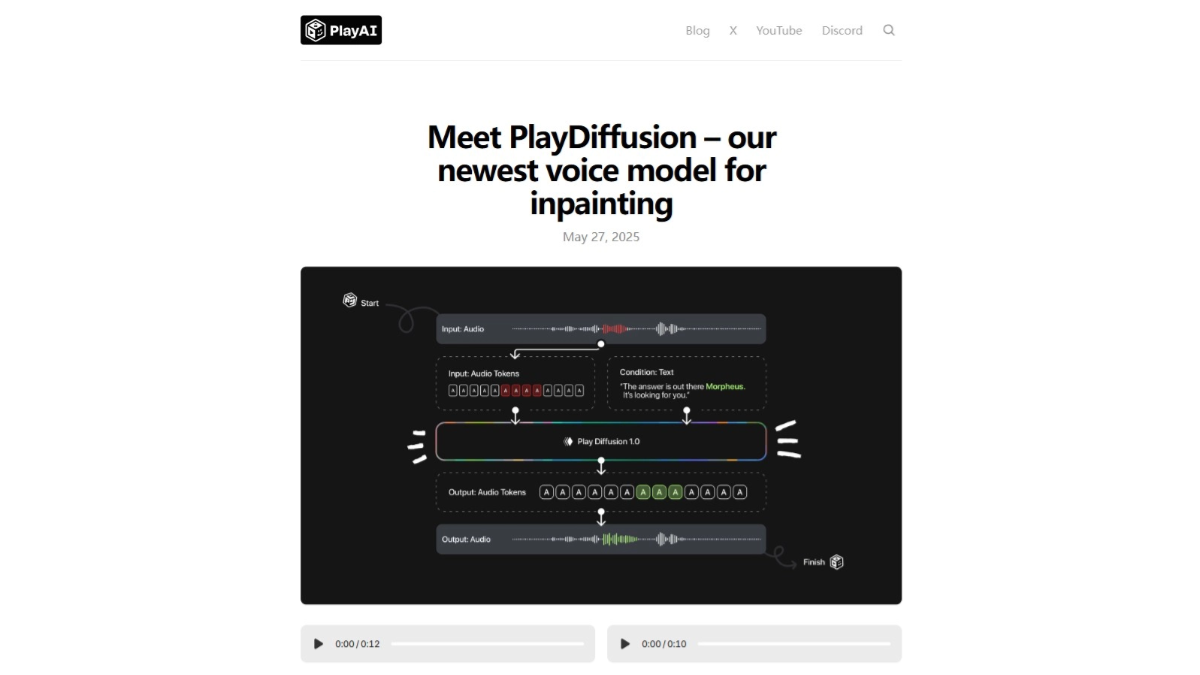
Main Features of PlayDiffusion
- Local Audio Editing: Supports local replacement, modification, or deletion of audio without regenerating the entire audio segment, maintaining natural and seamless speech.
- Efficient TTS: When masking the entire audio, it functions as an efficient TTS model, with inference speed 50 times faster than traditional TTS and better speech naturalness and consistency.
- Maintains Speech Coherence: Preserves context during editing, ensuring speech coherence and consistent speaker timbre.
- Dynamic Speech Modification: Automatically adjusts speech pronunciation, tone, and rhythm based on new text, suitable for scenarios such as real-time interaction.
- Seamless Integration and Ease of Use: Supports Hugging Face integration and local deployment, facilitating quick experience and use.
Technical Principles of PlayDiffusion
- Audio Encoding: Encodes the input audio sequence into a discrete token sequence, where each token represents a unit of audio. Applicable to real speech and audio generated by text-to-speech models.
- Masking: When a part of the audio needs to be modified, that part is marked as a mask for subsequent processing.
- Diffusion Model Denoising: Denoises the masked region based on the diffusion model with updated text. The diffusion model generates high-quality audio token sequences by gradually removing noise. Using a non-autoregressive method, all tokens are generated simultaneously and refined based on a fixed number of denoising steps.
- Decoding to Audio Waveform: Converts the generated token sequence back to speech waveform using the BigVGAN decoder model, ensuring the final output speech is natural and coherent.
PlayDiffusion Project Address
- Project Official Website:https://blog.play.ai/blog/play-diffusion
- GitHub Repository:https://github.com/playht/PlayDiffusion
- Online Experience Demo:https://huggingface.co/spaces/PlayHT/PlayDiffusion
Application Scenarios of PlayDiffusion
- Dubbing Error Correction: Quickly replace incorrect pronunciations, maintaining natural and smooth dubbing.
- Synthetic Dialogue Word Replacement: Easily modify dialogue content, ensuring language accuracy and naturalness.
- Podcast Editing: Modify or delete segments to improve content quality.
- Real-Time Voice Interaction: Dynamically adjust speech content to achieve natural interaction.
- Speech Synthesis: Efficiently generate high-quality speech, suitable for scenarios such as broadcasting.