
What is Piece it Together
Piece it Together (PiT) is an innovative framework launched by Bria AI and other institutionsimage generationframework, specifically designed to generate complete concept images from partial visual components. Based on domain-specific prior knowledge, it seamlessly integrates fragmented visual elements provided by users into a coherent whole, intelligently supplements missing parts, and generates complete and creative concept images. Piece it Together is based on the IP+ space of IP-Adapter+, training a lightweight flow matching model IP-Prior to achieve high-quality reconstruction and semantic manipulation. Based on LoRA fine-tuning strategy, Piece it Together can significantly improve text compliance, better adapt to different scenarios, and provide strong support for creative design and concept exploration.
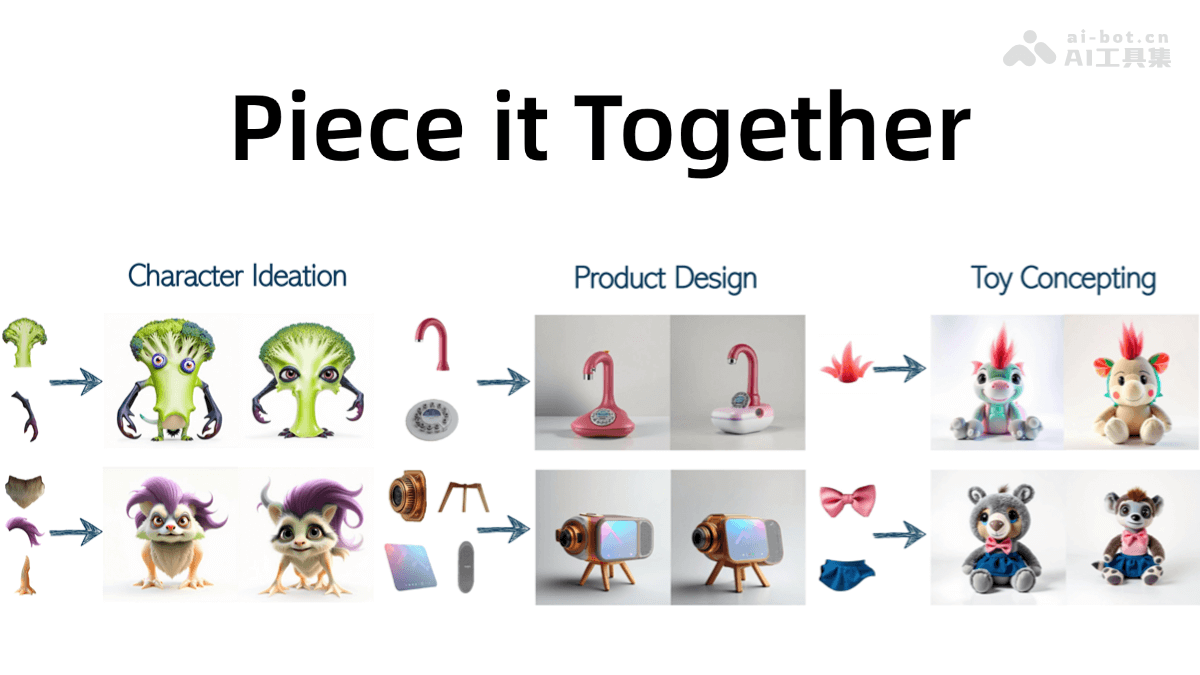
Main Features of Piece it Together
- Integration of Fragmented Visual Elements: Seamlessly integrates partial visual components provided by users (such as a unique wing, a specific hairstyle, etc.) into a coherent overall composition to generate complete concept images.
- Supplementing Missing Parts: While integrating existing visual elements, automatically supplements and generates the missing parts.
- Diverse Concept Generation: Generates multiple different concept variants for the same set of input elements.
- Semantic Manipulation and Editing: Supports semantic manipulation in the IP+ space, allowing users to further edit and adjust the generated concepts.
- Recovery of Text Compliance: Supports restoring the ability to follow text prompts, placing the generated concepts in specific scenes or backgrounds, enhancing the diversity and applicability of the generated images.
Technical Principles of Piece it Together
- IP+ Space: Based on the internal representation space of IP-Adapter+ (IP+ space), compared to the traditional CLIP space, the IP+ space performs better in preserving complex concepts and details, supports semantic manipulation, and provides a foundation for high-quality image reconstruction and concept editing.
- IP-Prior Model: Trains a lightweight flow matching model IP-Prior, which, based on domain-specific prior knowledge, generates complete concept images from input partial visual components. By learning the distribution of the target domain, it dynamically adapts to user input and completes the generation of missing parts.
- Data Generation and Training: Uses pre-trained text-to-image models such as FLUX-Schnell to generate training data, adding random adjectives and categories to enhance data diversity. Uses segmentation methods to extract semantic parts of target images, forming input pairs, and trains the IP-Prior model to solve the target task.
- LoRA Fine-tuning Strategy: Based on the LoRA fine-tuning strategy, it improves the shortcomings of IP-Adapter+ in text compliance. By training LoRA adapters with a small number of samples, it restores text control capability, allowing the generated concepts to better follow text prompts while maintaining visual fidelity.
Project Address of Piece it Together
- Project Official Website:https://eladrich.github.io/PiT/
- GitHub Repository:https://github.com/eladrich/PiT
- arXiv Technical Paper:https://arxiv.org/pdf/2503.10365
Application Scenarios of Piece it Together
- Character Design: Quickly generate complete character designs such as fantasy creatures and sci-fi characters, exploring different creative directions.
- Product Design: Provide product components, generate complete concept images, validate design ideas, and explore diverse designs.
- Toy Design: Input toy elements, spark creativity, and generate multiple toy concepts for market testing.
- Art Creation: Provide artistic elements, generate complete works, explore different styles, and inspire creative inspiration.
- Education and Training: Used in design and art education to quickly generate creative concepts, cultivate innovative thinking, and improve design skills.