
What is Pangea
Pangea is a multilingual multimodal large language model (LLM) launched by a team at Carnegie Mellon University, capable of improving coverage of global language and cultural diversity. The model includes a diverse dataset of 6 million instructions, supports 39 languages, and contains high-quality English instructions, machine-translated instructions, and culture-related tasks. Pangea's performance is evaluated based on the PangeaABench evaluation suite, which includes 14 datasets and covers 47 languages. Pangea outperforms existing open-source models (such as Llava-1.5-7B and Llava-Next-7B) in multilingual and cultural contexts. Research finds that the proportion of English data, language popularity, and the number of multimodal training samples have a significant impact on performance.
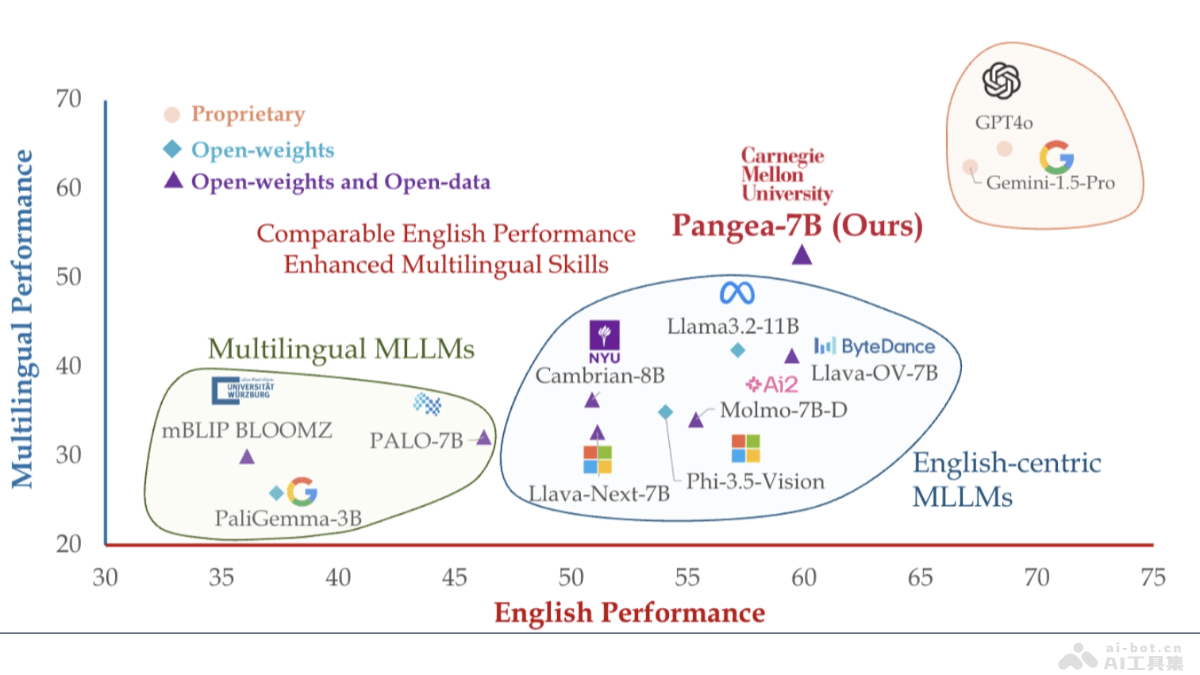
Pangea's Main Features
- Multilingual Support: Can understand and generate text in 39 different languages, making it very useful in multilingual communication and processing.
- Multimodal Understanding: In addition to text, can process and understand images, performing excellently in tasks such as image captioning and visual question answering.
- Cross-Cultural Coverage: Includes culture-related multimodal tasks in training, helping the model better understand and adapt to different cultural backgrounds.
- High-Quality Instruction Following: Pangea uses high-quality English instructions and carefully machine-translated instructions in training, ensuring the model's accuracy and consistency across different languages.
Pangea's Technical Principles
- Dataset Construction: Based on the Pangea dataset, a multilingual dataset containing 6 million instructions and covering 39 languages.
- Machine Translation: To address the scarcity of multilingual data, machine translation technology is used to translate high-quality English instructions into other languages.
- Culture-Related Tasks: Includes culture-related multimodal tasks in training to improve the model's understanding of and adaptability to cultural differences.
- Evaluation Suite: PangeaABench is an evaluation suite containing 14 datasets and covering 47 languages, used to comprehensively evaluate the model's performance in multilingual and multimodal tasks.
- Model Architecture: Based on the LLaVA-Next architecture, using Qwen2-7B-Instruct as the backbone of the language model, providing the model with strong language understanding and generation capabilities.
Pangea's Project Address
- Project Official Website:neulab.github.io/Pangea
- GitHub Repository:https://github.com/neulab/Pangea
- HuggingFace Model Library:https://huggingface.co/collections/neulab/pangea-6713c3b0d78a453906eb2ed8
- arXiv Technical Paper:https://arxiv.org/pdf/2410.16153
- Online Experience Demo:https://huggingface.co/spaces/neulab/Pangea
Pangea's Application Scenarios
- Multilingual Customer Service: In globalized companies, provide multilingual customer support and services to help solve the problems of customers in different languages.
- Education and Learning: As an educational tool, help learners obtain multilingual learning materials, or provide assistance in language teaching.
- Cross-Cultural Communication: In international organizations or non-governmental organizations, promote communication and understanding among people from different cultural backgrounds.
- Social Media and Content Creation: Pangea helps content creators generate multilingual content, or interact with users in different languages on social media.
- Travel and Navigation: In the tourism industry, provide multilingual travel information and navigation services to help tourists overcome language barriers.