
What is OneDiffusion
OneDiffusion is a versatile large-scale diffusion model launched by AI2, capable of seamlessly supporting bidirectional image synthesis and understanding, covering a variety of tasks such as text-to-image generation, conditional image generation, and image understanding. Based on training by modeling all conditions and target images as sequential "views," it enables the ability to use any frame as a conditional image at inference time. With its unified training framework, scalability, and support for multiple tasks, OneDiffusion provides a general-purpose visual model solution.
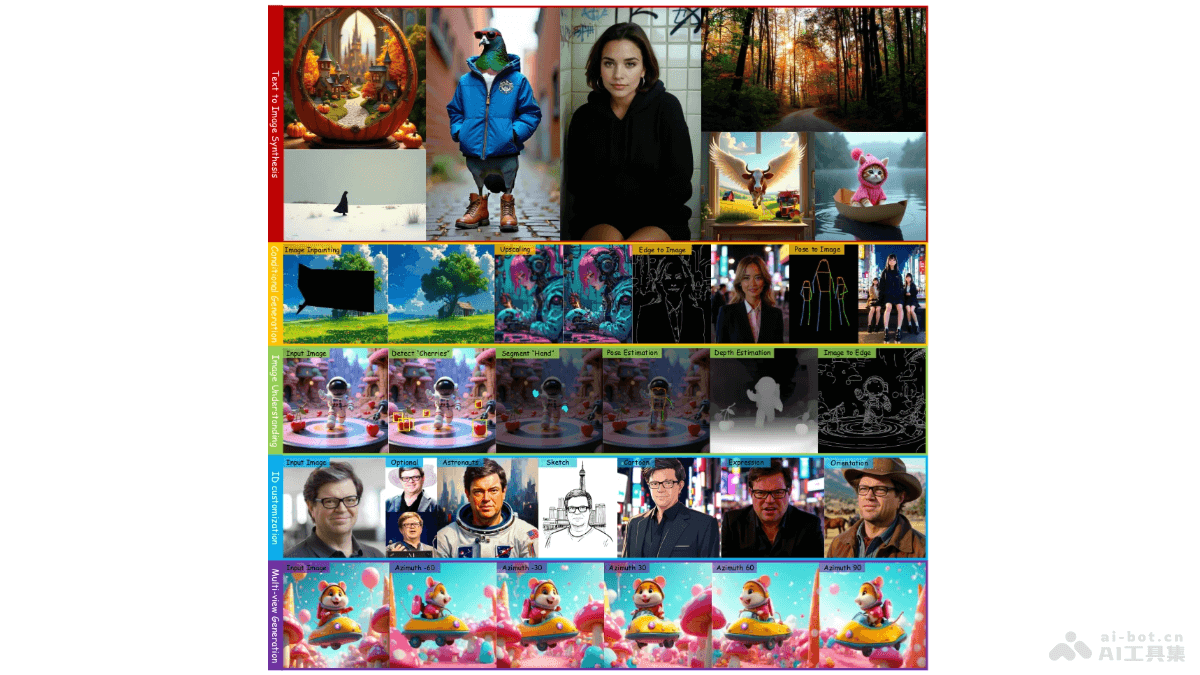
Main features of OneDiffusion
- Text-to-image synthesis: Generate high-quality, realistic images from text prompts.
- Conditional image generation: Generate new images based on input images (such as depth maps and pose maps).
- Image understanding: Perform tasks such as depth estimation, pose estimation, and image segmentation.
- Multi-view generation: Generate consistent views from multiple viewpoints from a single image.
- Instant personalization: Use sequence image input for personalized generation.
- ID customization: Perform image customization and generation based on personal identity information.
- Zero-shot high-resolution generation: Generate high-resolution images even if high resolution was not encountered during training.
Technical principles of OneDiffusion
- Flow matching framework: Use the flow matching framework to train a continuous-time generative model, learning a time-dependent vector field to transform probability distributions.
- Sequence modeling: Model all conditions and target images as a series of "views," processed as sequences during training, with each view having a different noise level.
- Flexible framework: At inference time, any view can be used as conditional input or set to noise to generate an output image.
- Unified training framework: Based on a unified training framework, it removes the need for specific architectures, supports scalable multi-task training, and can adapt to arbitrary resolutions.
- Noise scheduling: During training, independently sample the time variable and Gaussian noise for each view to achieve views with different noise levels.
OneDiffusion project address
- GitHub repository:https://github.com/lehduong/OneDiffusion/
- arXiv technical paper:https://arxiv.org/pdf/2411.16318
Application scenarios of OneDiffusion
- Artistic creation and design: With text-to-image synthesis, artists and designers can generate visual content from creative descriptions, accelerating the creative process.
- Advertising and marketing: Based on conditional image generation, customize images according to specific brand styles or market trends for advertising and marketing materials.
- Game development: In game design, rapidly prototype and generate diverse views of game environments, characters, and items.
- Virtual reality (VR) and augmented reality (AR): The multi-view generation capability creates 360-degree panoramic images, enhancing immersive experiences in VR and AR applications.
- Film and entertainment: In film production, generate preliminary sketches of special effects scenes, or use them for quickly previewing scene layouts.