
What is OneCAT
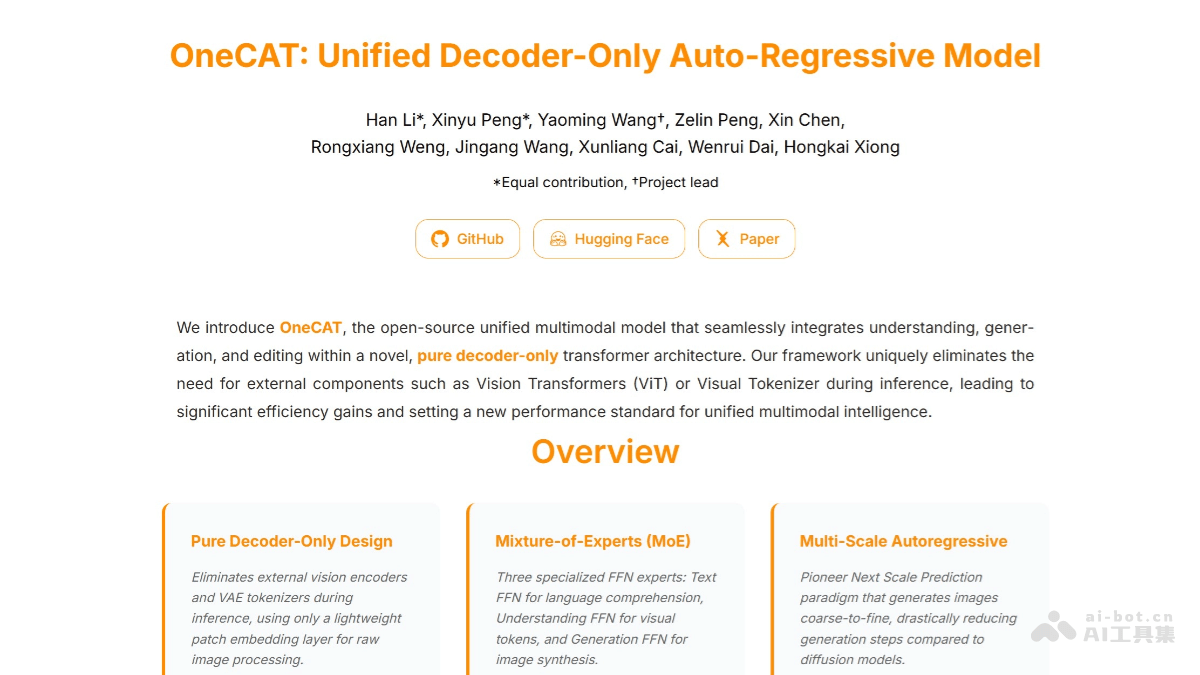
OneCAT is a new unified multimodal model launched by Meituan. It adopts a pure decoder architecture and can seamlessly integrate multimodal understanding, text-to-image generation, and image editing capabilities. The model abandons the design of traditional multimodal models that rely on external visual encoders and tokenizers. Through a modality-specific mixture-of-experts (MoE) structure and a multi-scale autoregressive mechanism, it achieves efficient multimodal processing. It performs excellently when processing high-resolution image inputs and outputs. Through an innovative scale-aware adapter and multimodal versatile attention mechanism, it further enhances visual generation capabilities and cross-modal alignment capabilities.
Main Features of OneCAT
-
Multimodal Understanding: It can efficiently handle multimodal understanding tasks involving images and text, without the need for external visual encoders or tokenizers, and directly achieves deep understanding of image-text content within a pure decoder architecture.
-
Text-to-Image Generation: It generates high-quality images based on text descriptions. Through the multi-scale autoregressive mechanism, it gradually predicts visual tokens from low resolution to high resolution. The generation process is efficient and the generation results are excellent.
-
Image Editing: It supports instruction-based image editing, conditioning the visual generation process on reference images and editing instructions. It can achieve powerful conditional generation capabilities without additional architectural modifications, and can perform precise local and global adjustments to images.
Technical Principles of OneCAT
-
Pure Decoder Architecture: OneCAT adopts a pure decoder autoregressive Transformer model and does not require external visual components such as a vision transformer (ViT) or visual tokenizer. This significantly simplifies the model structure and reduces computational overhead, with especially obvious efficiency advantages when processing high-resolution inputs.
-
Modality-Specific Mixture-of-Experts (MoE) Structure: The model contains three dedicated feed-forward network (FFN) experts, which respectively process text tokens, continuous visual tokens, and discrete visual tokens, for language understanding, multimodal understanding, and image synthesis. All query, key, value (QKV) and attention layers are shared across different modalities and tasks, improving parameter efficiency and enhancing cross-modal alignment capabilities.
-
Multi-Scale Visual Autoregressive Mechanism: Introduced into large language models (LLMs), it generates images in a coarse-to-fine, hierarchical manner, gradually predicting visual tokens from the lowest resolution to the highest resolution, greatly reducing decoding steps while maintaining state-of-the-art performance.
-
Multimodal Versatile Attention Mechanism: Based on PyTorch FlexAttention, it enables the model to flexibly adapt to multiple modalities and tasks. Text tokens use causal attention, continuous visual tokens are processed through full attention, and multi-scale discrete visual tokens are processed through block-wise causal attention.
OneCAT Project Address
- Project Official Website:https://onecat-ai.github.io/
- Github Repository:https://github.com/onecat-ai/onecat
- HuggingFace Model Library:https://huggingface.co/onecat-ai/OneCAT-3B
- arXiv Technical Paper:https://arxiv.org/pdf/2509.03498
Application Scenarios of OneCAT
-
Intelligent Customer Service and Content Moderation: OneCAT's multimodal understanding capability can efficiently process image and text content. It can be used in intelligent customer service systems to understand image-text information uploaded by users and provide accurate replies. It can also be used in the field of content moderation to automatically identify and filter violating image-text content.
-
Creative Design and Digital Content Creation: Its text-to-image generation capability can generate high-quality images based on text descriptions, providing creative inspiration for designers and creators and quickly generating image content that meets their needs. It can be used for preliminary concept design in fields such as advertising design, film and television special effects production, and game development.
-
Advertising Design and Marketing: In advertising design, OneCAT can quickly generate corresponding image assets based on advertising copy, improving design efficiency. It can be used to generate personalized advertising content and generate advertising images that match the preferences of different target audiences.
-
Film and Television Post-Production: OneCAT's image editing capabilities can be used for tasks such as image restoration, style transfer, and special effects addition in film and television post-production, helping film and television production personnel quickly achieve creative effects and improve production efficiency.
-
Education and Learning: In the field of education, OneCAT can generate images related to teaching content to help students better understand and remember knowledge. For example, it can generate corresponding schematic diagrams based on scientific concepts, or generate related scene images based on descriptions of historical events.