
What Is One Shot, One Talk
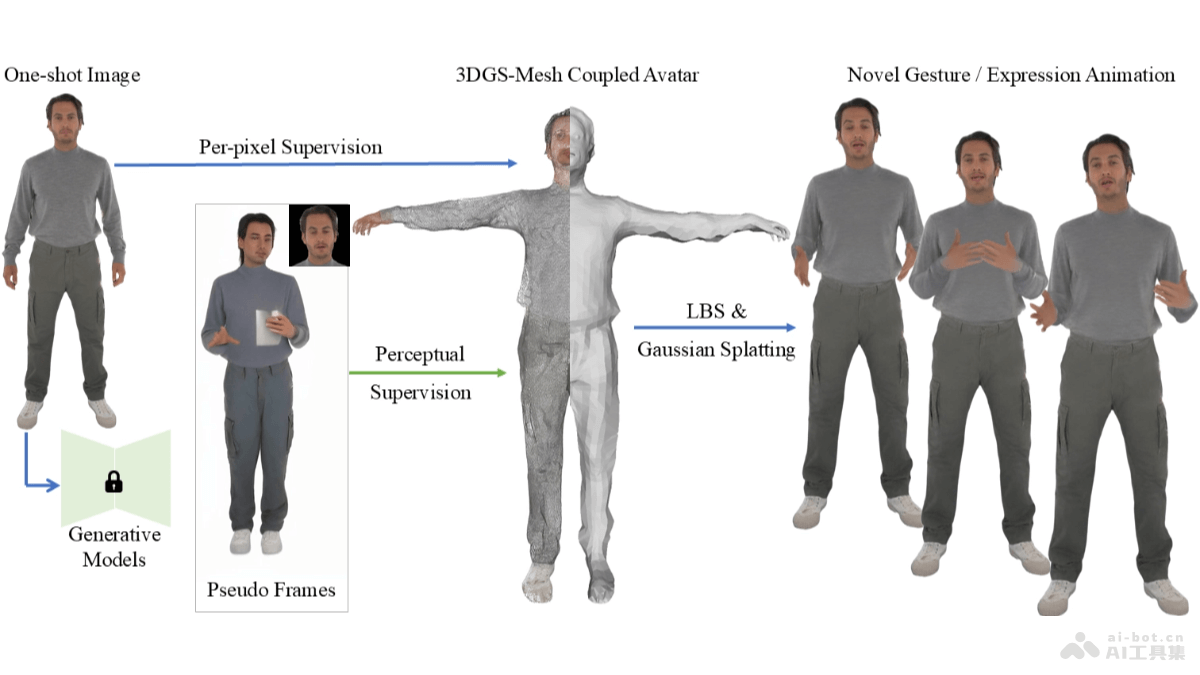
One Shot, One Talk is an advanced image generation technology that can generate a full-body dynamic talking avatar with personalized details from a single image, supporting realistic animation effects, including natural facial expression changes and vivid body movements. One Shot, One Talk was launched by researchers from the University of Science and Technology of China and the Hong Kong Polytechnic University. It combines a pose-guided image-to-video diffusion model and a 3DGS-mesh hybrid avatar representation to achieve generalization to new poses and expressions, creating a realistic, precisely movable, and expressive full-body talking avatar from a single image.
Main Features of One Shot, One Talk
- Single-image reconstruction: Reconstruct a full-body dynamic talking avatar from a single image.
- Realistic animation: Supports realistic animation effects, including body movements and facial expressions.
- Personalized details: Captures and reproduces a person's personalized features and details.
- Precise control: Provides precise control over the avatar's poses and expressions.
- Generalization ability: Can generalize to new poses and expressions, even those unseen during training.
Technical Principles of One Shot, One Talk
- Pose-guided image-to-video diffusion model: Based on the model, generates imperfect video frames as pseudo-labels to achieve generalization to new poses and expressions.
- 3DGS-mesh hybrid avatar representation: Combines 3D Gaussian Splatting (3DGS) and parametric mesh models (such as SMPL-X) to enhance the avatar's expressiveness and realism.
- Key regularization techniques: Applies regularization techniques to mitigate inconsistencies caused by pseudo-labels, ensuring the accuracy of the avatar's structural and dynamic modeling.
- Pseudo-label generation: Uses datasets such as the TED Gesture Dataset to drive pre-trained models and generate video sequences of the target person performing different poses and expressions.
- Loss functions and constraints: Designs multiple loss functions and constraint terms, including perceptual loss (such as LPIPS) and pixel-level loss, to effectively extract information from the input image and pseudo-labels and stabilize the avatar reconstruction process.
- Optimization and training: Uses the Adam optimizer for training, balancing different loss functions based on carefully designed loss weights to achieve optimal avatar reconstruction results.
Project Address of One Shot, One Talk
- Project website:xiangjun-xj.github.io/OneShotOneTalk
- arXiv technical paper:https://arxiv.org/pdf/2412.01106
Application Scenarios of One Shot, One Talk
- Augmented reality (AR) and virtual reality (VR): In AR/VR applications, create realistic virtual characters to enhance users' immersion and interactive experience.
- Remote meetings and telepresence: By generating realistic full-body dynamic avatars, it can be used in remote meetings to make remote communication more natural and efficient.
- Games and entertainment: In game and film production, quickly generate or customize characters, reducing the time and cost of traditional motion capture and modeling.
- Social media and content creation: Users create personalized virtual images for use on social media platforms or as virtual streamers for content creation.
- Education and training: In virtual teaching environments, teachers have realistic virtual images, enhancing the effectiveness of remote teaching.