
What Is OmniVision
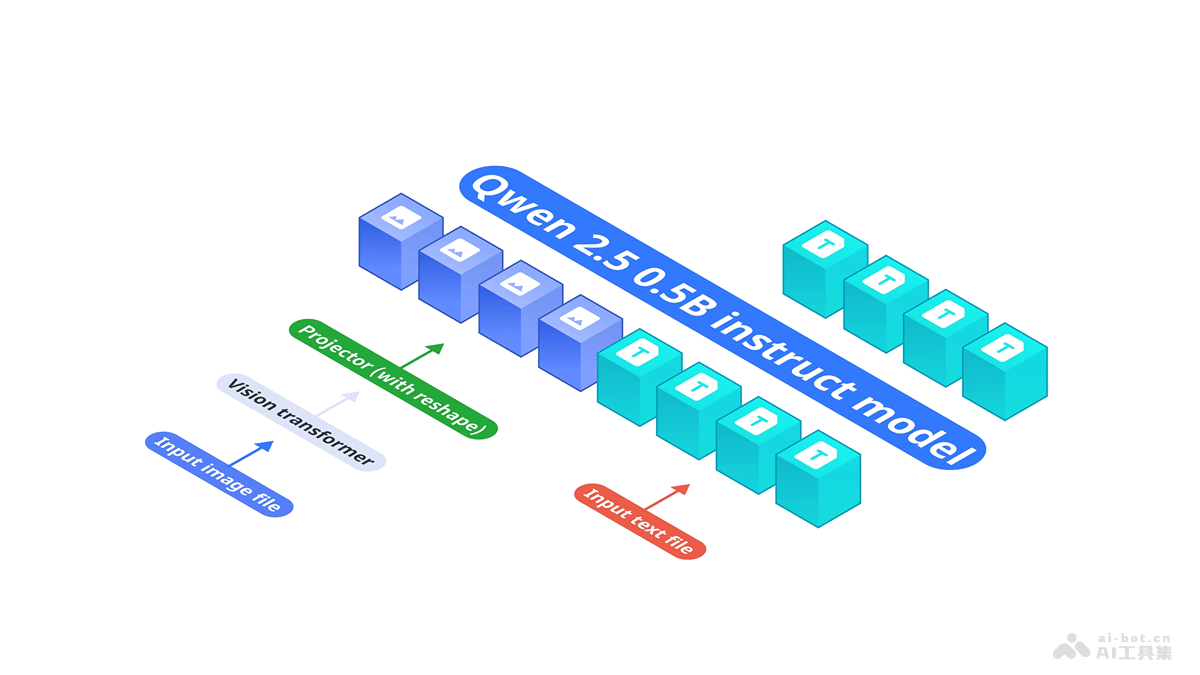
OmniVision is a compact multimodal model with 968M parameters, optimized for edge devices. OmniVision can process visual and text inputs, is improved based on the LLaVA architecture, significantly reduces the number of image tokens, and lowers latency and computational cost. Trained with DPO based on trustworthy data, OmniVision provides more reliable results and is suitable for tasks such as visual question answering and image captioning.
OmniVision's Main Features
- Visual Question Answering: OmniVision can understand image content and give accurate answers to questions asked about images.
- Image Captioning: The model can generate text that describes image content.
- End-to-End Visual Language Understanding: By integrating a visual encoder and a language model, OmniVision achieves seamless conversion from images to text, understanding image content and expressing it in natural language.
- Optimized Edge Deployment: Optimized for edge devices, it reduces the demand for computing resources, and the model runs in resource-constrained environments.
OmniVision's Technical Principles
- Compact Multimodal Architecture: OmniVision combines the base language model Qwen2.5-0.5B-Instruct and the visual encoder SigLIP-400M, and based on an MLP projection layer aligns image embeddings with the text token space, achieving end-to-end visual language understanding.
- Efficient Token Processing: Based on technological innovation, OmniVision greatly reduces the number of image tokens, lowering the model's computational cost and latency while maintaining model performance.
- Precise Training Strategy: Based on a three-stage training process, including pretraining, supervised fine-tuning, and direct preference optimization, it improves the model's accuracy in understanding and responding to vision and language.
OmniVision's Project Address
- Project Official Website:nexa.ai/blogs/omni-vision
- HuggingFace Model Library:https://huggingface.co/NexaAIDev/omnivision-968M
OmniVision's Application Scenarios
- Visual Question Answering: Users ask questions about image content, and OmniVision can understand the questions and give accurate answers combined with the image content.
- Image Captioning: The model can automatically generate descriptive text for images, suitable for fields such as social media, content management, and image archiving.
- Content Moderation: With visual and text understanding capabilities, OmniVision can assist in content moderation of images and text and identify inappropriate content.
- Assisted Visual Search: On e-commerce platforms or in image databases, users search for specific images based on descriptions, and OmniVision can understand the descriptions and match related images.
- Intelligent Assistants and Chatbots: Integrated into chatbots, OmniVision can understand the image and text information sent by users and provide a richer and more accurate interactive experience.