
What is OmniVinci
OmniVinci is an omni-modal large language model launched by NVIDIA, specifically designed to handle multimodal tasks involving vision, hearing, language, and reasoning. It achieves cross-modal semantic alignment through its unique OmnialignNet technology, solves temporal synchronization issues with the Temporal Embedding Grouping mechanism, and optimizes temporal perception capabilities using Constrained Rotary Time Embedding. In benchmarks such as Dailyomni, its performance surpasses models like Qwen2.5, especially excelling in audio-visual synchronization understanding tasks. The model requires only 0.2 trillion tokens for training, far more efficient than similar products, and is suitable for scenarios such as media analysis and game development.
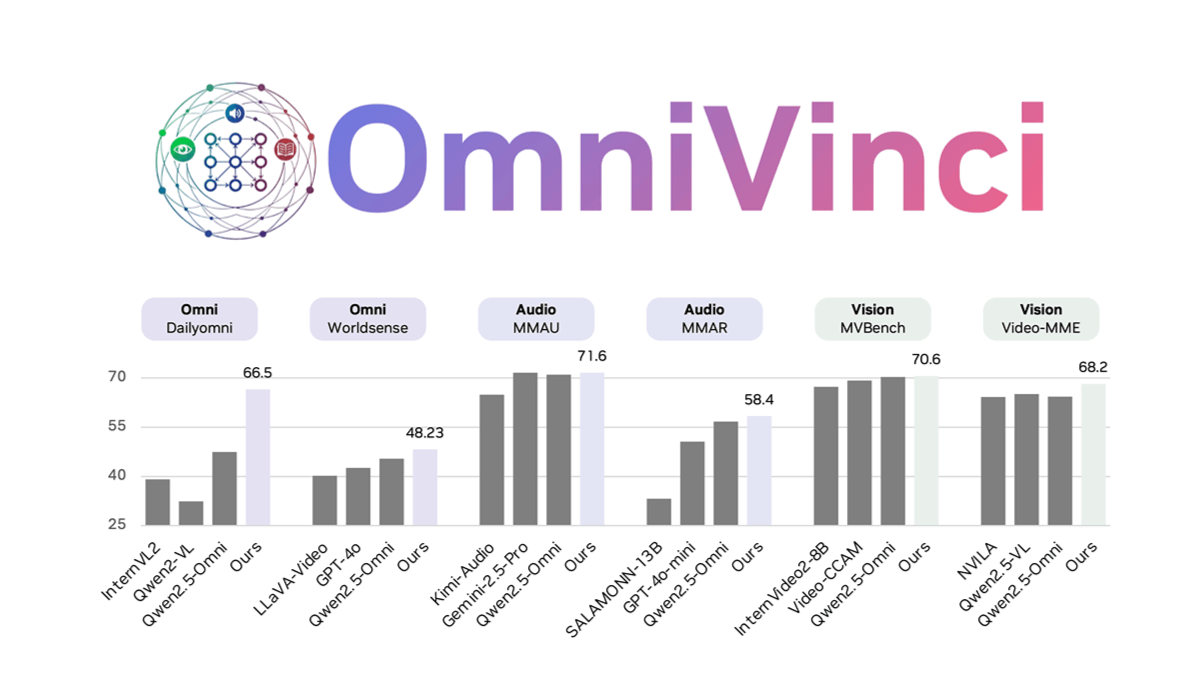
OmniVinci's Main Features
- Multimodal Understanding OmniVinci can simultaneously process visual (images, videos), audio, and text information, achieving joint cross-modal understanding. It can accurately fuse data from different modalities, for example, understanding a person's actions, speech content, and scene background in a video.
- Cross-Modal Alignment Through the OmniAlignNet module, OmniVinci can strengthen the alignment of visual and audio embeddings in a shared omni-modal latent space, solving the problem of modal semantic disconnection in traditional models and improving the fusion effect of multimodal data.
- Temporal Information Processing OmniVinci introduces Temporal Embedding Grouping and Constrained Rotary Time Embedding technologies, which can effectively handle the temporal alignment of visual and audio signals as well as the encoding of absolute time information, making it suitable for scenarios requiring time series analysis, such as video surveillance and audio analysis.
- Broad Application Scenarios OmniVinci is suitable for various practical application scenarios, including video content analysis, medical AI, robot navigation, speech transcription and translation, and industrial inspection, providing powerful multimodal solutions for different fields.
- Open Source and Community Co-Building OmniVinci's code, data, and web demo are all open-sourced, making it convenient for researchers and developers to use and improve, promoting the development of the omni-modal AI research community.
OmniVinci's Technical Principles
- OmniAlignNet Module Through the OmniAlignNet module, OmniVinci strengthens the alignment of visual and audio embeddings in a shared omni-modal latent space, solving the problem of modal semantic disconnection in traditional models and improving the fusion effect of multimodal data.
- Temporal Embedding Grouping OmniVinci adopts Temporal Embedding Grouping technology to capture the relative temporal alignment between visual and audio signals, effectively handling time series information in multimodal data and enhancing the model's understanding of temporal logic.
- Constrained Rotary Time Embedding OmniVinci introduces Constrained Rotary Time Embedding, which achieves precise marking of absolute time information through dimension-sensitive rotary encoding, further enhancing the model's ability to process temporal information, making it suitable for scenarios requiring time series analysis.
- Data Optimization and Synthesis OmniVinci, through carefully designed data synthesis and optimization processes, generated 24 million unimodal and omni-modal dialogue samples, of which 15% are explicit omni-modal synthetic data. Through multi-model collaborative error correction, it eliminates "modal hallucinations" and improves data quality.
- Efficient Training Strategy OmniVinci uses only 0.2T training tokens, compared to 1.2T for other models, greatly reducing training costs. At the same time, by optimizing the training process, the model performs excellently in multimodal tasks with higher training efficiency.
- Reinforcement Learning Enhancement OmniVinci is trained under the GRPO reinforcement learning framework, improving the model's convergence speed and performance through audio-visual integration, enabling it to perform better in multimodal tasks.
- Model Architecture Innovation OmniVinci has made multiple innovations in model architecture, including modules such as OmniAlignNet, Temporal Embedding Grouping, and Constrained Rotary Time Embedding, which significantly improve the model's performance in multimodal tasks.
OmniVinci's Project Address
- Project Official Website:https://nvlabs.github.io/OmniVinci/
- Github Repository:https://github.com/NVlabs/OmniVinci
- HuggingFace Model Library:https://huggingface.co/nvidia/omnivinci
- arXiv Technical Paper:https://arxiv.org/pdf/2510.15870
OmniVinci's Application Scenarios
- Video Content Analysis : OmniVinci can describe in detail the character actions, dialogue content, and scene details in videos, making it suitable for scenarios such as video commentary, sports game analysis, and news reporting, providing users with a richer understanding of video content.
- Medical AI : By combining doctors' oral explanations with medical imaging (such as CT, MRI, etc.), OmniVinci can accurately answer highly difficult questions, helping doctors with diagnosis and treatment plan formulation, and improving medical efficiency and accuracy.
- Robot Navigation : By controlling robot actions through voice commands, OmniVinci can enable more efficient human-robot interaction, making it suitable for scenarios such as home service robots and industrial robots, and improving the intelligence and flexibility of robots.
- Speech Transcription and Translation : OmniVinci supports speech transcription and multilingual translation, making it suitable for scenarios such as real-time meetings, voice assistants, and online education, helping users better understand and communicate.
- Industrial Inspection : In industrial production, OmniVinci can combine visual and audio information for scenarios such as semiconductor device inspection and production line monitoring, improving inspection accuracy and efficiency and reducing labor costs.
- Intelligent Security : OmniVinci can be used in video surveillance systems to detect abnormal behavior and events in real time by analyzing visual and audio information in videos, improving the intelligence level of security systems.