
What Is OmniGen
OmniGen is a new diffusion model for unified image generation that can handle multiple image generation tasks within a single framework, such as text-to-image generation, image editing, subject-driven generation, and visual conditional generation. OmniGen involves traditional computer vision tasks, transforming them into image generation tasks to enhance the model's complex image generation capabilities. OmniGen has a simplified architecture and does not require an additional text encoder, allowing users to complete complex tasks with instructions and without additional preprocessing steps, simplifying the image generation workflow. OmniGen demonstrates reasoning capabilities and a chain-of-thought mechanism, can handle multi-step image editing tasks, and shows rapid learning ability for new tasks in few-shot learning.
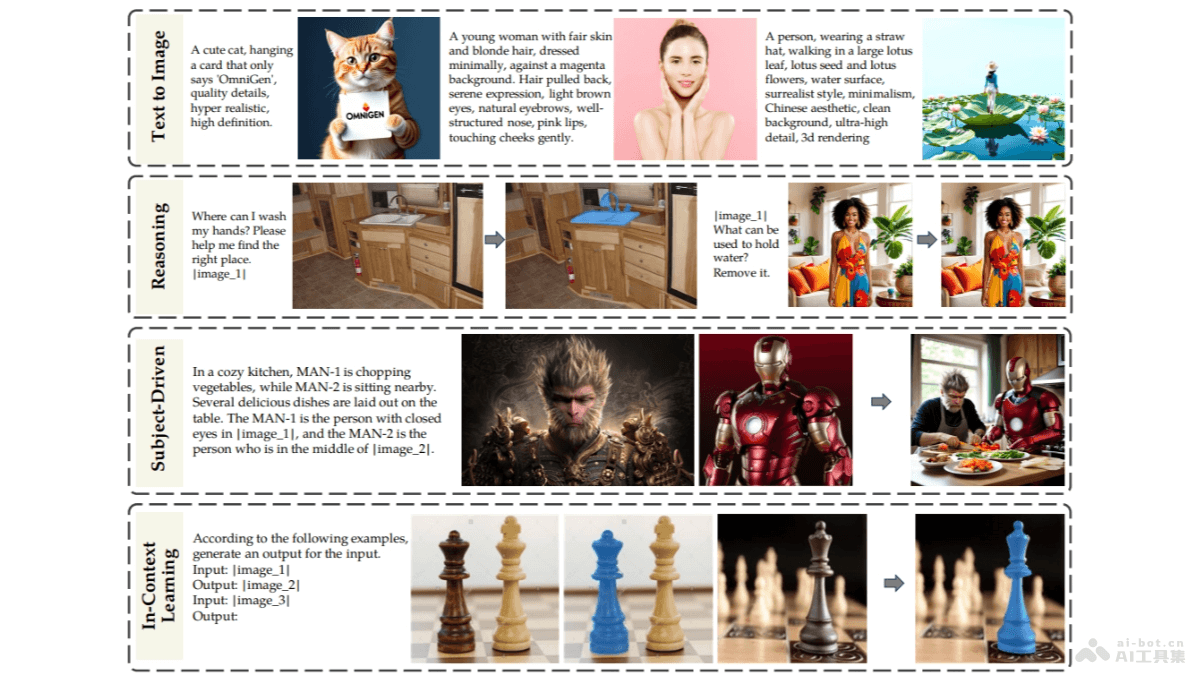
OmniGen's Main Features
- Text-to-Image Generation: Generate corresponding images based on given text descriptions.
- Image Editing: Edit existing images, such as adding or removing image elements.
- Subject-Driven Generation: Generate new images based on a specific subject or object.
- Visual Conditional Generation: Generate new images based on visual conditions such as edge detection or depth maps.
- Computer Vision Tasks: Perform computer vision tasks such as human pose estimation and edge detection.
OmniGen's Technical Principles
- Unified Framework Design: OmniGen uses a unified architecture to handle multiple image generation tasks without additional modules or network structures.
- Simplified Network Architecture: It omits an additional text encoder, reducing model complexity and improving parameter utilization efficiency.
- Multimodal Input Support: The model accepts interleaved inputs of text and images, using free-form input to provide conditions that guide image generation.
- Attention Mechanism: OmniGen adopts holistic modeling for images and uses a bidirectional attention mechanism, allowing elements within an image to attend to each other.
- Iterative Inference Process: During inference, image generation is refined based on multiple iterative steps, supporting accelerated inference, similar to large language models.
OmniGen's Project Address
- Project Website:vectorspacelab.github.io/OmniGen
- GitHub Repository:https://github.com/VectorSpaceLab/OmniGen
- HuggingFace Model Library:https://huggingface.co/Shitao/OmniGen-v1
- arXiv Technical Paper:https://export.arxiv.org/pdf/2409.11340
- Online Experience Demo:https://huggingface.co/spaces/Shitao/OmniGen
OmniGen's Application Scenarios
- Artistic Creation: OmniGen generates images based on text descriptions, providing inspiration for artists and designers or directly creating artworks.
- Media and Entertainment: In fields such as film and game development, it generates scene concept art or game assets, improving creative efficiency.
- Advertising and Marketing: By generating attractive image content, it helps create appealing advertising materials or marketing visual content.
- Education: In the field of education, it creates teaching materials, such as recreations of historical scenes, helping students better understand learning content.
- E-commerce: In e-commerce, it generates product display images, helping improve the visual effects of product pages.