
What is MUMU
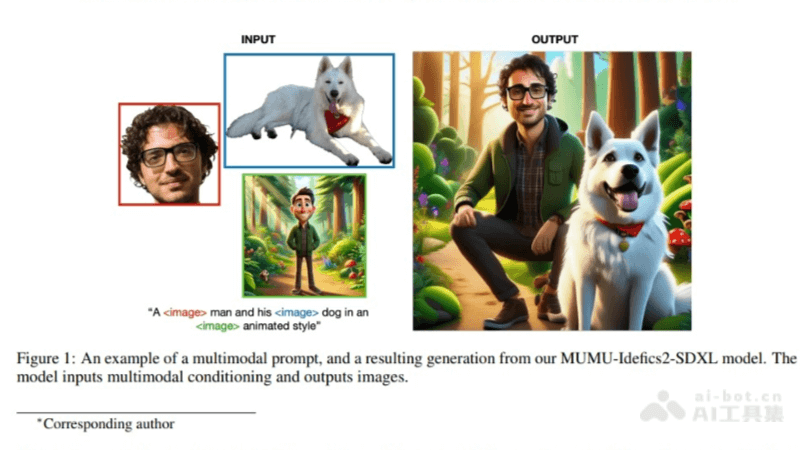
MUMU is a multimodal image generation model that generates target images by combining text prompts and reference images, thereby improving generation accuracy and quality. The architecture of the MUMU model is based on SDXL's pretrained convolutional UNet and is built using the hidden states of the vision-language model Idefics2. During training, the model uses both synthetic data and real data. Through a two-stage training process, MUMU can better preserve the details of the conditioning images and demonstrates generalization ability on tasks such as style transfer and character consistency.
Main Features of MUMU
- Multimodal Input Processing: MUMU can process both text and image inputs simultaneously, and it can generate images consistent with the style of a reference image based on a text description.
- Style Transfer: MUMU can convert realistic-style images into cartoon style or other specified styles, which is very useful in the fields of artistic creation and design.
- Character Consistency: When generating images, MUMU can maintain consistency in character features, preserving the uniqueness of the character even during style transfer or when combined with different elements.
- Detail Preservation: MUMU can better preserve the details of input images when generating images, which is crucial for generating high-quality images.
- Conditional Image Generation: Users can provide specific conditions or requirements, and MUMU can generate images that meet user needs based on these conditions.
Technical Principles of MUMU
- Multimodal Learning: The MUMU model can process multiple types of input data, including text and images. By learning the associations between text descriptions and image content, it generates images that match the text descriptions.
- Vision-Language Model Encoder: The MUMU model uses a vision-language model encoder to process input text and images. The encoder can convert text into vector representations that the model can understand and transform image content into feature vectors.
- Diffusion Decoder: The MUMU model uses a diffusion decoder to generate images. The diffusion decoder is a generative model that generates images by gradually adding details, thereby achieving high-quality image generation.
- Conditional Generation: When generating images, the MUMU model takes into account the conditional information from text and images. This means the model generates new images based on the input text description and reference image, ensuring that the generated images meet the given conditions.
MUMU Project Address
- arXiv Technical Paper:https://arxiv.org/pdf/2406.18790
How to Use MUMU
- Prepare Input Data:Prepare text description: Clearly describe the features and style of the image you want to generate.Prepare reference images: If there are specific styles or elements that need to be reflected in the generated image, you can provide one or more reference images.
- Access the MUMU Model:According to the interface or platform provided by the MUMU model, upload or input your text description and reference images.
- Set Generation Parameters:As needed, set the parameters for image generation, such as resolution, style preference, specific image content, etc.
- Submit Generation Request:Submit the prepared input data and parameters to the MUMU model to request image generation.
- Wait for Generation Results:The model will generate the target image based on the input text and image after a certain amount of computation time.
Application Scenarios of MUMU
- Artistic Creation: Artists and designers can use MUMU to generate images with specific styles and themes based on text descriptions, for use in painting, illustration, or other visual art works.
- Advertising and Marketing: Enterprises can use MUMU to quickly generate attractive advertising images, which can be customized according to marketing strategies and brand styles.
- Game Development: Game designers can use MUMU to generate images of characters, scenes, or props in games, accelerating the visual development process of games.
- Film and Animation Production: In the pre-production of films or animations, MUMU can help concept artists quickly generate visual concept art.
- Fashion Design: Fashion designers can use MUMU to explore design concepts for clothing, accessories, etc., and generate fashion illustrations.