
What is Multi-Speaker
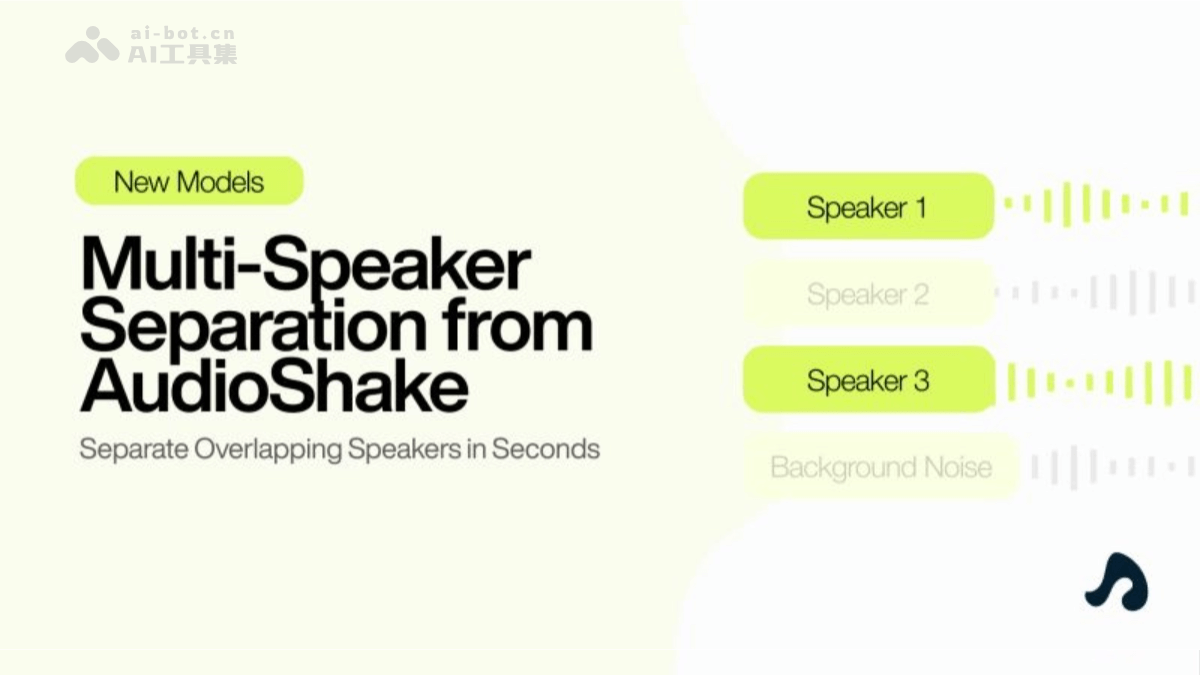
Multi-Speaker is the world's first high-resolution multi-speaker separation model introduced by AudioShake. It supports precisely separating multiple speakers in audio into different tracks, solving the challenge traditional audio tools face when handling overlapping speech. Multi-Speaker is suitable for a variety of scenarios, with an advanced neural architecture supporting high sample rates, suitable for broadcast-grade audio, and capable of processing recordings lasting several hours, maintaining consistent separation results in both high-overlap and low-overlap scenarios, bringing revolutionary changes to audio editing and creation.Multi-Speaker is now officially open, supporting users to access it via AudioShake Live and AudioShake'sAPI interfacefor integration and use.
Main Features of Multi-Speaker
- Speaker separation: Extract the speech of different speakers into separate audio tracks, making it easy to edit individually, adjust volume, or apply special effects.
- Dialogue cleanup: Remove background noise and other interference, provide clear dialogue tracks, and improve audio quality.
- High-fidelity audio processing: Support high sample rates, ensuring the separated audio is suitable for broadcast-grade and high-quality audio production.
- Long recording processing: Process recordings lasting several hours while maintaining consistent separation results.
Technical Principles of Multi-Speaker
- Deep learning model: Based on deep learning algorithms, train the model with large amounts of audio data to recognize and separate the speech features of different speakers.
- Speaker recognition and separation: The model detects different speakers in the audio and extracts the speech into separate tracks. It analyzes the acoustic features of speech (such as timbre, pitch, rhythm, etc.) to distinguish different speakers.
- High sample rate processing: Support high sample rates (such as 44.1kHz or 48kHz), ensuring the separated audio quality meets broadcast-grade standards.
- Dynamic processing capability: Handle various complex scenarios, including highly overlapping dialogue, background noise, and long recordings. The model is based on optimized algorithms to ensure stable separation results in different scenarios.
Multi-Speaker Project Address
- Project website:https://www.audioshake.ai/post/introducing-multi-speaker
Application Scenarios of Multi-Speaker
- Film and television production: Separate multi-speaker dialogue for post-production editing and dubbing.
- Podcast production: Clean up recordings, separate guest speech, and improve sound quality.
- Accessibility services: Help people with disabilities communicate using their own voices.
- User-generated content (UGC): Separate multi-speaker audio for creators to edit.
- Transcription and subtitle production: Reduce subtitle errors and improve subtitle accuracy.