
What is MTVCrafter
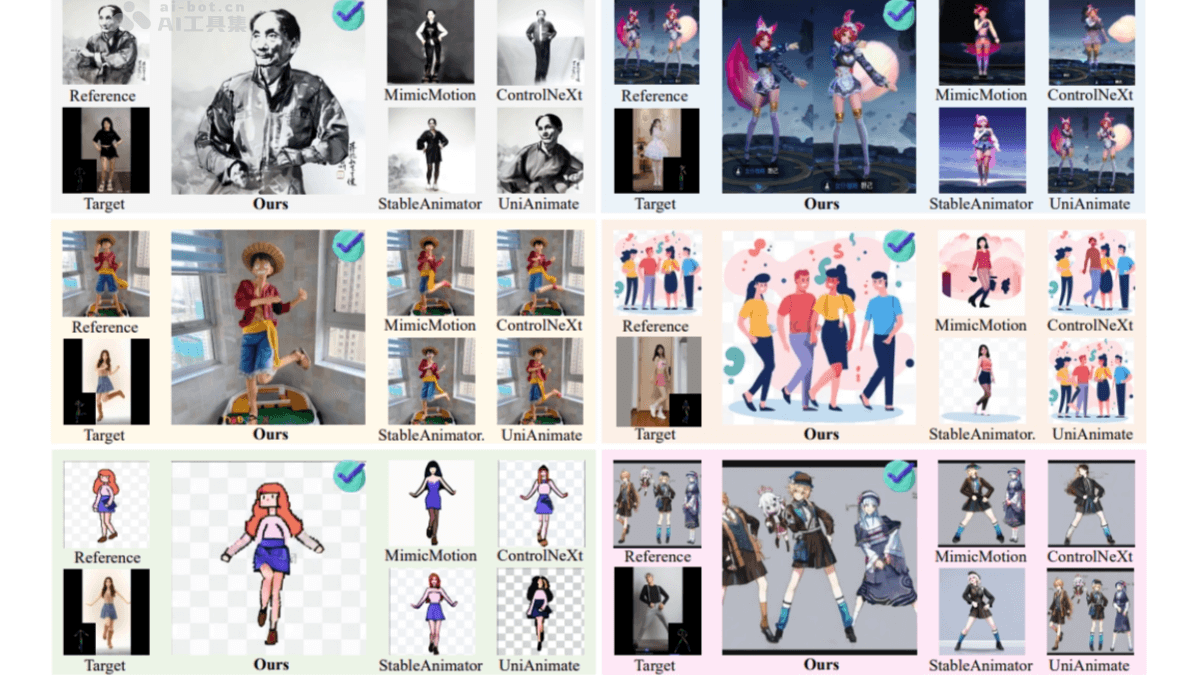
MTVCrafter is a new human image animation framework launched by the Computer Vision and Pattern Recognition Laboratory of the Shenzhen Institute of Advanced Technology, Chinese Academy of Sciences, the Artificial Intelligence Research Institute of China Telecom, and other institutions. It performs high-quality animation generation based on raw 3D motion sequences. The framework is based on 4D Motion Tokenization (4DMoT) to directly model 3D motion data, avoiding the limitations of traditional methods that rely on 2D rendered pose images. The framework introduces a Motion-aware Video Diffusion Transformer (MV-DiT), which uses unique 4D motion attention and positional encoding to effectively use 4D motion tokens as context for animation generation. MTVCrafter achieves an FID-VID score of 6.98 on the TikTok benchmark, 65% higher than the second-place method, demonstrating strong generalization ability and robustness.
Main features of MTVCrafter
- High-quality animation generation: Directly models 3D motion sequences to generate high-quality, natural, and coherent human animation videos.
- Strong generalization ability: Supports generalization to unseen motions and characters, including single and multiple characters, full-body and half-body characters, covering multiple styles (such as anime, pixel art, ink painting, and realistic styles).
- Precise motion control: Based on 4D motion tokenization and motion attention mechanisms, it achieves precise control over motion sequences, ensuring the accuracy and consistency of the animation.
- Identity consistency preservation: During the animation generation process, it preserves the identity features of the reference image, avoiding identity drift or distortion.
Technical principles of MTVCrafter
- 4D Motion Tokenizer (4DMoT): 4DMoT uses an encoder-decoder structure, processing data in the temporal (frame) and spatial (joint) dimensions based on 2D convolution and residual blocks, and uses a vector quantizer to map continuous motion features to a discrete token space. The tokens are represented in a unified space, facilitating subsequent animation generation.
- Motion-aware Video Diffusion Transformer (MV-DiT): Designs a 4D motion attention mechanism that combines 4D motion tokens with visual tokens (such as video frames). Based on 4D rotary position embedding (RoPE), it restores the spatiotemporal relationships lost due to tokenization and flattening. It introduces motion-aware classifier-free guidance, based on learning a joint representation of unconditional and conditional generation, improving generation quality and generalization ability. It uses a simple but effective repetition and concatenation strategy to combine reference images with noisy video latents, ensuring identity consistency.
Project address of MTVCrafter
- GitHub repository:https://github.com/DINGYANB/MTVCrafter
- arXiv technical paper:https://arxiv.org/pdf/2505.10238
Application scenarios of MTVCrafter
- Digital human animation: Generates natural and smooth movements and expressions for digital humans such as virtual streamers, customer service agents, and idols.
- Virtual try-on: Combines user photos and clothing to generate dynamic try-on effects, improving the shopping experience.
- Immersive content: Generates virtual character animations synchronized with user movements in VR and AR, enhancing immersion.
- Film and television special effects: Rapidly generates high-quality character animations, reducing production costs and enhancing the expressiveness of special effects.
- Social media: Allows users to create personalized animations by combining photos and movements, increasing the fun of content.