
What is mPLUG-Owl3
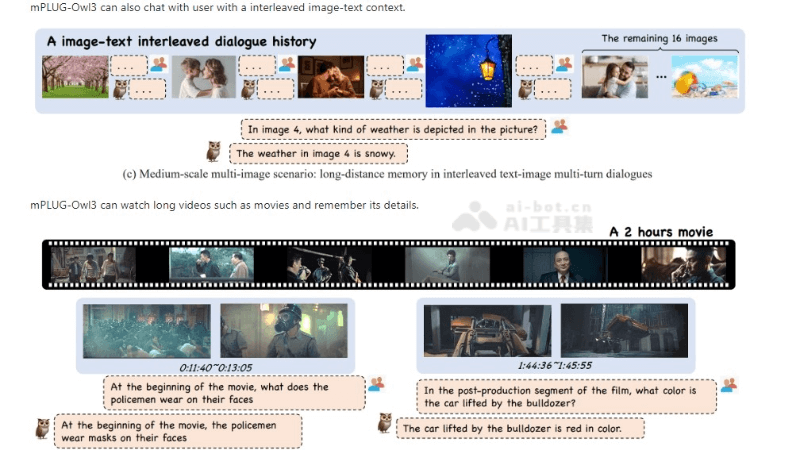
mPLUG-Owl3 is a general-purpose multimodal AI model launched by Alibaba, designed specifically for understanding and processing multiple images and long videos. While maintaining accuracy, it significantly improves inference efficiency, and can analyze a 2-hour movie within 4 seconds. The model adopts an innovative Hyper Attention module to optimize the fusion of visual and language information, and supports multi-image scenarios and long video understanding. mPLUG-Owl3 achieves industry-leading performance on multiple benchmarks, and its paper, code, and resources have been open-sourced for research and applications.
Main Features of mPLUG-Owl3
- Multi-image and long video understanding: Can quickly process and understand multiple images and long video content.
- High inference efficiency: Completes analysis of large amounts of visual information in an extremely short time, such as processing a 2-hour movie within 4 seconds.
- Maintains accuracy: While improving efficiency, it does not sacrifice the accuracy of content understanding.
- Multimodal information fusion: Through the Hyper Attention module, it effectively integrates visual and language information.
- Cross-modal alignment: Model training includes cross-modal alignment, improving the understanding of and interaction capability with image-text information.
Technical Principles of mPLUG-Owl3
- Multimodal fusion: The model understands multi-image and video content by fusing visual information (images) and language information (text). This is achieved through self-attention and cross-attention mechanisms.
- Hyper Attention module: An innovative module used to efficiently integrate visual and language features. Through shared LayerNorm, modality-specific Key-Value mapping, and adaptive gating design, it optimizes parallel processing and fusion of information.
- Vision encoder: Uses a vision encoder such as SigLIP-400M to extract image features, and maps them through a linear layer to the same dimension as the language model for effective feature fusion.
- Language model: For example Qwen2, used to process and understand text information, and enhances language representation by fusing visual features.
- Position encoding: Introduces multimodal interleaved rotary position encoding (MI-Rope), preserving the positional information of images and text, and ensuring the model can understand the relative positions of images and text in the sequence.
Project Addresses of mPLUG-Owl3
- GitHub Repository:https://github.com/X-PLUG/mPLUG-Owl/
- HuggingFace Link:https://huggingface.co/spaces/mPLUG/mPLUG-Owl3
- arXiv Technical Paper:https://arxiv.org/pdf/2408.04840
How to Use mPLUG-Owl3
- Environment preparation: Ensure the necessary software and libraries are installed in the computing environment, such as Python, PyTorch, or other deep learning frameworks.
- Obtain the model: Obtain the pretrained weights and configuration files of the mPLUG-Owl3 model from GitHub or Hugging Face.
- Install dependencies: According to the model documentation, install the required dependency libraries, which may include specific deep learning libraries, data processing libraries, etc.
- Data preparation: Prepare the data you want the model to process, such as images, videos, or image-text pairs. Make sure the data format meets the model input requirements.
- Model loading: Use an appropriate deep learning framework to load the pretrained mPLUG-Owl3 model.
- Data processing: Preprocess the data to adapt it to the model's input format. This includes steps such as image resizing, normalization, and encoding.
- Model Inference: Use the model to perform inference on the data. For multi-image or video content, the model will output its understanding and analysis of the content.
Application Scenarios of mPLUG-Owl3
- Multimodal Retrieval Augmentation: mPLUG-Owl3 can accurately understand the multimodal knowledge passed in and use it to answer questions, and can even point out the specific basis for its judgment.
- Multi-image Reasoning: It can understand the relationships between content in different materials and perform effective reasoning, for example, determining whether animals in different images can survive in a specific environment.
- Long Video Understanding: mPLUG-Owl3 can process and understand long video content in an extremely short time, and can quickly provide answers when asked about detailed segments such as the beginning, middle, and end of a video.
- Multi-image Long-sequence Understanding: Scenarios with multi-image long-sequence input, such as multimodal multi-turn dialogue and long video understanding, demonstrate efficient understanding and reasoning capabilities.
- Ultra-long Multi-image Sequence Evaluation: When faced with ultra-long image sequences and distracting images, mPLUG-Owl3 shows high robustness, maintaining high performance even when hundreds of images are input.