
What is mPLUG-DocOwl 1.5
mPLUG-DocOwl 1.5 is a multimodal large language model launched by Alibaba Group, focusing on OCR-free document understanding. The model is based on unified structure learning, strengthening the ability to understand structural information in text-rich images such as documents, tables, and charts. mPLUG-DocOwl 1.5 includes structure-aware parsing tasks and multi-granularity text localization tasks, covering five domains: documents, web pages, tables, charts, and natural images. The H-Reducer module of mPLUG-DocOwl 1.5 merges horizontally adjacent image patches based on convolutional layers, reducing the length of visual features and preserving layout information, enabling the model to efficiently process high-resolution images. In multiple visual document understanding benchmarks, the model demonstrates industry-leading OCR-free performance, improving SOTA performance by more than 10 points.
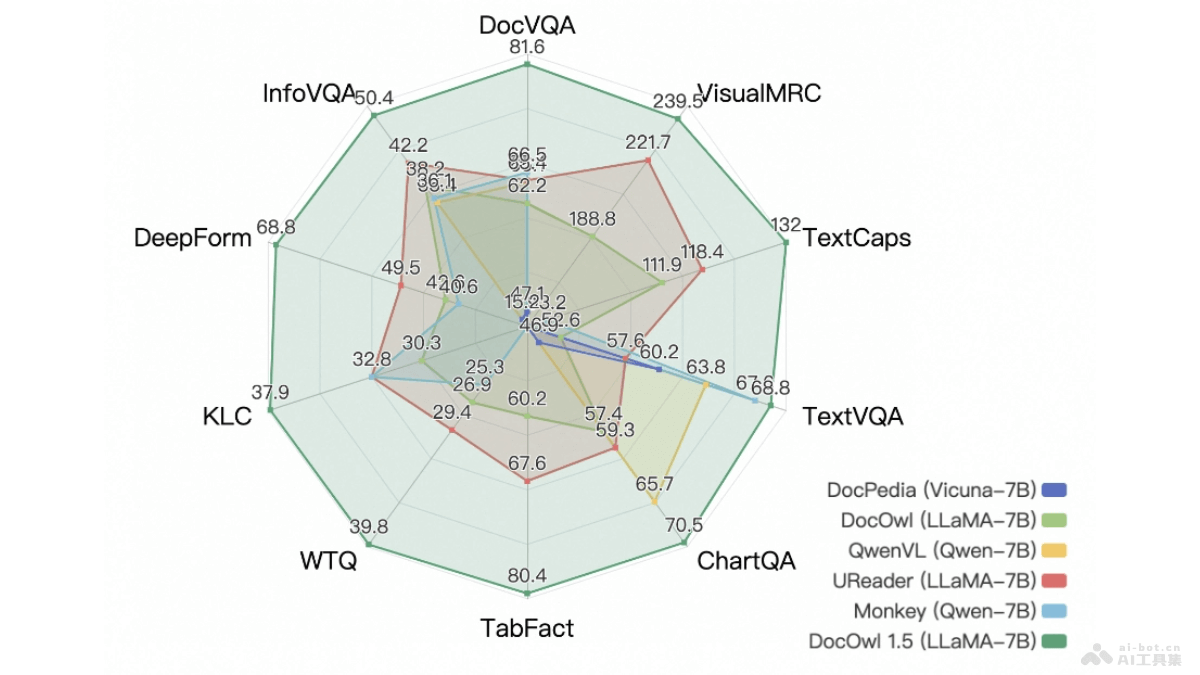
Main Features of mPLUG-DocOwl 1.5
- Structure-Aware Document Parsing: Recognizes and parses the text structure in documents, such as line breaks and spaces, and understands how documents are organized.
- Table-to-Markdown: Converts table images into Markdown format for further processing and reading.
- Chart-to-Markdown: Converts chart images into Markdown format, preserving the key data and structural information in the charts.
- Natural Image Parsing: Parses images in natural scenes, recognizing and understanding the textual information in the images.
- Multi-Granularity Text Localization: Localizes text at different granularity levels (words, phrases, lines, blocks), enhancing the model's ability to identify text positions.
Technical Principles of mPLUG-DocOwl 1.5
- Unified Structure Learning: Based on structure-aware parsing tasks and multi-granularity text localization tasks, the model learns how to understand and process text-rich images.
- H-Reducer Vision-Text Module: Merges horizontally adjacent visual features based on convolutional layers, reduces feature length, preserves layout information, and enables the large language model to process high-resolution images more effectively.
- Multimodal Large Language Model (MLLM): Combines a vision encoder and a large language model, using a vision-to-text module (such as H-Reducer) to enable the model to understand and generate language descriptions related to visual content.
- Large-Scale Dataset Training: Using large-scale annotated datasets such as DocStruct4M and DocReason25K, the model can learn the text structure and semantic information in various documents and images.
- Two-Stage Training Framework: First performs unified structure learning, then performs multi-task tuning, enabling the model to perform excellently in various downstream tasks.
Project Address of mPLUG-DocOwl 1.5
- GitHub Repository:X-PLUG/mPLUG-DocOwl/tree/main/DocOwl1.5
- arXiv Technical Paper:https://arxiv.org/pdf/2403.12895
Application Scenarios of mPLUG-DocOwl 1.5
- Automated Document Processing: In enterprises or government agencies, automatically parses and understands large numbers of documents, such as contracts, invoices, reports, and tables, improving work efficiency and reducing manual intervention.
- Intelligent Search Engines: Integrates mPLUG-DocOwl 1.5 into search engines to enhance the ability to search textual content in images and provide more accurate search results.
- Assisted Reading and Understanding: Helps users better understand the content of complex documents, especially for visually impaired people, by providing easily accessible information based on parsed document structure.
- Education and academic research: In the field of education, assist students and researchers in understanding complex information in textbooks, academic papers, and research materials.
- Customer service and support: In customer service systems, use mPLUG-DocOwl 1.5 to parse documents uploaded by users, automatically extract key information, and provide faster service responses.