
What Is MoE-TTS
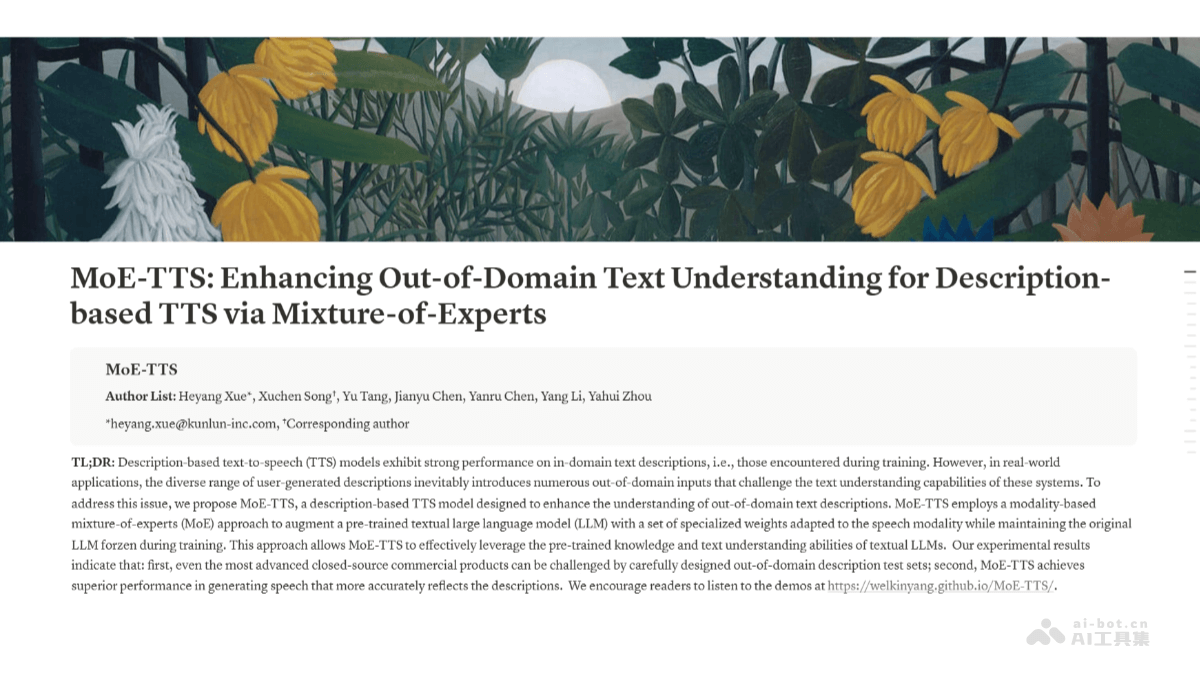
MoE-TTS is the first character description launched by the Kunlun Wanwei speech team based on MoEspeech synthesisframework, specifically used to improve the ability to understand open-domain text descriptions. Through a Mixture-of-Experts (MoE) architecture, the model combines a pretrained large language model (LLM) with speech expert modules. During training, the text module parameters are frozen and only the speech module parameters are updated, preserving the LLM's powerful text understanding ability while enhancing the accuracy of speech generation. Experiments show that MoE-TTS is significantly better than existing commercial models in generating speech that better matches descriptions, especially when handling complex and open-domain descriptions.
MoE-TTS's Main Features
- Enhanced open-domain text understanding: It can accurately understand and generate speech that matches complex, open-domain text descriptions, and supports descriptions that have never appeared in the training data.
- Natural language description-driven: Users can precisely control the style and characteristics of speech through natural language descriptions (such as "an energetic youthful voice" or "an actor with a New York accent").
- High-quality speech generation: The generated speech performs excellently in naturalness, emotional expression, and style consistency, significantly outperforming traditional TTS models.
- Cross-modal knowledge transfer: It transfers the powerful text understanding ability of pretrained language models to speech generation tasks, improving the model's understanding and expression of complex semantics.
MoE-TTS's Technical Principles
-
Pretrained LLM as the base model: It uses a pretrained text LLM as the base model, and freezes parameters to preserve powerful text understanding ability.
-
Modal routing strategy: Based on a modal routing mechanism, text and speech tokens are assigned to text expert and speech expert modules respectively, avoiding interference between modalities.
-
Frozen text expert modules: During training, only the parameters of the speech expert modules are updated, while the parameters of the text expert modules are frozen, ensuring that pretrained knowledge is preserved during training and inference.
-
Modality-aware Transformer components: The core components of the Transformer layer (such as layer normalization, feedforward networks, and multi-head attention) are converted into modality-aware MoE layers, further improving the model's ability to process different modalities.
-
Speech generation module: It combines diffusion models (such as Elucidated Diffusion Models) and VAEGAN components to convert discrete speech tokens into high-quality continuous speech waveforms.
MoE-TTS's Project Address
- Technical Paper:https://teal-aquarius-c17.notion.site/MoE-TTS-Enhancing-Out-of-Domain-Text-Understanding-for-Description-based-TTS-via-Mixture-of-Experts-24e44360bf708040bff3dffe2eef805e#24e44360bf70800c9290cce2d2d14dfe
MoE-TTS's Application Scenarios
- Virtual assistants and intelligent customer service: Make the voice responses of virtual assistants and intelligent customer service natural and fluent, as considerate as a real person, greatly improving the user experience.
- Audio content creation: Generate high-quality speech for audiobooks, podcasts, and more, with varied styles and rich emotions, making the content more appealing.
- Dubbing for digital humans and virtual characters: Generate personalized speech according to character settings, instantly bringing digital humans and virtual characters to life and enhancing realism and expressiveness.
- Education and training: It supports multilingual and multi-style speech generation, helping diversify educational content and making learning more interesting and efficient.
- Games and interactive entertainment: Generate scene-appropriate speech in real time, with a explosive sense of game interaction, vivid and lifelike character dialogue, and maximum immersion.