
What is MMSkills
MMSkills is a multimodal skill framework for general visual Agents jointly launched by Shanghai Jiao Tong University and Xiaohongshu. It supports extending reusable skills from plain text steps into multimodal procedural knowledge comprising text workflows, runtime state cards, and multi-view keyframes. Through a branch loading mechanism, it efficiently invokes visual evidence at runtime, delivering stable improvements for multiple model families such as Gemini, Qwen, Kimi, and GLM on GUI and game tasks including OSWorld, macOSWorld, and VAB-Minecraft.
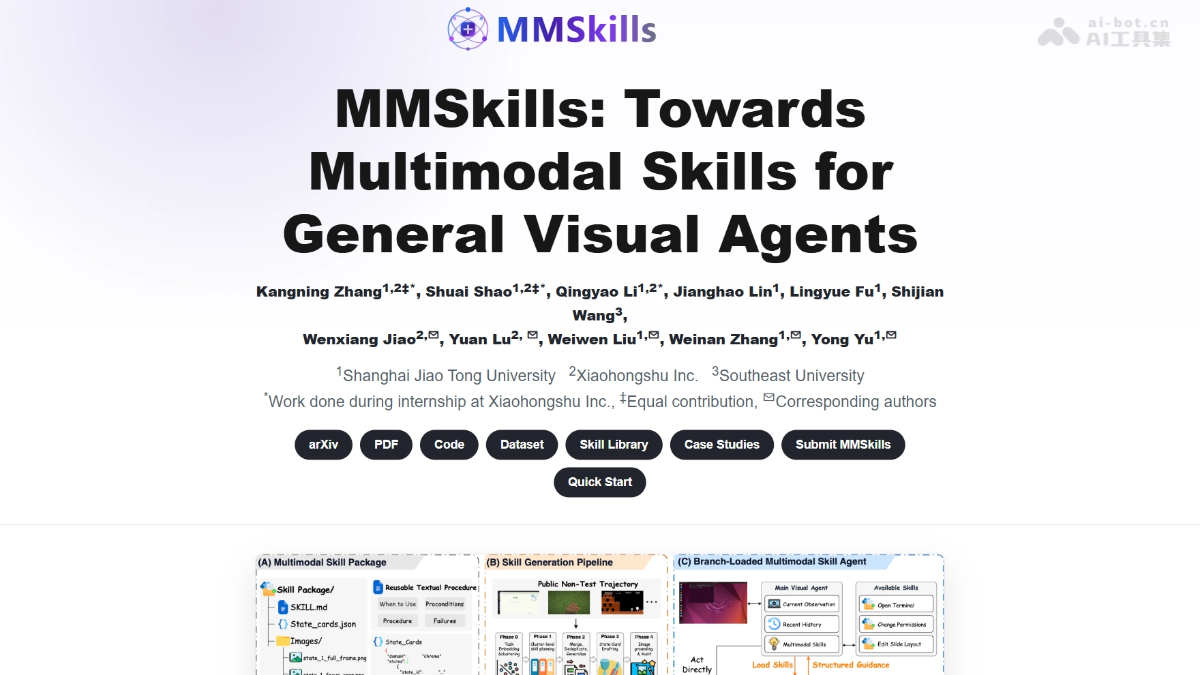
MMSkills' Main Features
- Multimodal Skill Package Construction: Integrates text workflows, runtime state cards, and multi-view keyframes to form reusable visual procedural knowledge units.
- Automated Skill Generation: Based on public non-test interaction trajectories, automatically distills a multimodal skill library through five stages: task clustering, skill planning, merge generalization, and visual auditing.
- Branch Loading: The main Agent temporarily opens a skill branch at runtime, invoking skills on demand instead of injecting the full context at once, avoiding visual evidence polluting the main decision-making process.
- View Selection: Based on the current screenshot, historical actions, and state cards, intelligently selects the most relevant keyframes and views from the skill package for alignment.
- Structured Decision Guidance: After the branch completes visual alignment, returns compact decision support to the main Agent containing applicable, subgoal, plan, do_not_do, and verify.
- Cross-Domain Task Coverage: Simultaneously supports GUI desktop automation and visual game tasks, such as Minecraft and Super Mario Bros, enabling cross-scenario transfer and reuse of multimodal skills.
MMSkills' Technical Principles
- Multimodal Skill Package Definition: MMSkills extends traditional text skills into a complete unit containing the SKILL.md text workflow, State_cards.json runtime state cards, and Images multi-view keyframes, enabling the Agent to determine when to use a skill and how to verify progress based on visual states.
- Automated Skill Generation: Through five stages—task clustering, intra-cluster skill planning, skill merge generalization, text draft generation, visual grounding, and auditing—automatically extracts reusable diagnostic state knowledge from public trajectories, rather than simply saving raw demonstrations.
- Branch Loading Runtime Mechanism: When the main Agent determines a skill may be useful, it temporarily opens a skill branch to execute View Selection to select key state views, then Branch Planning aligns the visual evidence with the current environment and returns compressed structured decision support.

Follow WeChat and reply "Open Source" to join theAI Open Source Project Exchange Group
How to Use MMSkills
- Obtain the Skill Library: Visit the Hugging Face dataset to download the pre-generated multimodal skill packages.
- Integrate the Main Agent: Connect the MMSkills branch loading mechanism into the inference process of an existing visual Agent.
- Trigger Skill Invocation: The main Agent determines at runtime that the current task may match a certain skill and initiates a branch loading request.
- Receive Structured Guidance: After the temporary branch completes visual evidence alignment, it returns decision support such as applicable, subgoal, and plan.
- Execute and verify: The main Agent executes actions based on the returned guidance and verifies task progress through status cards.
Core advantages of MMSkills
- State-aware decision-making: The skill package includes runtime status cards, enabling the Agent to determine whether the current interface meets the skill's preconditions.
- Visual evidence alignment: Multi-view keyframes help the Agent ground textual conditions in the real screen, avoiding misoperations.
- Efficient context management: Branch Loading prevents the complete skill package from being directly injected into the main context, avoiding reference images polluting the current decision.
- Significant gains for small models: External multimodal procedural knowledge more than doubles performance on small models such as Qwen3-VL-8B, supplementing their insufficient internal process priors.
- Behavior pattern optimization: Significantly reduces invalid clicks and repetitive actions, shifting the Agent from exploratory trial-and-error to state-aware execution.
MMSkills project addresses
- Project website:https://zkangning.github.io/MMSkills_for_Visual_Agents/
- GitHub repository:https://github.com/zkangning/MMSkills_for_Visual_Agents
- HuggingFace model library:https://huggingface.co/datasets/zhangkangning/mmskills
- arXiv technical paper:https://arxiv.org/pdf/2605.13527
Comparison of MMSkills with similar competitors
| Dimension | MMSkills | Text-only Skills |
|---|---|---|
| Skill representation | Text workflow + status cards + multi-view keyframes | Plain text steps or action diagrams |
| State judgment | Determine the current interface state through runtime status cards and screenshots | Infer only from text descriptions, easily overlooking the actual interface state |
| Runtime loading | Branch Loading temporarily and selectively loads visual evidence in branches | Usually injects the complete text skill directly into the main context |
| Context pollution | Filter through View Selection to prevent reference images from polluting the main Agent | Although the text has no image pollution, it lacks visual grounding |
| Typical failure cases | Can identify the currently active worksheet, button availability status, etc. | Prone to creating charts in the wrong worksheet and mistakenly clicking grayed-out buttons |
| Overall OSWorld performance | Gemini 3.1 Pro: 50.11%;Qwen3-VL-235B: 39.17% | Gemini 3.1 Pro: 40.76%;Qwen3-VL-235B: 28.57% |
Application scenarios of MMSkills
-
Desktop GUI automation: Complete complex cross-application operations in Ubuntu / macOS environments (such as LibreOffice chart creation and file permission modification).
-
Game AI agents: Execute long-horizon item acquisition and crafting planning in Minecraft survival mode, or make decisions based on visual states in platformer games.
-
Enterprise RPA enhancement: Add visual state awareness to existing robotic process automation systems to improve the stability of cross-software operations.
-
Visual task teaching: Consolidate manual operation experience into a reusable multimodal skill library for training or assisting other Agents in learning.