
What is MMSI-Video-Bench
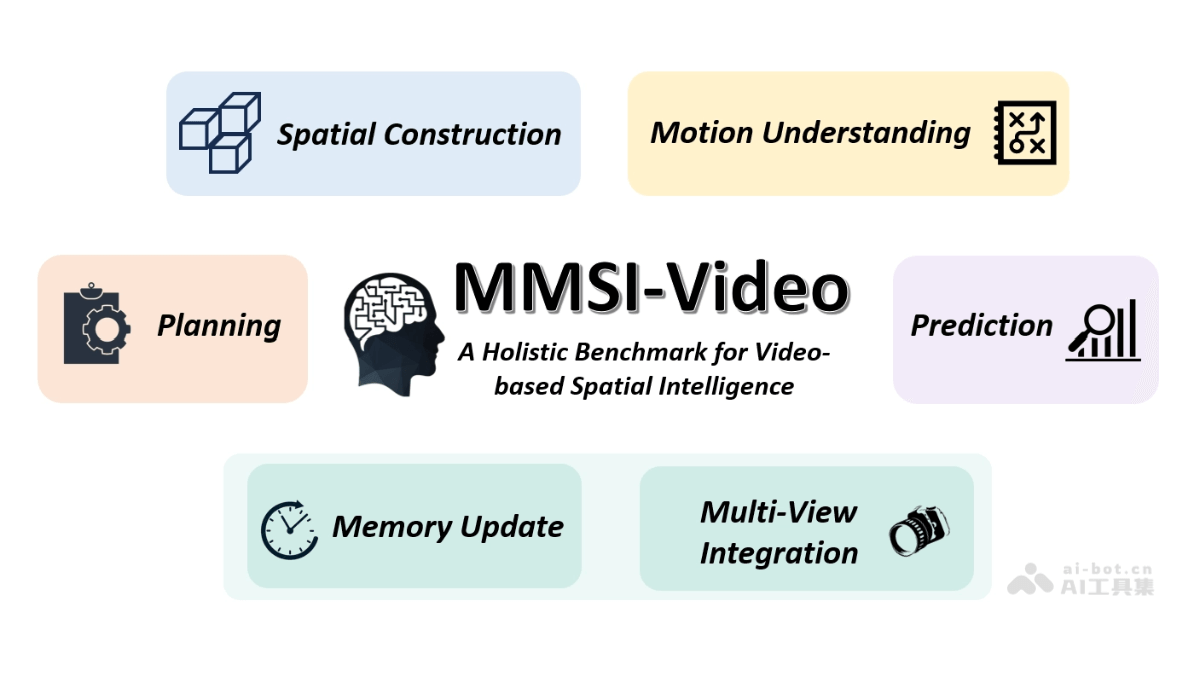
MMSI-Video-Bench is a benchmark tool for evaluating the capabilities of Multimodal Large Language Models (MLLMs) in video spatial intelligence. Jointly launched by Shanghai Artificial Intelligence Laboratory and multiple universities, it comprehensively evaluates models' spatial understanding and reasoning abilities in the real physical world. The benchmark contains 1,278 video clips from 25 public datasets and 1 self-built dataset, covering various complex scenarios such as indoor scenes, outdoor street scenes, and robotic manipulation. The questions were meticulously designed by 11 3D vision researchers, ensuring high challenge and accuracy. Through a multi-level task design, MMSI-Video-Bench covers capabilities such as spatial perception, motion understanding, planning, prediction, and cross-video reasoning, comprehensively examining models' video understanding and decision-making abilities.
Main Features of MMSI-Video-Bench
-
Multimodal Capability Evaluation: It is a benchmark tool specifically designed to evaluate the performance of Multimodal Large Language Models (MLLMs) in video spatial intelligence, and can comprehensively measure models' understanding and reasoning abilities regarding video content.
-
Diverse Datasets: It contains 1,278 video clips from 25 public datasets and 140 anonymous internal videos, covering various complex scenarios such as indoor scenes, outdoor street scenes, and robotic manipulation, ensuring the diversity and richness of the data.
-
High-Quality Annotation: All questions are designed and annotated by 3D vision experts, and each question is accompanied by a detailed explanatory rationale, ensuring the accuracy and high quality of the annotations.
-
Comprehensive Task Design: Through a multi-level task framework, it covers capabilities such as spatial perception, motion understanding, planning, prediction, and cross-video reasoning, comprehensively examining models' performance in video spatial intelligence.
-
Model Performance Measurement: It provides detailed evaluation results for 25 open-source and proprietary MLLMs, helping researchers and developers understand the strengths and weaknesses of models and guiding model improvement and optimization.
Technical Principles of MMSI-Video-Bench
-
Real-Scenario Driven: It uses dynamic video data from the real physical world, breaks away from reliance on template generation, and builds a testing environment full of uncertainty and diversity.
-
Multimodal Fusion: It integrates multiple modal information such as vision and language in videos, requiring models to accurately capture the occurrence points of key events and spatial associations in the spatiotemporal dimension.
-
Task Design: Based on a four-level framework of perception, planning, prediction, and cross-video reasoning, it designs multi-dimensional reasoning tasks covering across time, perspectives, and objects.
-
Expert Annotation: Each question is meticulously designed and reviewed by 3D vision experts, ensuring the precision and unambiguity of the questions.
-
Dynamic Testing Environment: By introducing natural behaviors and physical laws in real scenarios to generate questions, it forces models to deeply understand the spatial relationships between objects in videos, their motion trajectories, and the causal logic behind them.
-
Fine-Grained Annotation System: A fine-grained annotation system has been established, covering multi-level cognitive tasks from basic spatial relationships to high-order causal reasoning.
Project Address of MMSI-Video-Bench
- Project Official Website:https://rbler1234.github.io/MMSI-VIdeo-Bench.github.io/
- Github Repository:https://github.com/InternRobotics/MMSI-Video-Bench
- Huggingface Model Library:https://huggingface.co/datasets/rbler/MMSI-Video-Bench
- arXiv Technical Paper:https://arxiv.org/pdf/2512.10863
Application Scenarios of MMSI-Video-Bench
-
Model Performance Evaluation: Used for comprehensively evaluating the performance of Multimodal Large Language Models (MLLMs) in video understanding tasks, helping researchers and developers understand the strengths and weaknesses of models.
-
Academic Research: Provides a standardized testing platform for the academic community to research and improve the performance of multimodal models in video spatial intelligence.
-
Technical Development: Helps developers optimize and improve multimodal models, especially in key capabilities such as spatial perception, motion understanding, planning, and prediction.
-
Industry Application Testing: Suitable for fields such as autonomous driving, robot navigation, and intelligent surveillance, used to test model performance in real-world application scenarios.
-
Education and Training: As a teaching resource, it helps students and researchers better understand and practice multimodal video understanding technology.
-
Model Comparative Analysis: Provides a unified testing benchmark for different multimodal models, facilitating horizontal comparison and performance analysis.