
What is MMedAgent
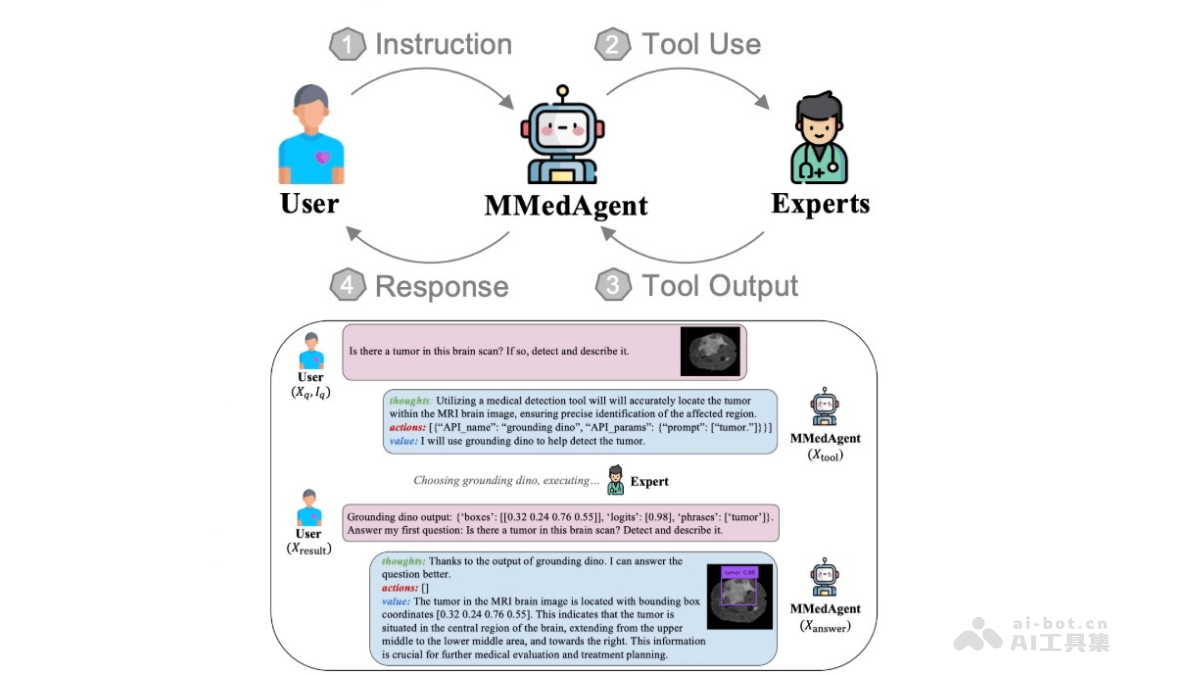
MMedAgent is a multimodal AI agent designed specifically for the medical field, managing multiple medical tasks by integrating various open-source medical models. The system includes an instruction-tuned multimodal large language model (MLLM) that serves as an action planner and result aggregator, along with a set of medical tools tailored for the agent, each targeting specific tasks in the medical field. MMedAgent can handle multiple medical imaging modalities including MRI, CT, X-ray, and more, supporting various data types encountered in clinical practice. By understanding user instructions and medical images, it generates formatted instructions to invoke specific tools and aggregates the tools' outputs to accurately and comprehensively reply to the user. MMedAgent outperforms existing open-source methods on multiple medical tasks, even surpassing the closed-source model GPT-4o.
Main Features of MMedAgent
- Multimodal Task Processing: MMedAgent can handle multiple language and multimodal tasks including grounding, segmentation, classification, medical report generation (MRG), and retrieval-augmented generation (RAG).
- Medical Imaging Support: The system supports multiple medical imaging modalities such as MRI, CT, and X-ray, adapting to various data types encountered in clinical practice.
- Tool Integration and Invocation: MMedAgent integrates multiple tools covering seven representative medical tasks and can select appropriate tools to invoke based on user instructions.
- Instruction Fine-Tuning: MMedAgent trains a multimodal large language model (MLLM) as an action planner by creating an instruction tuning dataset to understand and execute user instructions.
- Result Aggregation: The MLLM serves as a result aggregator, combining the tools' outputs with the user's instructions and images to generate the final answer.
- End-to-End Training: MMedAgent performs end-to-end training on the generated sequences via an autoregressive objective, ensuring the model can use the correct tools and answer questions based on the tool results.
Technical Principles of MMedAgent
- System Architecture: MMedAgent consists of two main parts:
- An instruction-tuned multimodal large language model (MLLM) that serves as an action planner and result aggregator.
- A set of medical tools tailored for the agent, each targeting specific tasks in the medical field.
- Workflow: The workflow of MMedAgent includes four steps:
- The user provides instructions and medical images.
- The MLLM understands the instructions and images and generates formatted instructions to invoke specific tools.
- Execute the tools and return the results.
- The MLLM combines the tools' outputs with the user's instructions and images to generate the final answer.
- Instruction Fine-Tuning: MMedAgent adopts a unified dialogue format to ensure its role as an action planner and result aggregator. After receiving user input, MMedAgent generates three parts:
- Thought: Determine whether an external tool is needed.
- API Name and API Params: The name and parameters of the API call.
- Value: The tool outputs aggregated by the MLLM and the natural language response.
- Autoregressive Objective Training: MMedAgent trains the generated sequences end-to-end through an autoregressive objective, ensuring that the model can use the correct tools and answer questions based on the tools' results.
MMedAgent's project address
- Github repository:https://github.com/Wangyixinxin/MMedAgent
- arXiv technical paper:https://arxiv.org/pdf/2407.02483
Application scenarios of MMedAgent
- Visual Question Answering (VQA): MMedAgent can handle questions related to medical imaging, provide answers based on image content, and support multiple imaging modalities such as MRI, CT, X-ray, histology, and gross pathology.
- Classification tasks: By using the BiomedCLIP tool, MMedAgent can perform zero-shot and fine-grained medical image classification.
- Localization and segmentation tasks: MMedAgent integrates the Grounding DINO and MedSAM tools for localization and segmentation tasks in medical imaging, including bounding box prompt-based segmentation (Segmentation) and text prompt-based segmentation (G-Seg).
- Medical Report Generation (MRG): Using the ChatCAD tool, MMedAgent can generate accurate medical reports from chest X-ray images.
- Retrieval-Augmented Generation (RAG): Through the ChatCAD+ tool, MMedAgent can obtain the most relevant information from external data sources to support the medical retrieval process.
- Cross-modal medical task processing: MMedAgent can seamlessly leverage various medical tools to handle a wide range of medical tasks across different imaging modalities.