
What is MM1.5
MM1.5 is a multimodal large language model released by Apple, designed to enhance text-rich image understanding, visual referring and grounding, and multi-image reasoning capabilities. The model is based on a data-centric training approach, achieving high performance from 1B to 30B parameter scales through large-scale pretraining, continued pretraining with high-resolution OCR data, and optimized visual instruction fine-tuning. MM1.5 includes dense and MoE variants, demonstrating that small-scale models can achieve strong performance through refined data curation and training strategies. MM1.5 introduces specialized variants MM1.5-Video and MM1.5-UI optimized for video understanding and mobile UI understanding, providing in-depth insights into the training process and decisions based on empirical research, offering guidance for the future development of multimodal AI technology.
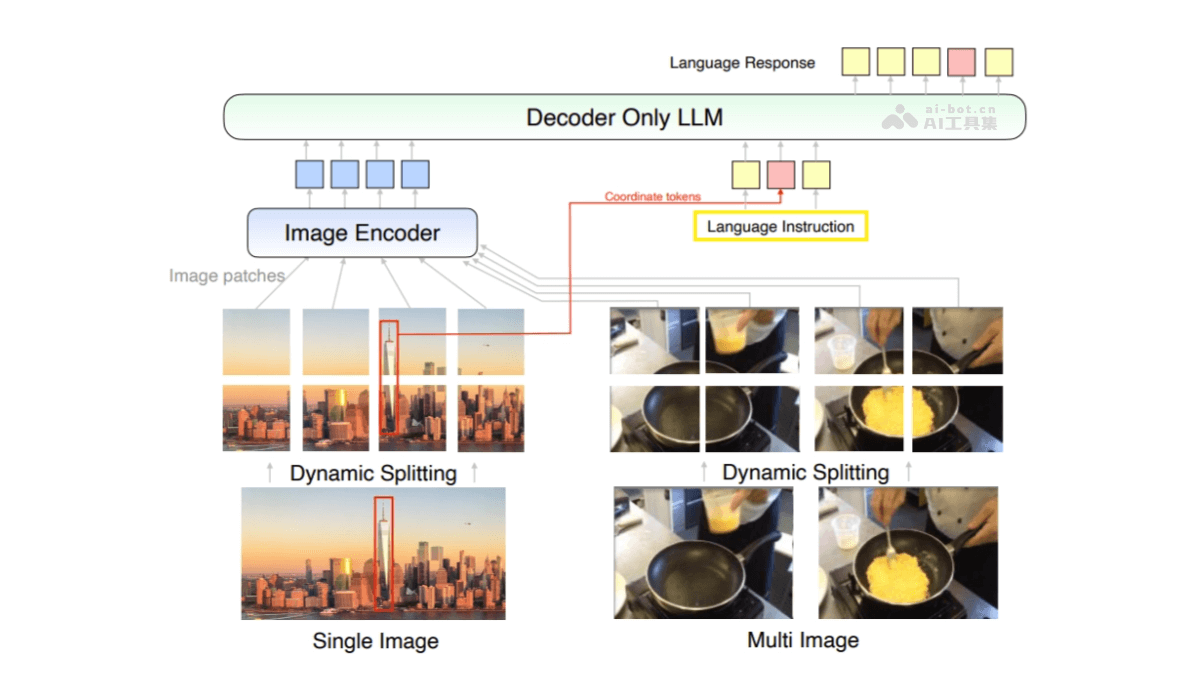
Main features of MM1.5
- Text-rich image understanding: MM1.5 can understand the text content in images as well as the relationship between text and image content.
- Visual referring and grounding: The model identifies specific objects in images and understands references to objects in text, such as "that red ball".
- Multi-image reasoning: MM1.5 can analyze multiple images, understand the connections between images, and perform logical reasoning.
- Video understanding: Based on the MM1.5-Video variant, the model can understand video content, including actions, events, and temporal sequences.
- Mobile UI understanding: The MM1.5-UI variant is specifically designed for understanding mobile application interfaces, recognizing and operating interface elements.
Technical principles of MM1.5
- Deep learning and natural language processing: Combining deep learning visual models and natural language processing technology, the model can understand and generate text related to image content.
- Coordinate tokens and visual attention mechanism: Using coordinate tokens to locate objects in images, focusing on specific regions of the image based on the visual attention mechanism.
- Image segmentation and multimodal fusion: Dividing images into multiple parts, fusing them with text information, and supporting multi-image reasoning.
- Video frame sampling and temporal analysis: Sampling video frames, analyzing the temporal relationships between frames, and understanding video content.
- Interface element recognition: Using image recognition technology to identify elements on mobile interfaces, such as buttons and icons.
Project address of MM1.5
- arXiv technical paper:https://arxiv.org/pdf/2409.20566v1
Application scenarios of MM1.5
- Image and video understanding: MM1.5 can understand and analyze image and video content, applied in fields such as image annotation, video content analysis, and security monitoring.
- Visual search: In e-commerce or digital libraries, MM1.5 helps users search for specific products or documents based on descriptions or query images.
- Assisted driving and autonomous driving: In the automotive industry, MM1.5 is used to understand and analyze road conditions, assisting driving decisions.
- Intelligent assistant: In smartphones and smart home devices, MM1.5 provides a more natural and intuitive way of interaction, understanding users' voice or text commands.
- Education and training: As an educational tool, MM1.5 helps students understand complex concepts and provides personalized learning experiences.