
What is MinT
MinT (Mind the Time) is a multi-eventvideo generationframework jointly launched by Snap Research, the University of Toronto, and the Vector Institute. Based on precise temporal control, it generates video sequences containing multiple events according to text prompts. MinT's core technology is time-based positional encoding (ReRoPE), which enables the model to associate specific text prompts with the corresponding time periods in the video, ensuring that events occur in order and controlling the duration of each event. As the first model to provide temporal control of events in video, MinT surpasses existing open-source models in generating coherent, dynamically connected events, bringing new flexibility and control capabilities to video content creation.
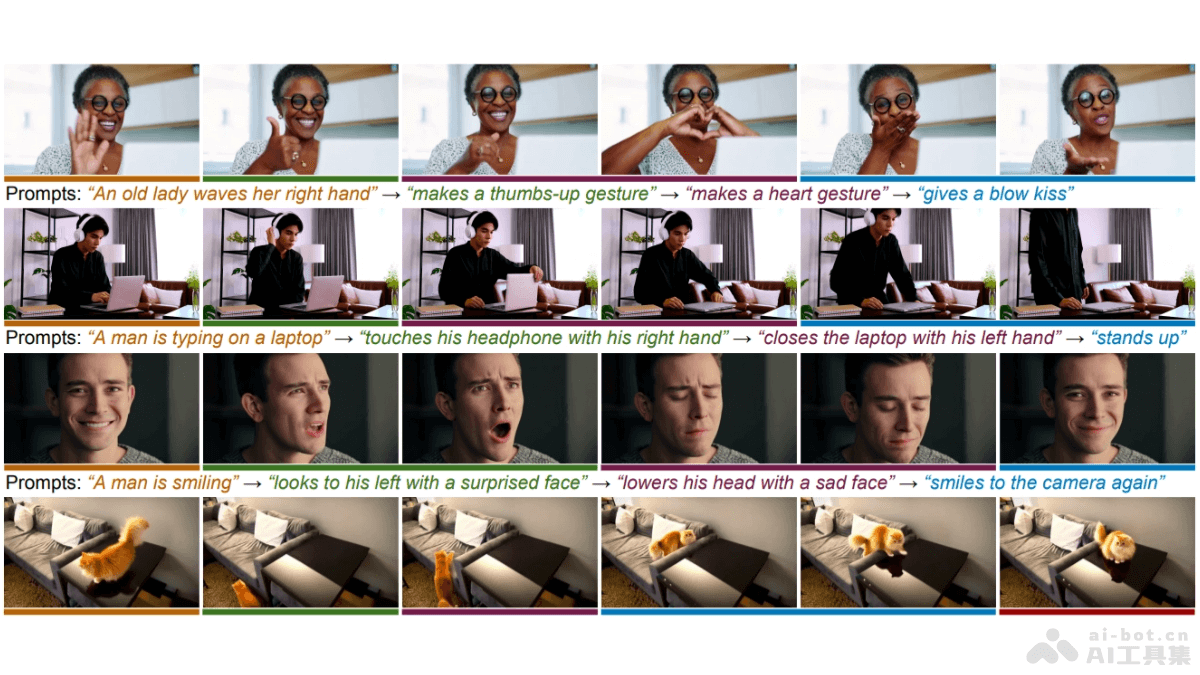
MinT's main features
- Multi-event video generation: Generates videos containing multiple events according to text prompts. Events can be actions, expressions, or daily activities, etc.
- Temporal control: Supports users in specifying the start and end time of each event, achieving precise control over the order and duration of events in the video.
- Coherence preservation: When generating multi-event videos, maintains the coherence of the video content, including consistent themes and backgrounds.
- High-quality video synthesis: Optimizes the model to generate high-quality video content, ensuring the video's dynamism and visual quality.
- LLM-based prompt enhancer: Provides a prompt enhancer based on a large language model (LLM), which can expand short prompts into detailed global and temporal captions to generate richer video content.
MinT's technical principles
- Time-based positional encoding (ReRoPE): Introduces eRoPE, a time-based positional encoding method that guides the model on how to associate text prompts with video frames, ensuring that events occur within the correct time ranges.
- Pretrained video diffusion transformer (DiT): Based on a pretrained latent diffusion transformer (DiT). The transformer encodes video into video tokens based on an encoder and uses a denoising network to generate video.
- Cross-attention for global and temporal captions: Uses two cross-attention layers in each DiT block to process global captions and temporal captions separately, achieving precise control over events.
- Association of event time ranges: Provides temporally localized captions. The model focuses on one event at a time and maintains control over the event's time range during the generation process.
- Scene transition control: Based on a conditioning model, identifies scene transitions in the video and controls the effect of camera transitions in the generated video.
- Prompt enhancement: Uses a large language model (LLM) to expand short text prompts into detailed global captions and temporal captions, supporting users in generating complex video content from simple prompts.
MinT's project addresses
- Project official website:mint-video.github.io
- arXiv technical paper:https://arxiv.org/pdf/2412.05263v1
MinT's application scenarios
- Entertainment industry: Used in the pre-production stage of films and TV series to generate dynamic previews of scripts, helping teams understand the flow of scenes and events.
- Advertising industry: Creates dynamic advertisements. By precisely controlling the timing of product displays in advertisements, it enhances the effectiveness of information delivery.
- Education field: Create educational videos, such as historical reenactments and scientific experiment simulations, to assist learning and understanding of complex concepts through visualization.
- Gaming Industry: Generate story animations and cutscenes in games to enhance the narrative experience of the game.
- News Media: Quickly produce dynamic summary videos of news events to improve the appeal of news reports and the efficiency of information delivery.