
What is MinMo
MinMo is a multimodal large model launched by the FunAudioLLM team at Alibaba Tongyi Lab, focused on achieving seamless speech interaction. MinMo has approximately 8 billion parameters and is based on multi-stage training, learning on 1.4 million hours of diverse speech data and a wide range of speech tasks. MinMo supports controlling the emotion, dialect, and speaking style of generated audio according to user instructions, as well as imitating specific timbres, with a generation efficiency exceeding 90%. MinMo supports full-duplex speech interaction, with a speech-to-text latency of approximately 100 milliseconds and a full-duplex latency of approximately 600 milliseconds in theory and approximately 800 milliseconds in practice, enabling simultaneous two-way communication between the user and the system, making multi-turn conversations more fluid.
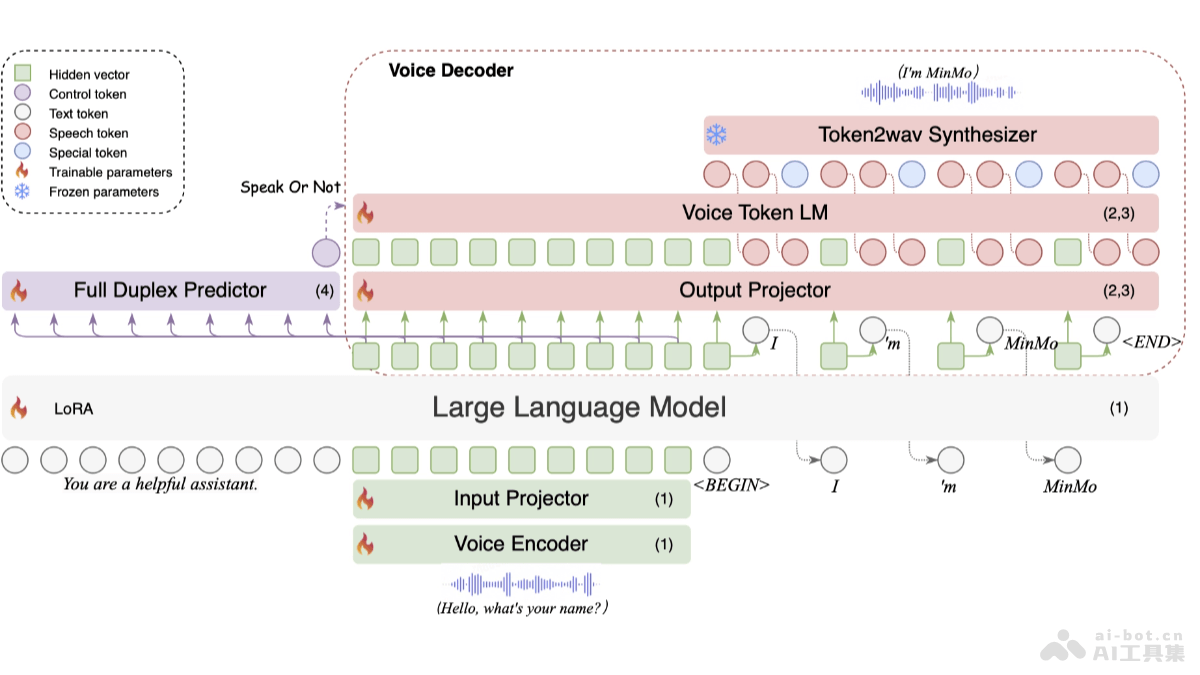
MinMo's Main Features
- Real-time speech conversation: Can conduct speech conversations with users in real time, naturally, and fluidly, understand users' speech instructions, and generate corresponding speech responses.
- Multilingual support: Supports multilingual speech recognition and translation, enabling smooth communication with users in various language environments.
- Emotional expression: Generates speech with specific emotions (such as happiness, sadness, surprise, etc.) according to user instructions.
- Dialects and speaking styles: Supports generating speech in specific dialects (such as Sichuan dialect, Cantonese, etc.) and specific speaking styles (such as fast, slow, etc.).
- Timbre imitation: Imitates specific timbres, making speech interaction more personalized and expressive.
- Full-duplex interaction: Supports users and the system speaking and listening at the same time, achieving more natural and efficient multi-turn conversations, with a speech-to-text latency of approximately 100 milliseconds and a full-duplex latency of approximately 600 milliseconds in theory and approximately 800 milliseconds in practice.
MinMo's Technical Principles
- Multimodal fusion architecture:
- Speech encoder: Based on the pretrained SenseVoice-large encoder module, it provides powerful speech understanding capabilities and supports multilingual speech recognition, emotion recognition, and audio event detection.
- Input projector: Composed of two Transformer layers and one CNN layer, used for dimension alignment and downsampling.
- Large language model: Uses the pretrained Qwen2.5-7B-instruct model because of its outstanding performance on multiple benchmarks.
- Output projector: A single-layer linear module used for dimension alignment.
- Speech token language model: Uses the pretrained CosyVoice 2 LM module to autoregressively generate speech tokens.
- Token2wav synthesizer: Converts speech tokens into mel spectrograms and then into waveforms, supporting real-time audio synthesis.
- Full-duplex predictor: A single-layer Transformer and a linear softmax output layer, used to predict in real time whether to continue the system response or pause processing of user input.
- Multi-stage training strategy:
- Speech-to-text alignment: Based on a large amount of speech data and corresponding text annotations, the model is trained to learn the mapping relationship between speech and text, enabling the model to accurately convert speech into text and laying the foundation for subsequent text understanding and generation.
- Text-to-speech alignment: Enables the model to learn how to convert text into speech, generate natural and fluid speech expressions, and preserve the semantic information and emotional tone of the text.
- Speech-to-Speech Alignment: Further enhance the model's understanding and generation capabilities for speech, enabling the model to interact directly at the speech level and better handle features such as speech prosody and intonation.
- Full-Duplex Interaction Alignment: Simulate real full-duplex interaction scenarios, train the model to accurately perform speech recognition and generation while simultaneously receiving and sending speech signals, and optimize the model's performance in complex interactive environments.
MinMo Project Address
- Project Official Website:https://funaudiollm.github.io/minmo/
- arXiv Technical Paper:https://arxiv.org/pdf/2501.06282
MinMo Application Scenarios
- Intelligent Customer Service: Provide 24*7 multilingual voice support, answer customer questions in real time through interaction, provide personalized services based on emotion recognition, and support full-duplex dialogue to improve efficiency.
- Intelligent Assistant: Control smart home devices, manage schedules, query information, recommend personalized content, and improve the convenience of life and the efficiency of information acquisition.
- Education: Assist language learning, improve participation through interactive teaching, provide personalized plans according to learning progress, and encourage students to learn with emotional support.
- Healthcare: Remote medical consultation, health monitoring reminders, rehabilitation training guidance, emotional support and counseling, improving the accessibility of medical services and the patient experience.
- Intelligent Driving: Voice control of vehicle systems, provision of real-time traffic information, guidance in emergencies, and full-duplex dialogue to improve driving safety and convenience.