
What is MiMo-VL
MiMo-VL is Xiaomi's open-source multimodal large model, composed of a vision encoder, a cross-modal projection layer, and a language model. The vision encoder is based on Qwen2.5-ViT, and the language model is Xiaomi's self-developed MiMo-7B. It adopts a multi-stage pre-training strategy, uses 2.4T tokens of multimodal data, and improves performance through hybrid online reinforcement learning. It performs excellently on tasks such as basic visual understanding, complex reasoning, and GUI interaction. For example, it reaches 66.7% on MMMU-val, surpassing Gemma 3 27B; it reaches 59.4% on OlympiadBench, surpassing 72B models.
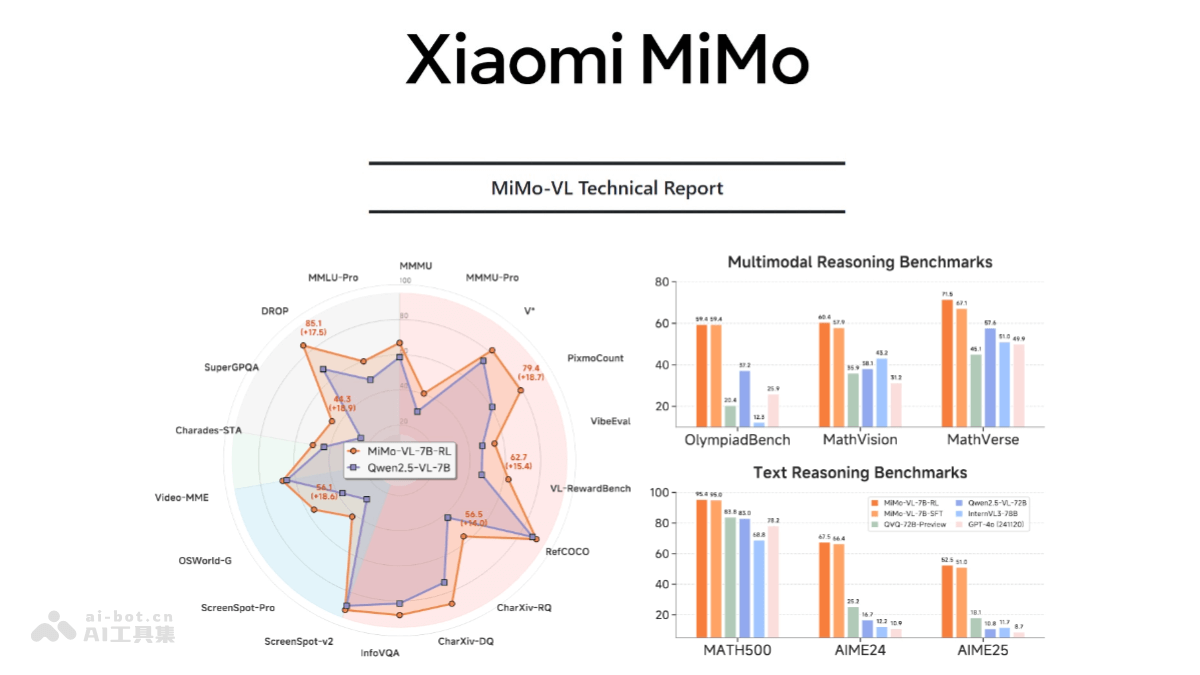
Main Features of MiMo-VL
- Complex Image Reasoning and Question Answering: It can perform reasoning and question answering on complex images, accurately understand image content, and provide reasonable explanations and answers.
- GUI Operation and Interaction: It supports GUI operations of more than 10 steps, and can understand and execute complex graphical user interface operation instructions.
- Video and Language Understanding: It can understand video content and perform reasoning and question answering combined with language.
- Long Document Parsing and Reasoning: It can process long documents and perform complex reasoning and analysis.
- User Experience Optimization: Through the hybrid online reinforcement learning algorithm (MORL), it comprehensively improves the model's reasoning, perception performance, and user experience.
Technical Principles of MiMo-VL
- Vision Encoder: Based on Qwen2.5-ViT, it supports native resolution input and preserves more details.
- Cross-Modal Projection Layer: Uses an MLP structure to align visual and language features.
- Language Model: Adopts Xiaomi's self-developed MiMo-7B base model, specially optimized for complex reasoning.
- Multi-Stage Pre-Training: High-quality multimodal pre-training data was collected, cleaned, and synthesized, covering data types such as image-text pairs, video-text pairs, and GUI operation sequences, totaling 2.4T tokens. By adjusting the proportions of different types of data in stages, it strengthens long-range multimodal reasoning capabilities.
- Four-Stage Pre-Training:
- Projection Layer Warm-Up: Uses image-text pair data, with a sequence length of 8K.
- Vision-Language Alignment: Uses image-text interleaved data, with a sequence length of 8K.
- Multimodal Pre-Training: Uses OCR/video/GUI/reasoning data, with a sequence length of 8K.
- Long-Context SFT: Uses high-resolution images/long documents/long reasoning chains, with a sequence length of 32K.
Project Address of MiMo-VL
- Github Repository:https://github.com/XiaomiMiMo/MiMo-VL
- HuggingFace Model Library:https://huggingface.co/collections/XiaomiMiMo/mimo-vl
Application Scenarios of MiMo-VL
- Intelligent Customer Service: It can complete tasks such as complex image reasoning and question answering, providing users with more intelligent and convenient services.
- Smart Home: Through understanding multimedia data such as family photos and videos, it implements GUI Grounding tasks and improves the efficiency and experience of human-computer interaction.
- Smart Healthcare: Through understanding medical images and texts, it assists doctors in diagnosis and treatment.
- Education: It assists with math problem solving and programming learning, providing solution steps and code examples.
- Scientific Research and Academia: Assist with logical reasoning and algorithm development, helping researchers verify hypotheses and design experiments.